Blog

  • Invoice Numbers Explained: What They Are & How They Work

    Invoice Numbers Explained: What They Are & How They Work

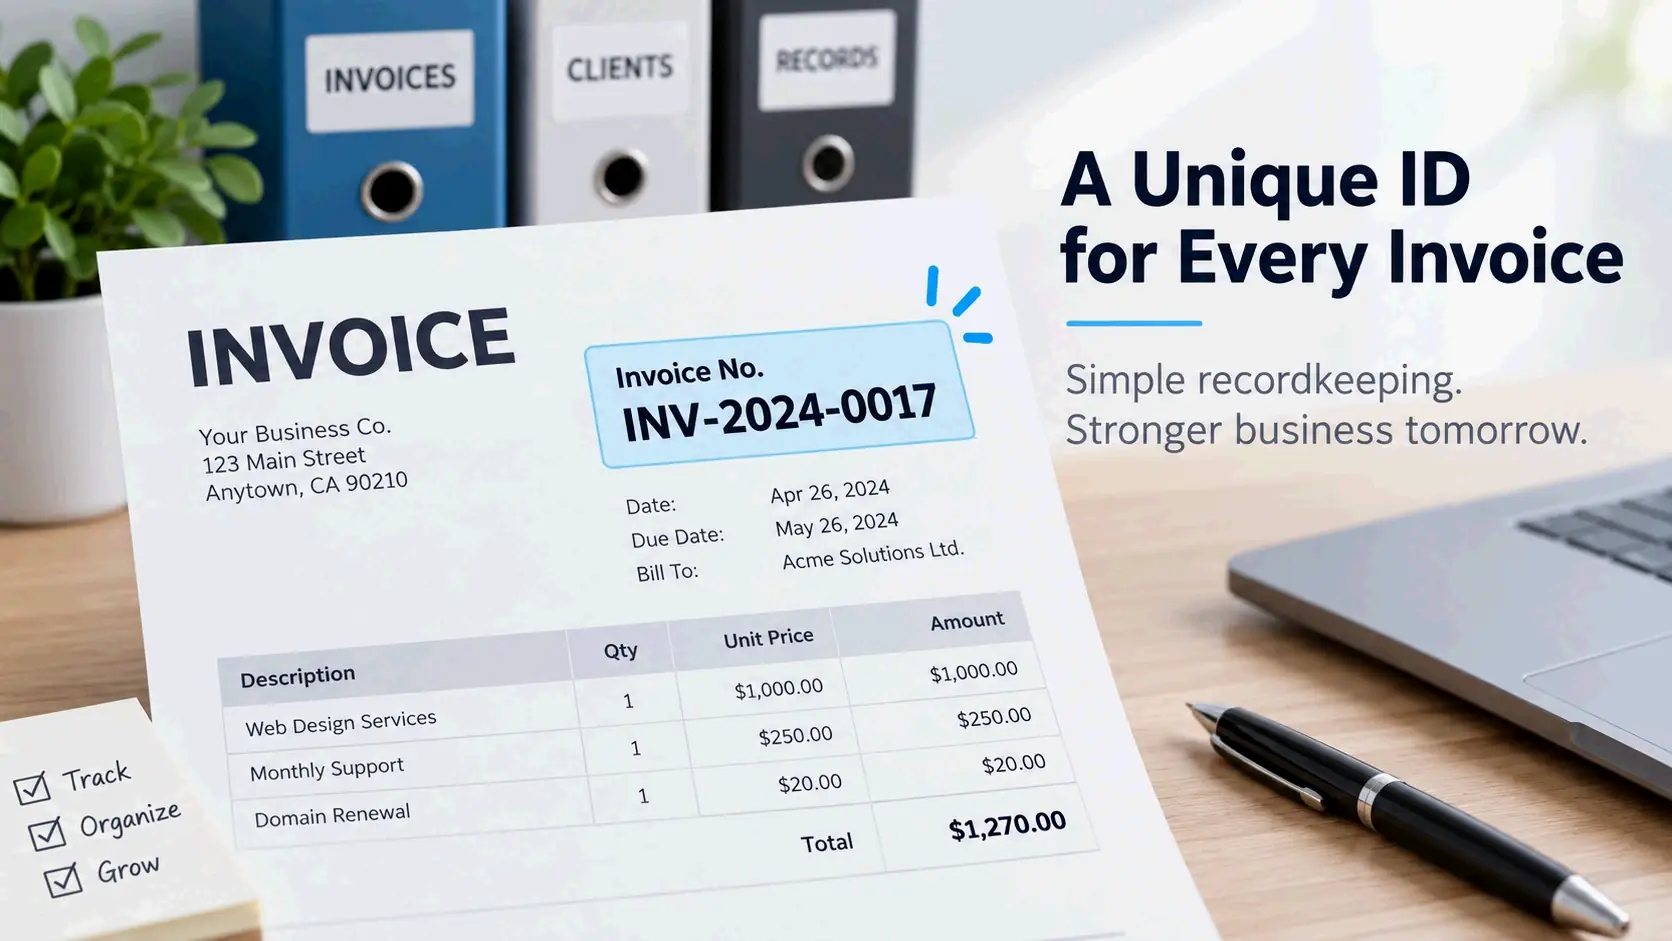
    Unique invoice number as the key to records

    Invoice numbers explained: an invoice number is a unique ID assigned to every invoice you issue. It tracks payments, reconciles records, and keeps you audit-ready. Never reuse, skip, or delete one. The US sets no federally mandated format — but IRS recordkeeping rules still apply.

    What Is an Invoice Number? (And What It Is Not)

    An invoice number is the unique identifier assigned to one specific invoice you issue. It exists so that you, your customer, your bookkeeper, and a tax authority can locate the same transaction without relying on names, dates, or amounts that repeat constantly across a set of books.

    In practice, the invoice number is the primary key of your accounts receivable ledger. When a customer’s payment lands with a memo line, the characters in that memo are the only thing that reliably ties the cash to the invoice it settles. Statrys describes the number as the reference that lets you locate and verify any specific transaction.

    Every invoice number comes down to three components: a prefix, a sequential number, and optionally a date segment, plus zero-padding to keep the digits consistent. The format itself is yours to choose. Uniqueness is not. As Lev Tretyakov, CEO of Fortador USA, puts it: “We always include an invoice number for all sales we make. The invoice number makes it easy to pull up the transaction and provide accurate assistance to our clients.”

    It also helps to know what an invoice number is not. It is not a purchase order number, a quote number, a receipt number, or a credit note number. Each of those is issued by a different party, at a different point in the transaction, for a different purpose.

    The short version: numbering is an internal control, not an aesthetic decision.

    The Three Parts of Every Invoice Number

    A prefix identifies the document type or issuing entity, such as INV for a sales invoice or a branch code in a multi-location business. A date segment places the invoice in the right tax period, which speeds up retrieval during a review. The sequential number is the part that carries the control — it must increase logically and never repeat. Statrys recommends starting at 0001 rather than 1 so the sequence accommodates growth without a mid-year format change.
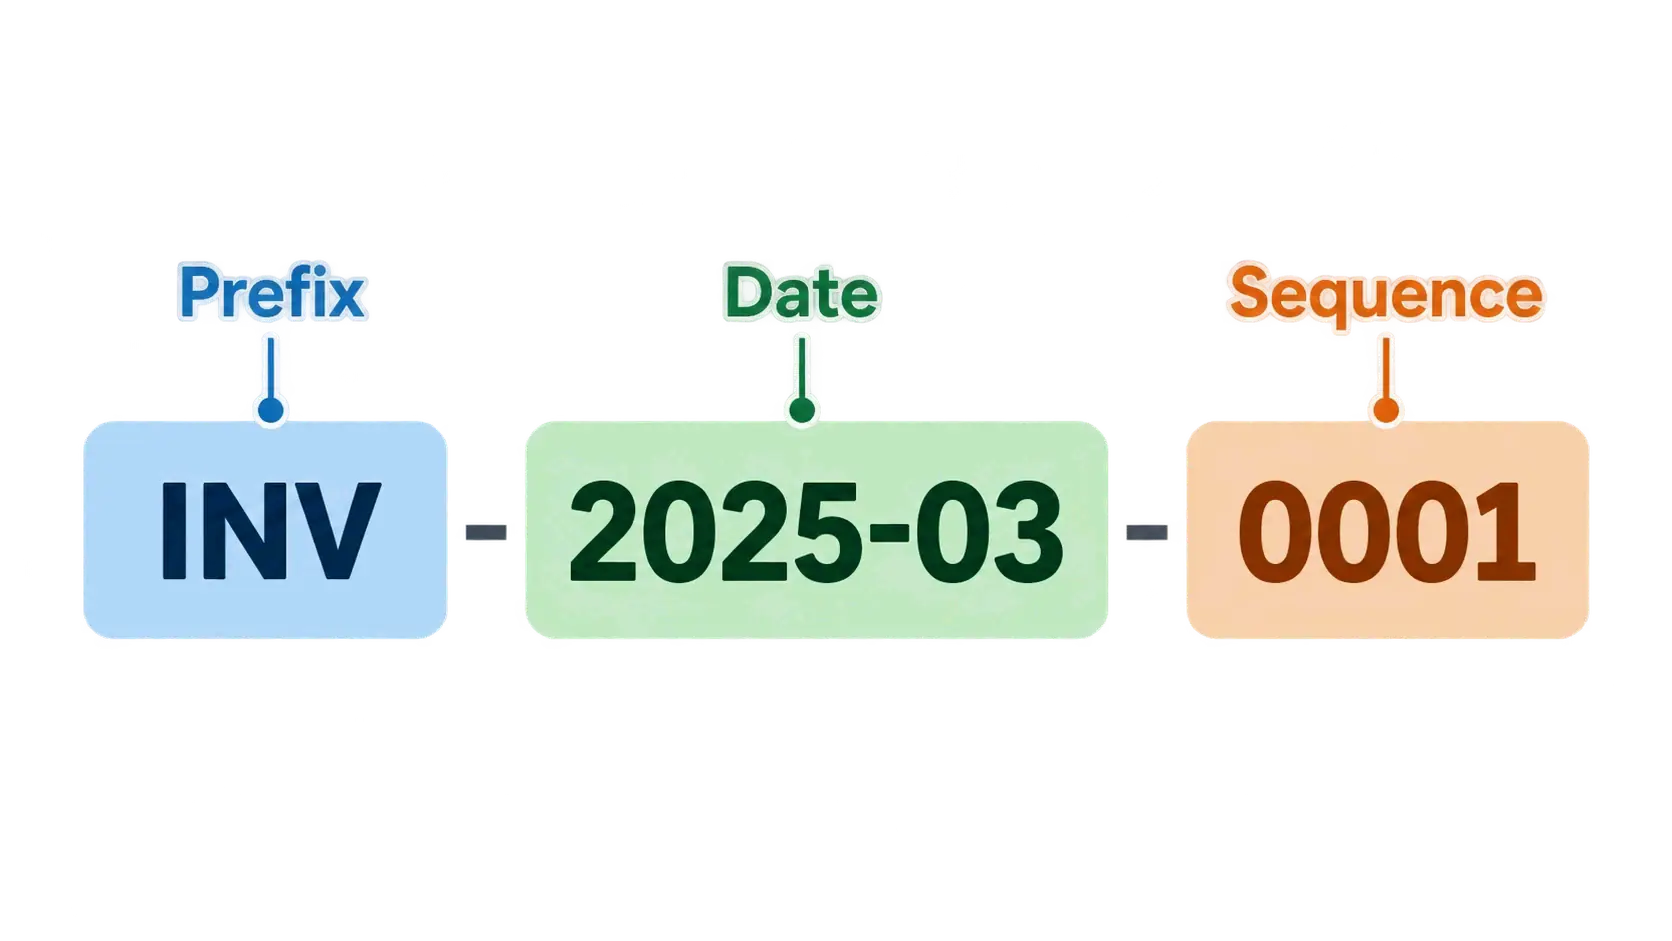
    Three components: prefix, date segment, sequence

    Where the Concept Came From: From Clay Tablets to Internal Controls

    Numbered commercial records are not a modern invention. Around 5,000 years ago, merchants in ancient Mesopotamia used cuneiform script on clay tablets to document trade transactions, including quantities, prices, and the parties involved — and roughly 85% of the cuneiform tablets uncovered at Uruk (3000 BCE) represent economic records, according to Wikipedia’s overview of invoicing. Standardized printed invoice forms emerged with the printing press in the 15th century, and printed invoices with company names and logos were widespread by the 19th century. Digital and automated numbering systems followed in the 20th and 21st centuries.

    The One Rule of Invoice Numbering: Never Reuse, Skip, or Delete

    If you remember one rule from this guide, make it this one: one number maps to one invoice, once and only once. Every serious source on the topic converges on the same principle, and almost every numbering problem traces back to violating it.

    A gap in the sequence is not automatically wrong, but an unexplained gap is a problem. During an audit or an internal review, a missing number raises a specific question — was there an invoice here, and if so, where did it go? Alaan notes that gaps are acceptable only when voided invoices are clearly documented; otherwise the sequence looks incomplete.

    Reusing a number creates a different failure. If two transactions carry the same identifier, a payment that arrives against that number cannot be matched to a specific invoice, and the ambiguity persists in the ledger indefinitely.

    This is why numbering matters beyond bookkeeping mechanics. A continuous, explainable, traceable sequence is itself evidence that your reported revenue is complete. Statrys points out that gaps or duplicate numbers raise questions about whether all income was reported, which matters more if your books are ever reviewed.

    The operational rule that follows is simple: when an invoice is wrong, void it rather than delete it. Keep the number, mark the document void, and note the reason. The number stays in the sequence permanently, even though it will never produce a payment.
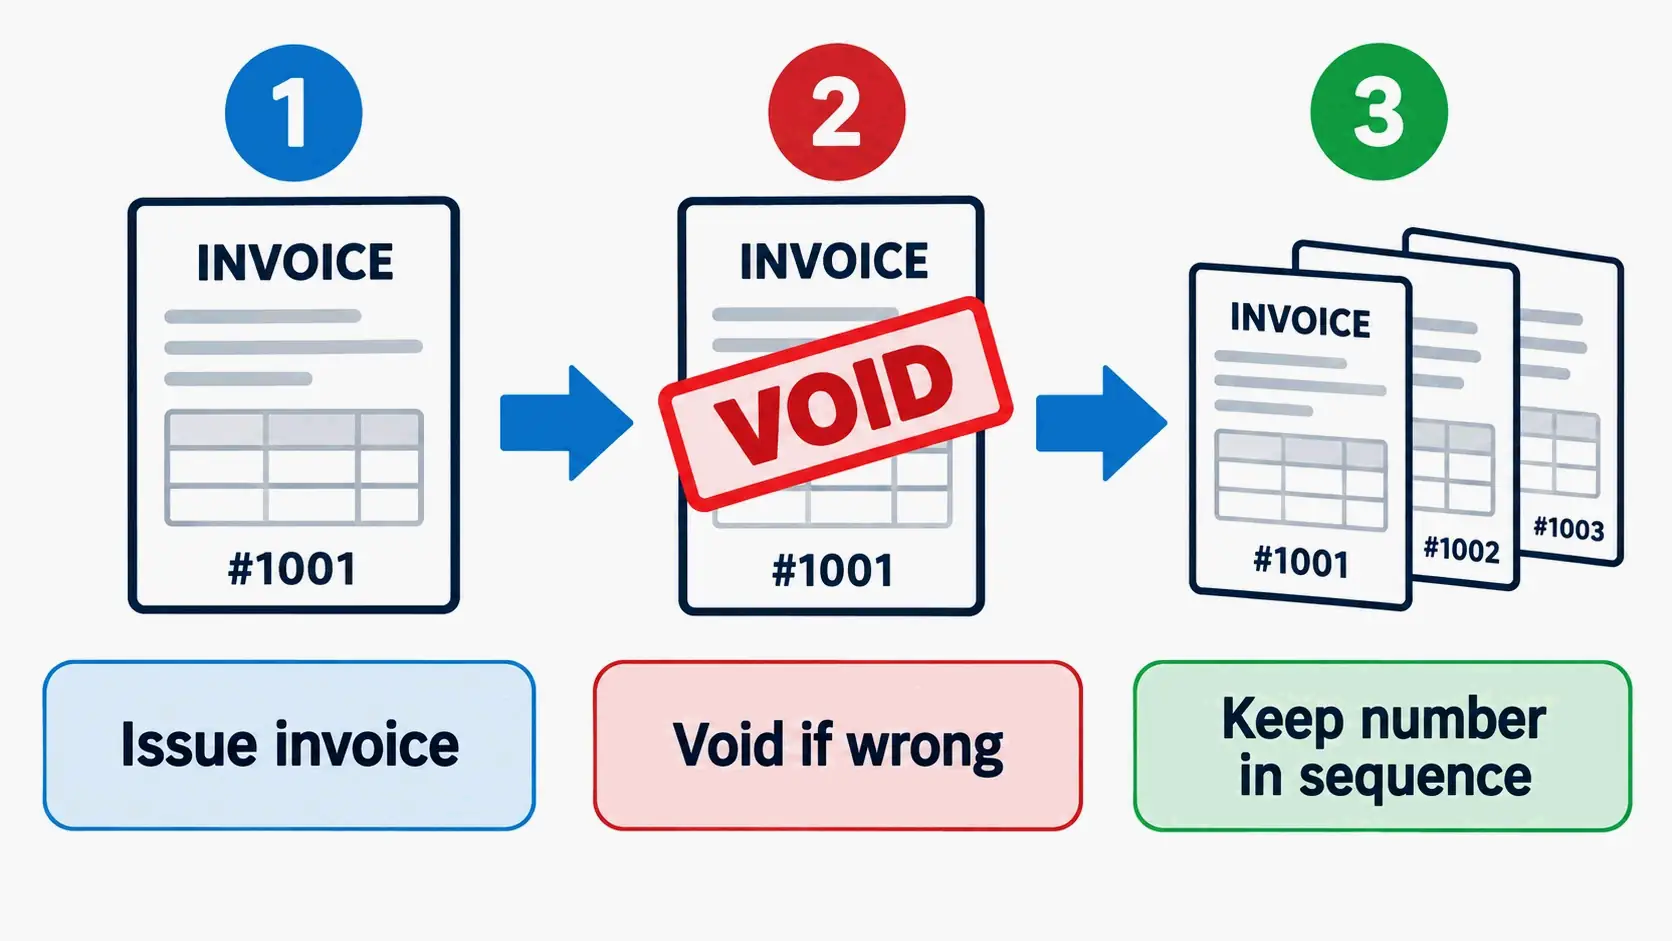
    Void wrong invoices, keep the number

    There is a second baseline rule that keeps your numbering aligned with reality. Lilach Bullock uses a fixed rule of invoicing within 24 hours of work being completed or a milestone being hit, with no exceptions and a calendar reminder attached. That discipline keeps the sequence order identical to the order in which business actually happened.

    Why a Missing Invoice Number Triggers Questions

    A missing number forces anyone reviewing your records to search by customer name, amount, or date instead of by a key. That search is slower and less precise, and it can end in a dead stop. Statrys frames the practical cost this way: when a client references a past transaction, the invoice number is what matches it to a record, and without one you rely on memory or manual searching. Multiply that across several clients and the gap becomes genuinely difficult to resolve.

    Does the IRS Require Invoice Numbers? What US Rules Actually Say

    Here is the answer most US readers are looking for: there is no federal requirement governing invoice number format, prefix, starting value, or continuity. Statrys states plainly that there is no legal requirement in the US to use a specific invoice number format, and no single federal requirement that invoice numbers be strictly sequential — though sequential numbering is standard practice and the default in most accounting software.

    But “no mandated format” is not the same as “no recordkeeping requirement.” IRS Publication 334 (Tax Guide for Small Business) sets out the general record-keeping standards that apply to small business income documentation. An invoice number is what lets those records tie to each other — it is the thread that connects a payment to a sale to a reported figure.

    Retention is the next layer. Ramp notes that the IRS and most tax authorities require keeping invoices for at least three to seven years depending on jurisdiction and business type, and recommends erring longer since digital storage is inexpensive. The practical implication for numbering is that your sequence needs to remain readable and searchable across that entire window, which is an argument against formats you will not be able to reconstruct in five years.

    Why does this matter in a review? A complete sequence requires almost no explanation. Statrys describes the alternative: gaps or duplicate numbers raise questions about whether all income was reported, and this matters more if you are subject to an IRS audit or need to produce invoices on request.

    For a US small business that wants a defensible default with no deliberation required, use INV-YYYY-NNNN, start at 0001, and decide explicitly whether the sequence resets annually or runs continuously. The European Commission’s work on the Late Payment Directive has estimated that non-payment and late payment of invoices cause 25% of corporate bankruptcies — a non-US figure included here only to illustrate why collection discipline carries real economic weight, not to draw conclusions about US requirements.

    One caveat before moving on: this is general information, not tax advice. Confirm your specific recordkeeping and retention obligations with a tax professional.

    Federal vs. State: Where Invoice Number Rules Actually Live

    The federal layer governs income recordkeeping. The state layer is where invoice content requirements are more likely to appear, particularly around sales tax. Because sales tax is administered state by state, the required fields on a sales invoice can differ depending on where you operate and where your customer is. If you sell into multiple states, check the requirements for each jurisdiction you have nexus in rather than assuming one template covers everything — and confirm the specifics with your accountant.

    How Other Jurisdictions Differ (UAE, UK, India, Philippines)

    Other countries make numbering far more prescriptive than the US does, which is useful context for anyone comparing systems or reading international guides. In the UAE, VAT law requires a unique, sequential invoice number on every tax invoice, Alaan explains, and missing or duplicate numbers can trigger audit queries or rejected claims; UAE VAT records must generally be retained for at least five years. In the UK, GOV.UK sets out what an invoice must include for VAT purposes. India’s GST e-invoicing system uses a jurisdiction-specific Invoice Reference Number (IRN), a registration identifier generated for an e-invoice rather than the generic “reference” field on an ordinary bill. In the Philippines, invoicing and tax requirements are administered by the BIR. If you operate across borders, treat numbering as a per-jurisdiction compliance question.

    Invoice Number vs. PO Number vs. Reference Number: A Numbering Identity Table

    The fastest way to eliminate numbering confusion is to separate each identifier by what it points to, who issues it, and when it comes into existence. The table below maps the identifiers that most often get conflated on a single invoice.

    Identifier What it identifies Who issues it When it is generated Where it usually appears Can it be the invoice number?
    Invoice number The invoice itself Seller’s finance or billing system When the invoice is issued Invoice header and accounting record —
    PO number The buyer’s authorized purchase order Customer’s procurement team Before supply or billing Customer PO, cross-referenced on the invoice No
    Reference number A customer, project, contract, job, or internal record Varies by party Varies Invoice header, labeled separately No (it is a different object)
    Credit note / credit memo number An adjustment document Seller’s finance or billing system When the credit is approved Credit note, linked to the original invoice No — use a separate series
    Receipt number Collection of payment Seller’s finance or billing team When payment is received Receipt and collection record No
    Pro forma invoice number A preliminary estimate or quote Seller Before the sale is confirmed Pro forma document No — use a separate series
    Sales order number The seller’s accepted order Sales or order-management team After order acceptance Sales order, fulfillment record, invoice No
    Delivery receipt number Proof or tracking of delivery Warehouse or logistics team At dispatch or delivery Delivery receipt, fulfillment record No
    Payment reference A remittance or bank transaction Customer or bank When payment is sent Remittance advice, bank record No — it identifies the payment event

    The core distinctions are worth stating plainly. A PO number identifies the buyer’s purchase order, and the buyer — not you — supplies it. An invoice reference number connects the invoice to something else useful, such as a customer account, project, job, contract, or order, and does not necessarily identify the invoice itself. A receipt number confirms collection of payment, not the sale. InvoiceAtlas summarizes the relationship well: an invoice can contain both an invoice number and a PO number because each one connects the transaction to a different document, and they are not duplicates.

    If your customer requires a PO number, quote the one they gave you — never substitute an internal reference for it. InvoiceAtlas lists “creating a PO number instead of using the one supplied by the customer” among the most common reference mistakes. If the required PO number is missing, ask the customer’s contact before you send the invoice.

    The Same Document, Two Perspectives: AR and AP

    One party’s invoice is the other party’s bill. From your side of the transaction, the invoice number identifies a receivable you are owed. From your customer’s side, the same number identifies a payable they must clear. Invoice Data Extraction emphasizes that the supplier-issued invoice number is the durable link back to the source document, and that AP teams should record the full value as printed — including prefixes, suffixes, separators, and leading zeros. Changing INV-00417 to 417 makes duplicate detection and supplier queries less reliable because the recorded value no longer matches the source.

    Why Separate Number Series Prevent Downstream Matching Errors

    Credit notes, pro forma invoices, and any other adjustment documents should run in their own series with their own prefixes, such as CN- or PF-. Alaan recommends distinct prefixes for invoices and credit notes to prevent sequence contamination and protect audit clarity. Statrys makes the same case for pro forma invoices: because they are not final billing documents, they should not run in the same sequence as your official invoices. Mixing them creates documents that look like duplicates of legitimate invoices, which is a self-inflicted reconciliation problem.

    Invoice Numbering Formats Explained: Sequential, Date-Based, Client-Coded, Project-Based

    Take a typical format apart once and the rest are variations on the same theme. INV-2026-000127 carries a prefix (INV) that identifies the document type, a year segment (2026) that makes retrieval by tax period straightforward, and a four-digit zero-padded sequence (0127) that supports more than ten thousand invoices per year without changing the number of digits.

    Four approaches cover the overwhelming majority of US small businesses. Sequential numbering increments by one and is the default in most accounting software. Date-based numbering embeds the period in the number. Client-coded numbering attaches a customer or account prefix. Project-based numbering attaches an engagement code. None of these is more compliant than another in the US — the choice depends on how you actually search your records.

    A comparison from Tofu lays out the trade-offs fairly: sequential numbering produces no gaps and audits easily but carries the risk of overlap during system updates; chronological numbering organizes by date but can produce long numbers; alphanumeric formats encode useful detail but require strict format documentation; and fully custom formats adapt to unusual needs at the cost of complexity.

    Approach Example Strength Limitation Best fit
    Sequential INV-0001, INV-0002 Short, system-friendly, easy to audit No period or entity context Single-entity small businesses
    Date-based 2026-04-001 Organizes by tax period Longer references; reset rules must be documented Businesses that reconcile monthly or by tax year
    Client-coded CLIENT01-001 Supports sorting by account Requires a controlled client code list Agencies and consultants with recurring clients
    Project-based PROJ-MKTG-01 Groups invoices by engagement Codes can become lengthy; watch field-length limits Project-based and milestone-billed businesses

    Sequential Numbering: The Default That Audits Easiest

    Sequential numbering is the lowest-friction option and the one most software defaults to. Start at 0001 and increment by one for each invoice. Tofu describes it as well suited to small businesses issuing regular invoices without complex categorization needs, and Statrys recommends starting at 0001 rather than 1 to accommodate growth and present more professionally on client-facing documents. The one weakness to plan around is overlap during system changes or migrations, which is why a documented freeze point matters more than the format itself.

    Date-Based Numbering and the Annual Reset Question

    Date-based numbering embeds the period directly into the identifier, using formats such as 2026-04-001 or YYYYMMDD-XXX. Tofu notes that if you issue multiple invoices on the same day, a numerical suffix distinguishes them. This approach naturalizes annual resets because the year segment already separates one period from another — but it does not remove the need for a written policy. Statrys cautions that switching reset behavior mid-year without documentation creates confusion, and that either a continuous or an annual-reset sequence is acceptable as long as you pick one and stay with it.

    Client-Coded and Project-Based Numbering for Agencies and Multi-Entity Businesses

    Client-coded formats attach a customer prefix, so CLIENT01-001 sorts invoices by account without opening individual files. Project-based formats attach an engagement code so all invoices tied to one piece of work can be pulled together. Tofu illustrates the pattern with formats like CL-001 for a client code or PROJ-A-001 for a project identifier. The governance cost is real: prefix lists need controls so two branches or teams cannot claim the same code, and codes must stay short enough to survive portal, spreadsheet, and API field limits. Set the code list centrally before anyone starts issuing.

    How to Choose and Set Up Your Invoice Numbering System: A 6-Step Framework

    This is a decision path, not a format menu. Answer three questions first: is your business a single entity, multi-branch, multi-client, or project-based? Do you need to retrieve invoices by tax year or accounting period? Who actually assigns numbers, and in what system? Only then pick a format.
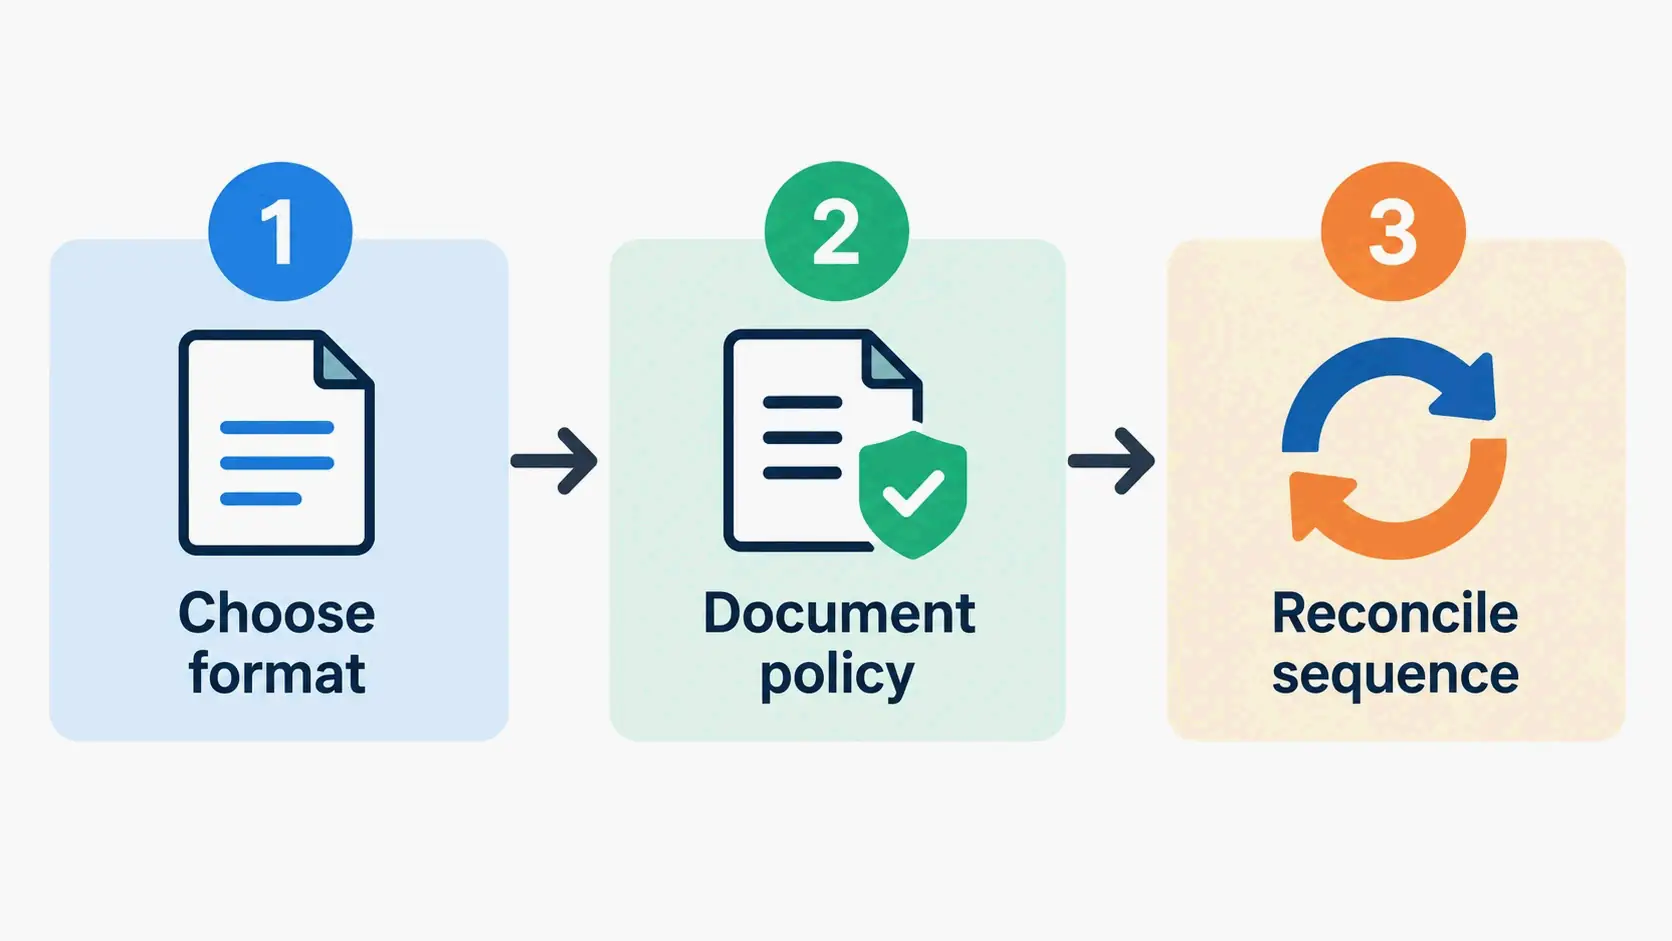
    Choose format, document policy, reconcile sequence

    Step 1 — Choose your prefix. Use prefixes to distinguish document types: INV for sales invoices, CN for credit notes, PF for pro forma documents. Alaan recommends separate prefixes for invoices and credit notes specifically to avoid sequence contamination. If you operate multiple entities or branches, add a controlled entity code and make sure no two entities share it.

    Step 2 — Set the sequence length and zero-padding. Work backward from your maximum expected invoice volume over the next three to five years, then pad to that width. Four digits (0001) covers up to 9,999 invoices per year; five digits covers 99,999. Choosing the width up front avoids the renumbering problem that appears when you outgrow a three-digit sequence in month eight.

    Step 3 — Write down your reset policy. Decide whether the sequence resets at the start of the year or runs continuously forever. If it resets, decide how the reset avoids collisions with historical numbers — the common solution is to embed the year in the identifier rather than returning the running number to 0001. Record the policy in an accounting policy document rather than leaving it as tribal knowledge.

    Step 4 — Document who assigns numbers and when. The assignment rule that matters most is timing: numbers should be generated when the invoice is issued, not when a draft is created. Alaan explains that assigning numbers at the draft stage leaves gaps behind when drafts are abandoned or edited. Lilach Bullock applies the same principle at the workflow level with her rule of invoicing within 24 hours of completion or milestone, which keeps the sequence order consistent with the order work was actually delivered.

    Step 5 — Fix the template. Place the invoice number at the top of the document, next to the issue date and the customer’s details, and keep that position identical across every template version. Statrys notes that most invoicing software and standard templates already place it there by default, which makes it easy for a client to find when paying or asking a question.

    Step 6 — Set a check point. Run a monthly reconciliation of your numbering sequence against your issued invoices. Look for duplicates and unexplained gaps while the month is still open. Alaan recommends periodic sequence reviews to confirm there are no unexplained gaps or duplicates, because early detection avoids painful corrections during an audit.

    Where the Invoice Number Should Appear on the Document

    The invoice number belongs near the top of the invoice, in the header block, close to the issue date and customer information. That placement lets a customer retype it accurately into a payment memo and lets an accounts team find it without scanning the whole document. Whatever template you use, the field label and position should stay consistent — InvoiceAtlas recommends keeping important identifiers together near the main invoice details, with the invoice number shown first, followed by the PO number or other reference, then the invoice date and due date.

    How to Write an Annual Reset Policy (and When Not To Reset)

    A workable reset policy answers four questions in writing: does the sequence reset, on what date, how does the new series avoid colliding with historical numbers, and where is the policy recorded? Alaan confirms that invoice numbers can restart at the beginning of a new financial year provided the reset is clearly documented and the sequence stays continuous within that year. The safer pattern for most US businesses is to embed the year in the identifier — INV-2026-0001 followed by INV-2027-0001 — rather than returning a bare running number to 0001, which risks two open invoices sharing a short reference. If you have open receivables spanning a year end, resetting is usually more trouble than it is worth; run a continuous sequence instead.

    Changing Formats Mid-Year: Freeze Points and Migration Rules

    Changing formats mid-year is one of the most reliable ways to break continuity. Alaan warns that format changes mid-period complicate reconciliation and reporting, and Tofu lists inconsistent formats as a direct cause of sorting errors when invoices stop following the established system.

    If you need to change, set a freeze point — typically the start of a fiscal year or a new quarter — reconcile the old sequence completely before the switch, and never return to the old format. Historical invoices are not renumbered. HashMicro’s numbering guidance describes the migration sequence in practical terms: freeze the cutover point, reconcile open receivables, communicate the new format, and obtain approval for any exceptions before the first invoice leaves the new system.

    Why Invoice Number Discipline Is a Cash Flow Lever, Not Just a Compliance Task

    Numbering and invoice timing are two halves of the same cash flow mechanism. The invoice date starts the clock on your payment terms. The number is what lets the incoming payment be matched to the right invoice once it arrives. Together they determine how long your cash sits outside your account.

    That second half is where the friction shows up. Payment memos are frequently incomplete or mistyped, and a unique, continuous invoice number is the one key that can still reconcile an imperfect payment. Statrys describes the consequence of not having one: tracking outstanding invoices and reconciling payments relies on memory or manual searching, and managing multiple invoices across several clients makes any gap in the sequence significantly harder to resolve.

    The scale of the problem is well documented on the receivables side. According to the 2025 Intuit QuickBooks Small Business Late Payments Report, 56% of small businesses have late payments owed to them. On the more severe end, the European Commission’s Late Payment Directive work has estimated that non-payment and late payment of invoices cause 25% of corporate bankruptcies — a figure from a non-US regulatory context, included here as background on why collection timing has outsized consequences.

    There is a first-person illustration of how much timing alone can cost. Lilach Bullock describes sending invoices a week or more after delivering work while on standard 30-day terms, which stretched what looked like a 30-day cycle to roughly 45 days from delivery to payment. Across five or six clients on rolling retainers, that produced a persistent cash gap of a few thousand pounds every month. The fix was a single rule — invoice within 24 hours of completion or milestone, no exceptions — which pulled almost two weeks back into the cash cycle without changing a single client’s payment terms.

    The same discipline shows up on the service side. As Lev Tretyakov of Fortador USA notes, the invoice number “makes it easy to pull up the transaction and provide accurate assistance to our clients.” Both benefits come from the same underlying habit: a numbering system that stays in step with real business events.

    Common Invoice Numbering Mistakes and How to Repair a Broken Sequence

    Most numbering failures fall into a short list: duplicate numbers, skipped numbers, deleted or edited numbers, voided invoices with no explanation, format changes mid-year, and multiple systems each generating their own numbers. Each has a documented repair path.
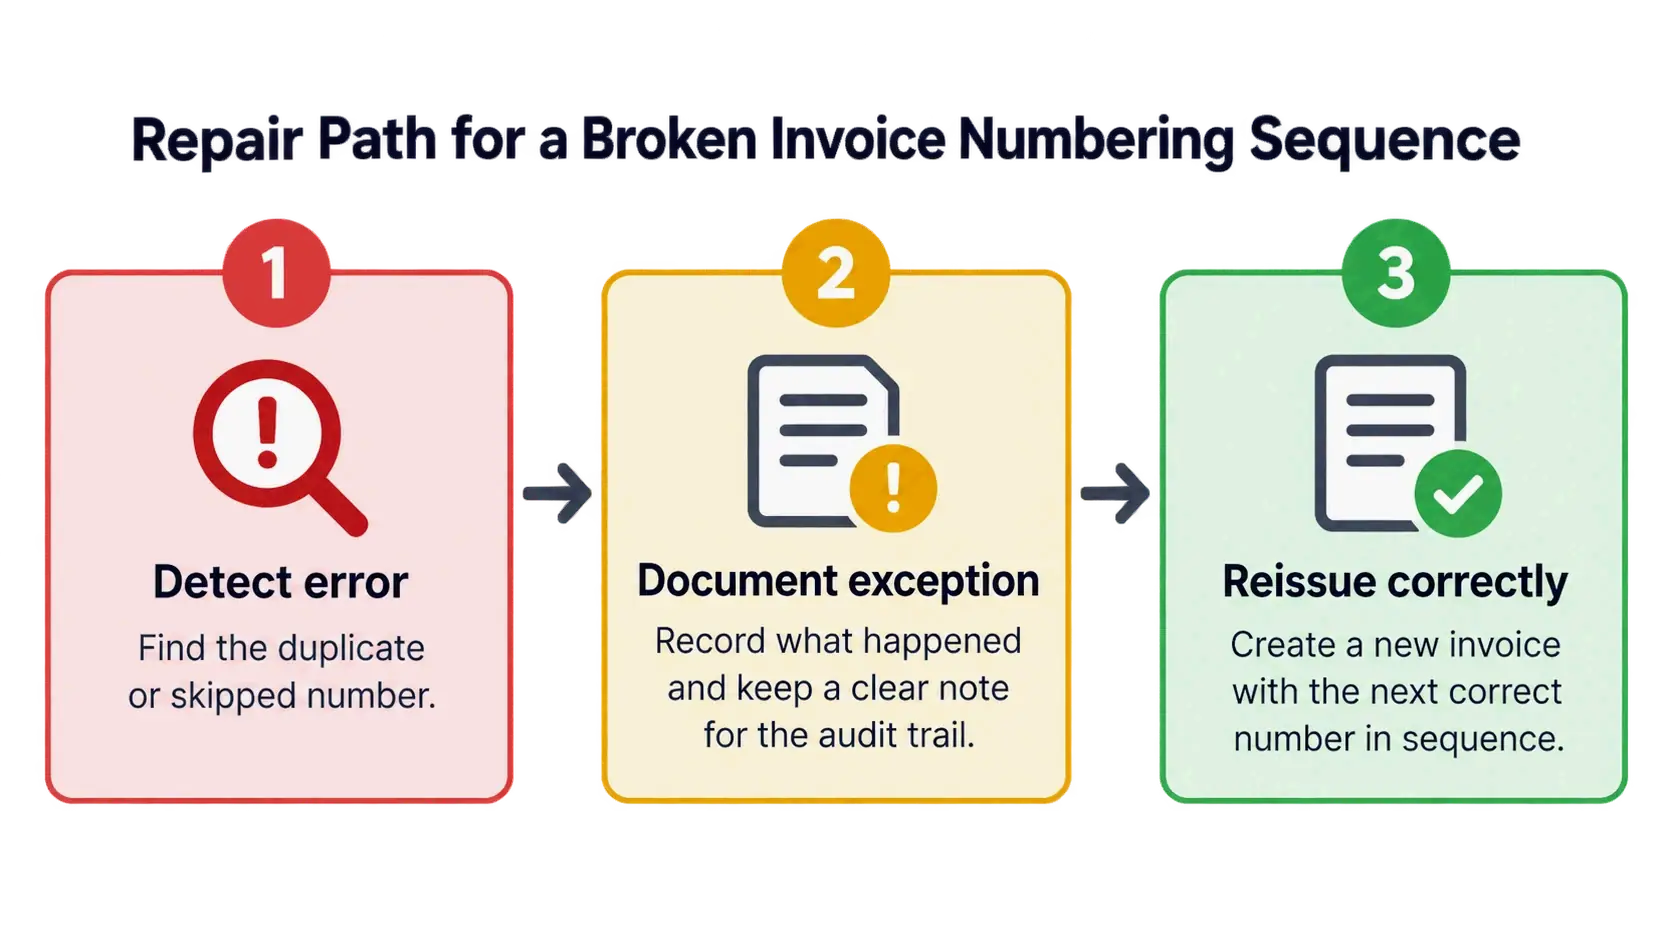
    Detect error, document exception, reissue correctly

    For context on how common invoicing errors are in general, a second-hand compilation cited by Tofu states that 39% of invoices contain errors. That figure is republished without a marked statistical year and should be treated as indicative only — it is useful for illustrating that invoicing errors are not rare, not for drawing conclusions about numbering accuracy.

    I Found a Duplicate Invoice Number — Now What?

    Do not delete either document. First confirm which of the two is the original issued invoice. Keep the original number as it stands. Void the duplicate and reissue the correct invoice under a new number. Note the original number and the reason for the void directly on the record, and retain the correction in your files. Statrys describes the equivalent workflow for a numbering mistake: mark the incorrect invoice as void and note the reason, then issue a corrected invoice with a new number, which keeps records complete and prevents gaps that could raise questions during an accounting review. Never reassign the duplicated number to a new document.

    How to Document a Skipped Number Without Reusing It

    A skipped number needs a written explanation, not a backfill. Do not issue a new invoice into the empty slot, and do not reuse the number for anything else. Instead, record the exception in a log with five fields: the number, the date, the reason (voided, never issued, or system error), the action taken, and the reviewer. HashMicro’s control framework treats missing exception logs as a distinct failure mode, because without one, finance cannot distinguish a legitimate exception from an error. Alaan makes the same point about voided invoices: leave voided numbers in the sequence with a documented reason so reviewers can see the run is complete.

    Migrating from Excel to Invoicing Software Without Breaking the Sequence

    Migration is where duplicate numbers most often appear, because a legacy spreadsheet and a new system can both be generating numbers for a short window. Fix it in order. Freeze the cutover point and stop issuing from the old system. Reconcile the old sequence completely, including any open receivables. Configure the new system’s starting number and format. Preserve legacy references in a separate field rather than overwriting them. Then test duplicate prevention before going live. HashMicro notes that legacy references should be preserved in a separate field when the new system key differs, because legacy and new sequences can collide after cutover.

    Two related traps deserve specific mention. Credit notes and pro forma invoices must run in their own series; if they share the invoice sequence, they will look like duplicates of legitimate invoices. And when multiple systems generate numbers, designate one system of record for number generation and let the others sync rather than create.

    Invoice Automation: How Software Removes Human Numbering Errors

    Automation addresses numbering at the level where the errors actually originate. A system that generates the number at issuance enforces uniqueness by construction, blocks a duplicate before it posts, and holds the sequence intact when several people issue invoices concurrently. Alaan describes automated systems as ensuring numbers are assigned once and only once, sequences remain intact across users and departments, and the same number flows into accounting tools and reports.

    Three error classes largely disappear with automation: manual duplicates, format drift between team members, and skipped or never-issued numbers caused by draft-stage assignment. What remains is a different set of exceptions — data migration leftovers, multiple entities sharing a sequence they should not share, and manual overrides of system-generated numbers. Those are governance problems, not software problems, and they need policy rather than a feature.

    Buyer-side cost is worth understanding too, because it explains why large customers care how you number. HashMicro cites Ardent Partners’ 2025 global benchmark, which reported a 22% average invoice exception rate — a figure that shows how often invoices fail to process cleanly on the receiving end. Inconsistent or ambiguous references contribute to that failure rate, which is why enterprise AP teams often require a valid PO number and a clear invoice number on every document they receive.

    What to Look For in Invoicing Software

    Evaluate numbering capability with specific questions rather than a feature tour. Does the system support custom prefixes and zero-padded sequences without manual formatting? Can it share a sequence across entities, or isolate one per entity where that is required? Does it detect duplicates at entry rather than at month-end? Does it keep an audit history showing who issued, voided, or changed a number, and does it prevent edits to issued references? HashMicro recommends restricting manual edits, deletion, backdating, and sequence changes through role-based access, and testing the full workflow — including a duplicate attempt the system must reject and a cancelled document whose reference never returns — before committing to a vendor.

    Invoice Numbers in E-Invoicing Standards

    If you ever exchange invoices in structured electronic formats, the invoice number becomes a data field with defined transmission rules rather than a visible label. Wikipedia’s overview of invoicing notes that the United Nations EDIFACT “INVOIC” standard includes standard codes for transmitting header information common to the entire invoice as well as line-item detail, and can also carry credit and debit memos. XML-based standards include the UN/CEFACT cross industry invoice and OASIS Universal Business Language (UBL), which is used in public-sector implementations including Denmark, with further implementations in Italy, Spain, and the Netherlands, and the PEPPOL framework for European public procurement. ISDOC was developed in the Czech Republic as a universal electronic invoice format.

    There is also a process model that bypasses invoices altogether for some transactions. Evaluated Receipt Settlement (ERS) pays from the packing slip rather than a separate invoice: the supplier ships against an advance shipping notice, and the purchaser confirms the corresponding purchase order or contract, verifies the goods, and pays. If your customers use ERS, your internal numbering still governs your own records even though no invoice number travels with the payment. Because public documentation on e-invoicing standards ages quickly, verify current requirements against the standards body or your customer’s specification rather than a secondary summary.

    Conclusion

    Invoice numbering is an internal control, not a formatting preference. A unique, continuous, explainable sequence makes payment matching faster and audit questions rarer — and in the US, the real constraint is not the format but whether your records can be traced and reconciled. Three actions to take today: write down your format and reset policy, including prefixes and zero-padding; pin the invoice number to the top of every template and commit to invoicing within 24 hours of completion or milestone; then run one continuity reconciliation and log every existing duplicate and gap in an exception file.

    FAQ

    Does the IRS require invoice numbers on invoices?

    No. There is no federal requirement for invoice number format or continuity. However, IRS Publication 334 requires businesses to keep records supporting income and expenses, and invoice numbers are what let those records cross-reference each other. Some state sales tax rules impose additional invoice field requirements, so check the rules for states where you operate.

    Can I reset my invoice numbers at the start of a new tax year?

    Yes, but there is no single mandatory US rule — what matters is writing the policy down and applying it consistently. Alaan notes that a reset is acceptable when clearly documented and the sequence stays continuous within the year. A safer pattern for most businesses is embedding the year in the identifier, such as INV-2026-0001, rather than returning the running number to 0001 and risking collisions with open historical invoices.

    What should I do if I skip or duplicate an invoice number?

    For a duplicate, confirm the original, void the duplicate, and reissue under a new number while recording the original number and reason. For a skip, do not backfill or reuse the number — document it in an exception log with the date, reason, and reviewer. Both cases need a written trail so the sequence stays explainable during any review.

    Is an invoice number the same as a receipt number?

    No. An invoice number identifies a request for payment; a receipt number identifies confirmation that payment was received. Statrys describes them as different document types serving different purposes that both belong in your recordkeeping system. Many systems generate the receipt number separately, so store them in distinct fields.

    Can two different suppliers use the same invoice number?

    Yes. Uniqueness is only required within a single issuing entity — Alaan confirms invoice numbers only need to be unique per supplier, not across different businesses. That is why buyer systems typically identify an invoice using the combination of supplier plus invoice number, and why enterprise customers require your business identifier and invoice number to appear together.

    Where should the invoice number appear on an invoice?

    Place it in the header, near the invoice date and the customer’s details. Statrys notes that most invoicing software and standard templates position it there by default, which makes it easy for a client to locate when paying. Keep the field label and position identical across every template version you use.
  • Discord File Size Limit 2026: 20MB Cap and What to Do

    Discord File Size Limit 2026: 20MB Cap and What to Do

    Header: Discord upload limit tiers in 2026

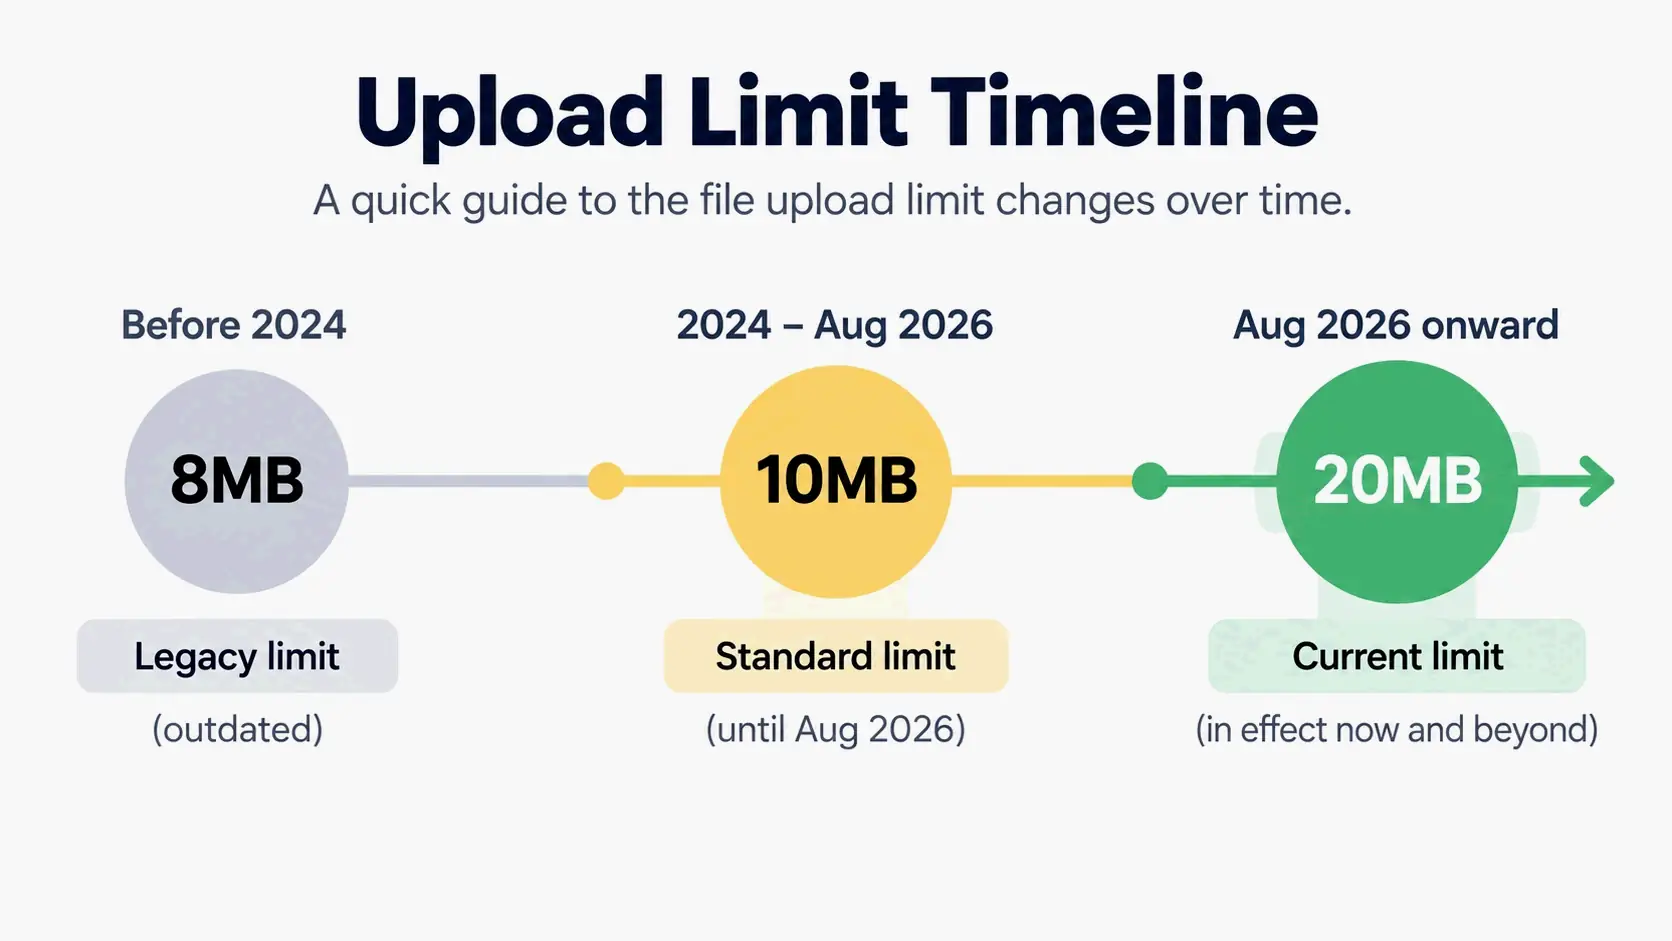
    The Discord File Size Limit 2026 is 20MB per file for free accounts, up from 10MB in August 2026. Nitro Basic raises that to 50MB, Nitro goes up to 500MB, and a server Boost lifts the cap for the whole server. The 8MB, 10MB, and 25MB numbers still floating around online are out of date.

    Discord File Size Limit in 2026: 20MB Free, 500MB With Nitro

    The current limit for a free, non-Nitro account is 20MB per file, effective August 2026 and up from the old 10MB ceiling. As the Discord File Attachments FAQ puts it, “for non-Nitro subscribers, the maximum file upload is 20MB.” The same page also says Discord is “currently experimenting with various file upload size limits,” which is why a small number of accounts may see a different number in the app.

    Paid tiers raise the ceiling. Nitro Basic takes the per-file limit to 50MB, and full Nitro supports uploads up to 500MB, according to the same Discord support docs. Server Boost works separately: it changes the limit for the entire server, not just for you. Level 2 is 50MB and Level 3 is 100MB — Section 3 covers that in detail.

    Discord’s developer docs back up the consumer-facing numbers. The Discord API reference says “the file upload size limit applies to each file in a request. The default limit is 20 MiB for all users, but may be higher for users depending on their Nitro status or by the server’s Boost Tier.” When two independently maintained sources land on the same figure, that’s the strongest signal 20MB is the real baseline in 2026.

    All current Discord upload limits at a glance

    Access type Per-file upload limit Scope
    Free account 20MB Account-wide (servers + DMs)
    Nitro Basic 50MB Account-wide
    Nitro Up to 500MB Account-wide
    Server Boost Level 2 50MB Server-wide (all members)
    Server Boost Level 3 100MB Server-wide (all members)

    The 20MB baseline is the number to compare against when a file fails. Anything below it should upload without a paid plan, as long as the channel and server also allow the file.

    Per file, not per message — and why that matters

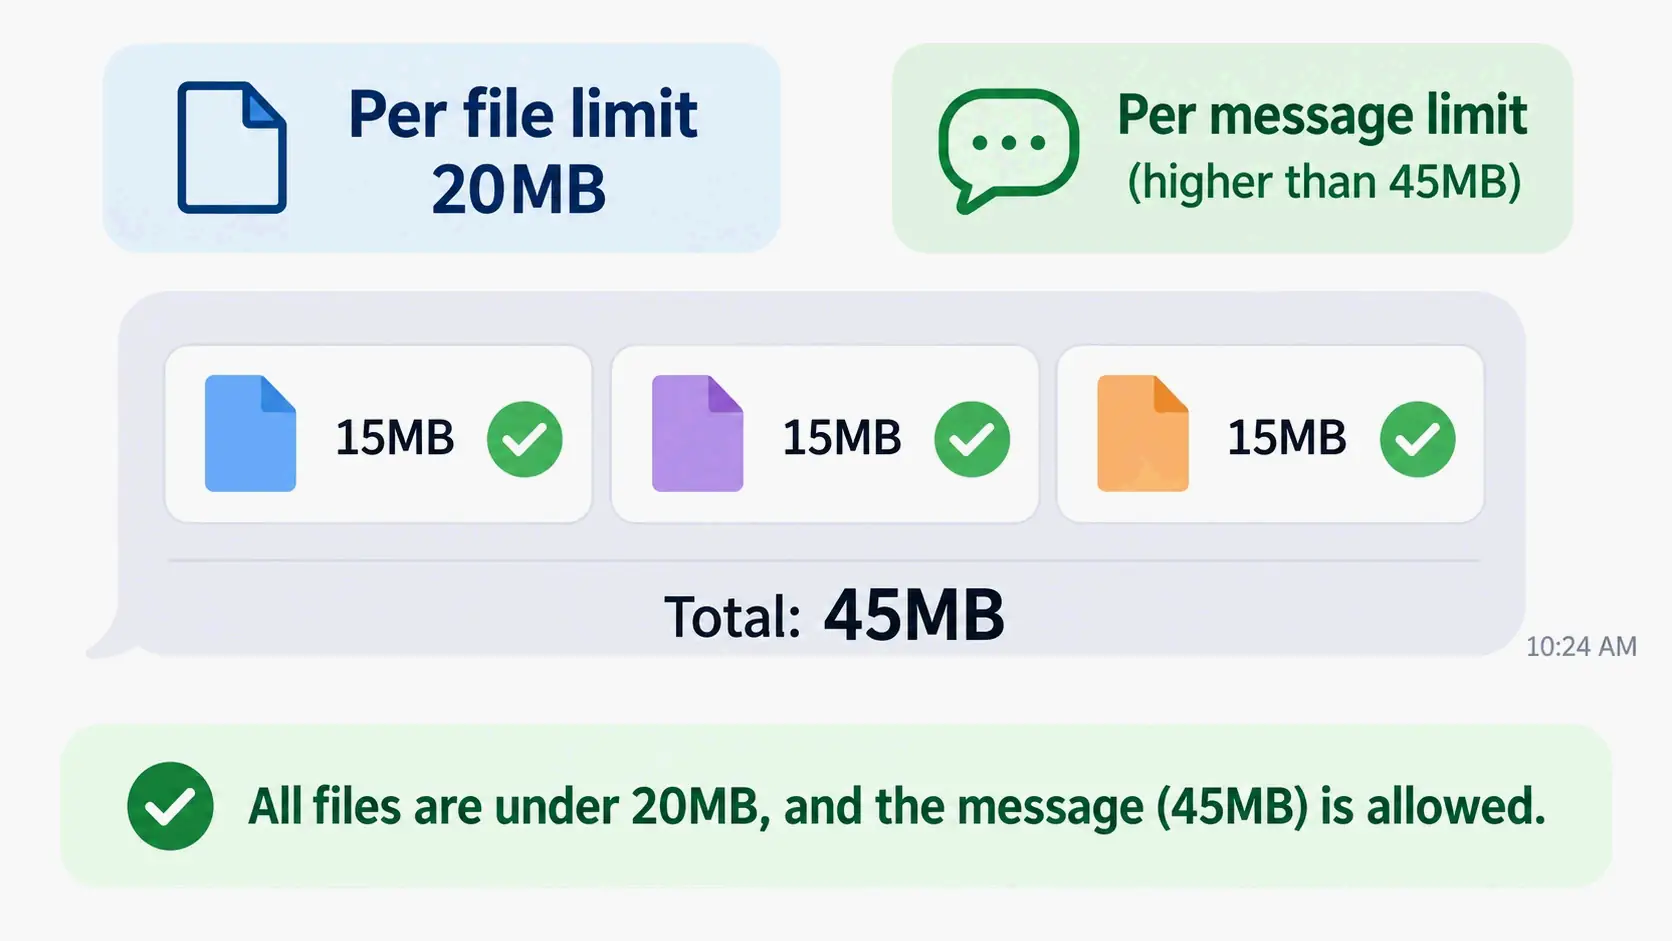
    The limit applies per file, not per message. A free user can attach several files in one message, and each one is measured on its own. Three 15MB files in a single message add up to 45MB, but they pass fine because no single file crosses the 20MB line.

    That distinction changes what “too big” means. When an upload is rejected, it’s the single attachment that’s over the cap, not the whole message. The same rule applies at every tier: Nitro and Server Boost raise the per-file ceiling, not the number of files you can send.

    Per-file limit visual: three 15MB files pass together

    Why Do 8MB, 10MB, and 25MB Still Appear? A Discord Upload Limit Timeline

    Figure Effective period Status in 2026
    ~8MB Legacy era Out of date
    10MB Until August 2026 Replaced by 20MB
    20MB From August 2026 Current free limit
    25MB Undated Conflicts with Discord’s documentation

    Timeline from 8MB and 10MB to current 20MB

    The confusion is mostly a search-decay problem. Older articles that were never updated still rank for upload-limit searches, and some of them quote a stale number in the headline while linking to Discord’s current Help Center page in the body. The mismatch looks authoritative even though the two halves of the page disagree.

    Discord’s own content isn’t perfectly consistent either. The GitHub issue tracking the Cove video downloader bot points out that “Support caps article still documents server Level 0/1 as 10MB in places; the live free-user/default behaviour is 20MB as of August 2026.” When the documentation and the live app disagree, treat the in-app number as the tiebreaker — that’s what the server actually enforces.

    The 10MB legacy limit (pre-August 2026) and why it is still everywhere

    Until August 2026, 10MB was the correct free upload limit, and a huge number of tutorials, forum posts, and bot configs were built around it. Discord’s August 2026 update confirmation says the free upload limit was raised from 10MB to 20MB in a platform-wide change, not a limited test. According to TechJournal, Discord confirmed the increase in its September 8, 2026 patch notes and said the larger limit applies across all platforms, including desktop and mobile.

    That same release batch shipped client performance updates, which helps date the change window. Discord reported its mobile apps moved to React Native 0.86 with roughly 5% lower average CPU use and about 5% faster average launch times, and its desktop app moved to Electron 42 with roughly 17% better p50 CPU usage alongside an approximately 4% p50 memory regression. These are company-reported averages, not independent benchmarks.

    Where the 8MB and 25MB figures came from

    The 8MB figure lives on in GIF-specific content. A 2026 reference page from BulkPicTools still lists 8MB as the free limit and even claims 10MB is the outdated number. That page is wrong about the current free chat limit — Discord’s Help Center says 20MB — but the 8MB number does describe something else: it’s the profile avatar and banner asset limit for Nitro users, not the per-file chat upload limit.

    The 25MB figure shows up in third-party guides such as transientfiles.com, which states “on a free account that’s 25 MB.” That number doesn’t match Discord’s Help Center or its API reference and shouldn’t be treated as fact. Put it plainly: any page citing 8MB or 10MB as the current free chat limit in 2026 is wrong, and 25MB should be treated as an unverified claim.

    Which Limit Applies to You? Account Tier × Server Boost × Channel

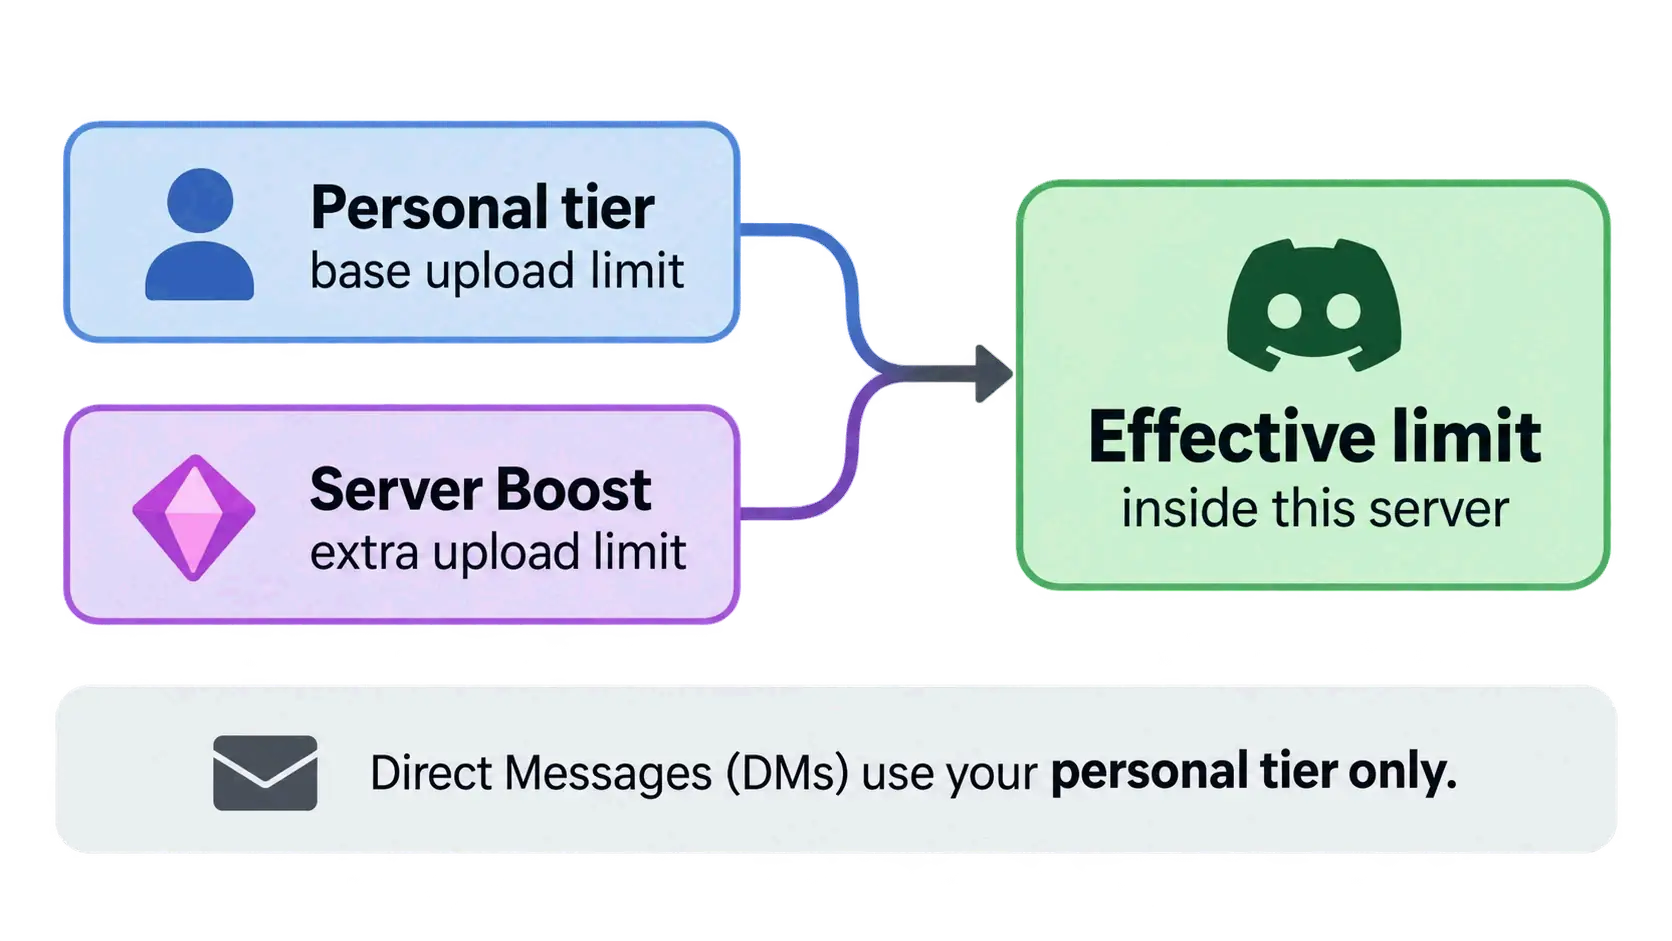
    Four layers decide the real ceiling: your account tier, the server’s Boost level, the surface you’re posting on (server channel vs. DM), and where Discord checks the size. The effective limit is usually the higher of your personal tier and the server’s Boost tier, but only inside that server.

    Personal tier plus server Boost determines effective limit

    Server Boost lifts the cap for everyone in that server. At Level 2, the server-wide limit is 50MB; at Level 3, it’s 100MB. A free account posting inside a Level 3 server can upload a 100MB file that would fail in an unboosted server. A Nitro or Nitro Basic subscriber keeps their personal ceiling in every server and in DMs — Boost doesn’t lower a paid tier.

    DMs follow the personal account limit only. Server Boost never applies there, so a Level 3 server’s 100MB ceiling disappears the moment you open a direct message. A Nitro subscriber in an unboosted server still keeps their 50MB or 500MB personal limit in that server and in DMs.

    Below the Boost tiers, the documentation is genuinely inconsistent. Some official passages still list 10MB at Boost Level 0/1 while the live free default is 20MB. Bot developers working against these tiers often leave about 1MB of headroom to absorb rounding and encoding overhead — a pattern visible in the Cove bot repository, which uses 49.0MB for Level 2 and 99.0MB for Level 3, and proposed moving the Level 0/1 margin from 9.5MB to 19.5MB after the August 2026 change.

    To confirm your own current limit rather than trust any published table — including this one — check the original file size in your OS, compare it against your account tier and the server’s Boost level, and try the upload. If it fails, Discord’s error message tells you whether size is the blocker. The Help Center’s core point is simple: the number shown in the app is the one that counts.

    Scenario: free account inside a Level 3 boosted server

    You have no Nitro. The server you’re posting in has reached Boost Level 3. In that server’s text channels, you can upload files up to 100MB — the same ceiling a paying subscriber would get from Boost alone. Your personal free limit of 20MB doesn’t restrict you here, because the server-wide Boost value is higher.

    The moment you leave that server, you’re back to 20MB. Post the same 100MB file in a DM or in an unboosted server and it will be rejected. The boosted ceiling belongs to the server, not your account.

    Scenario: Nitro subscriber in a server with no Boost (and in DMs)

    You pay for Nitro. You’re posting in a server with no Boost at all. Your personal ceiling of up to 500MB applies, and the server’s lack of Boost doesn’t reduce it. The same goes for DMs, where only your account tier matters.

    If that unboosted server also has channel-level restrictions — a missing “Attach Files” permission, for example — the size limit is irrelevant; the file won’t go through at any size. Size and permission are separate gates.

    How to confirm your own current limit in the app

    Discord’s experiment with upload limits means a small number of accounts don’t match the published table. The practical check is to look at the file size before you send. On Windows, right-click the file and open Properties; on macOS, right-click and choose Get Info; on mobile, open the file manager and tap the file for details. Compare that number against your account tier and the server’s Boost level, then send.

    If a file under your expected limit still fails, the fastest diagnostic is to try the same file on desktop, where the pre-compression check has always applied. Discord’s Help Center notes mobile was moved to the same pre-compression check desktop uses, so any device-specific gap should now be narrow.

    How to Send Files Larger Than 20MB on Discord

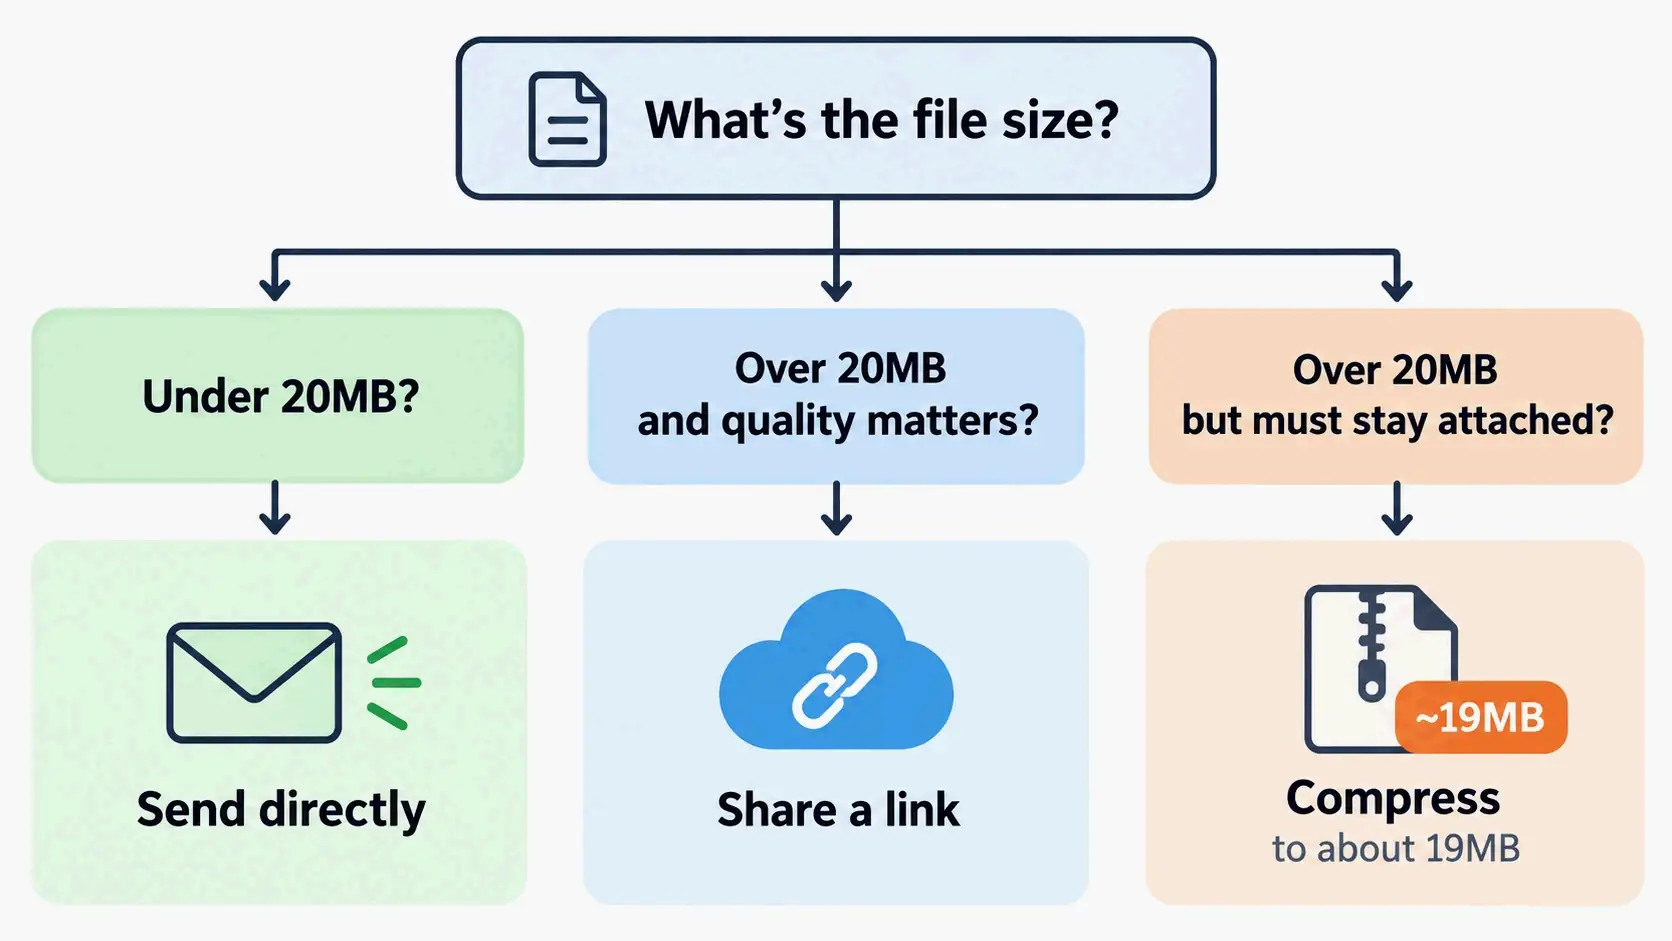
    Start with a three-branch triage before touching any tool. Branch A: the original file is at or under 20MB — just send it, and if it still fails, jump to Section 5. Branch B: the file is bigger and quality matters — share a link. Branch C: the file must live inside Discord as an attachment — compress to roughly 19MB.

    Three-branch triage for sending over 20MB

    Check the ORIGINAL file size first. Since August 2026, Discord compares against the pre-compression size on both desktop and mobile, so guessing wastes attempts. The starting threshold for a free account is the 20MB per-file baseline documented in the Discord File Attachments FAQ.

    Branch 1: Compress to about 19MB (FFmpeg, HandBrake, 7-Zip)

    A cross-platform comparison checked on September 9, 2026 by SqueezeVid lists Discord’s practical target as 19MB at 720p — about 1MB of headroom under the documented free limit. That margin absorbs container overhead and rounding so the file doesn’t land on the wrong side of the cap.

    The most reproducible route is FFmpeg. A test published by DisCoRibute on September 13, 2026, run with FFmpeg 7.0.2-static on Ubuntu 24.04.4 LTS, took a generated 20-second 1920 × 1080 clip and produced this result:

    ffmpeg -i "input.mp4" -vf "scale=1280:-2" -c:v libx264 -b:v 1800k -c:a aac -b:a 96k -movflags +faststart "discord-video.mp4"
    

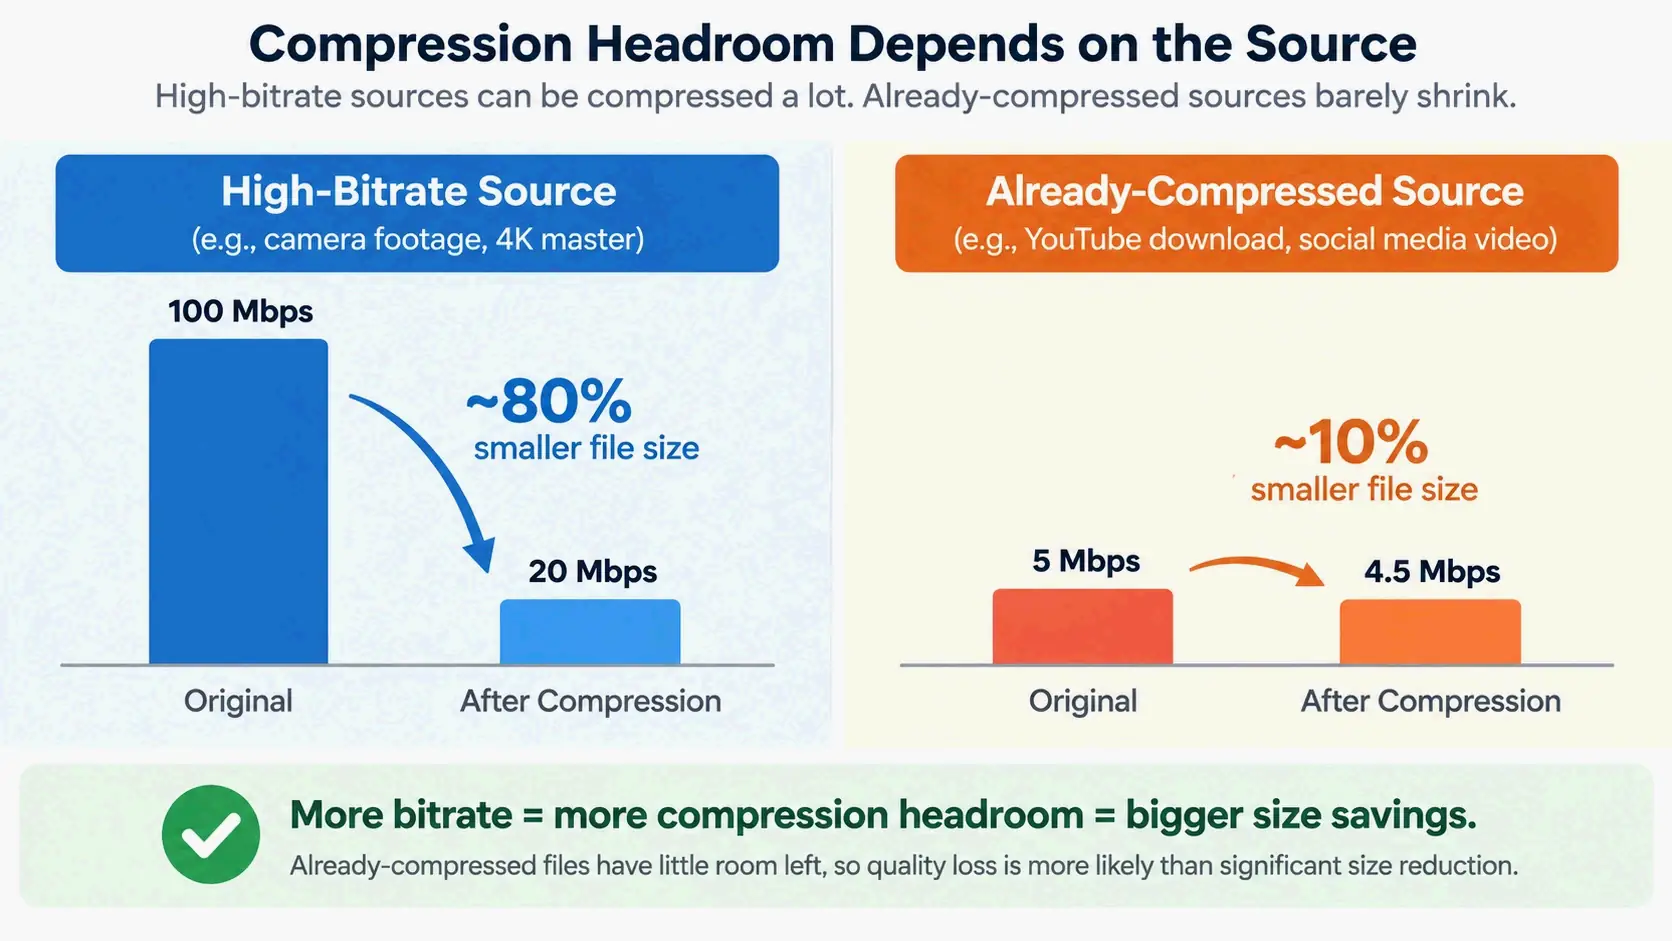
    The source file was 85,414,421 bytes. The exported discord-video.mp4 was 4,801,249 bytes, about 4.8MB, and it uploaded to Discord successfully. The parameters are a starting point, not a guarantee — a longer or more complex clip will land higher, and if the output is still too large the same source recommends lowering the bitrate and exporting again with a new filename. For the framework behind those settings — codec choice, CRF, bitrate budgeting — see how to compress a video without losing quality.

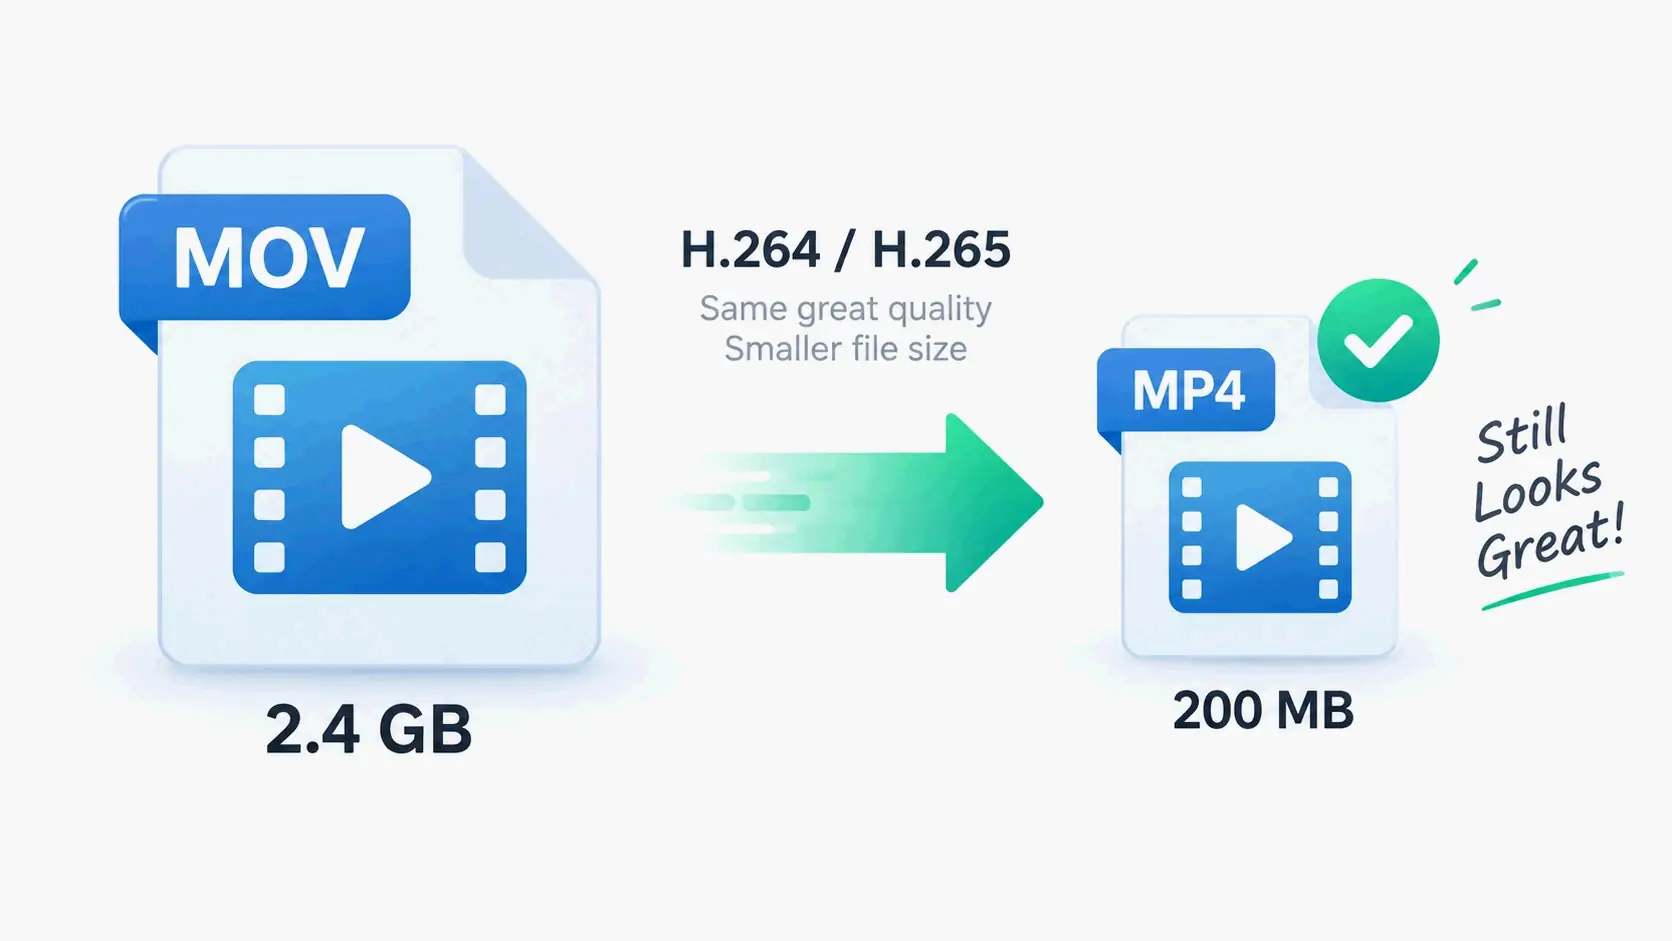
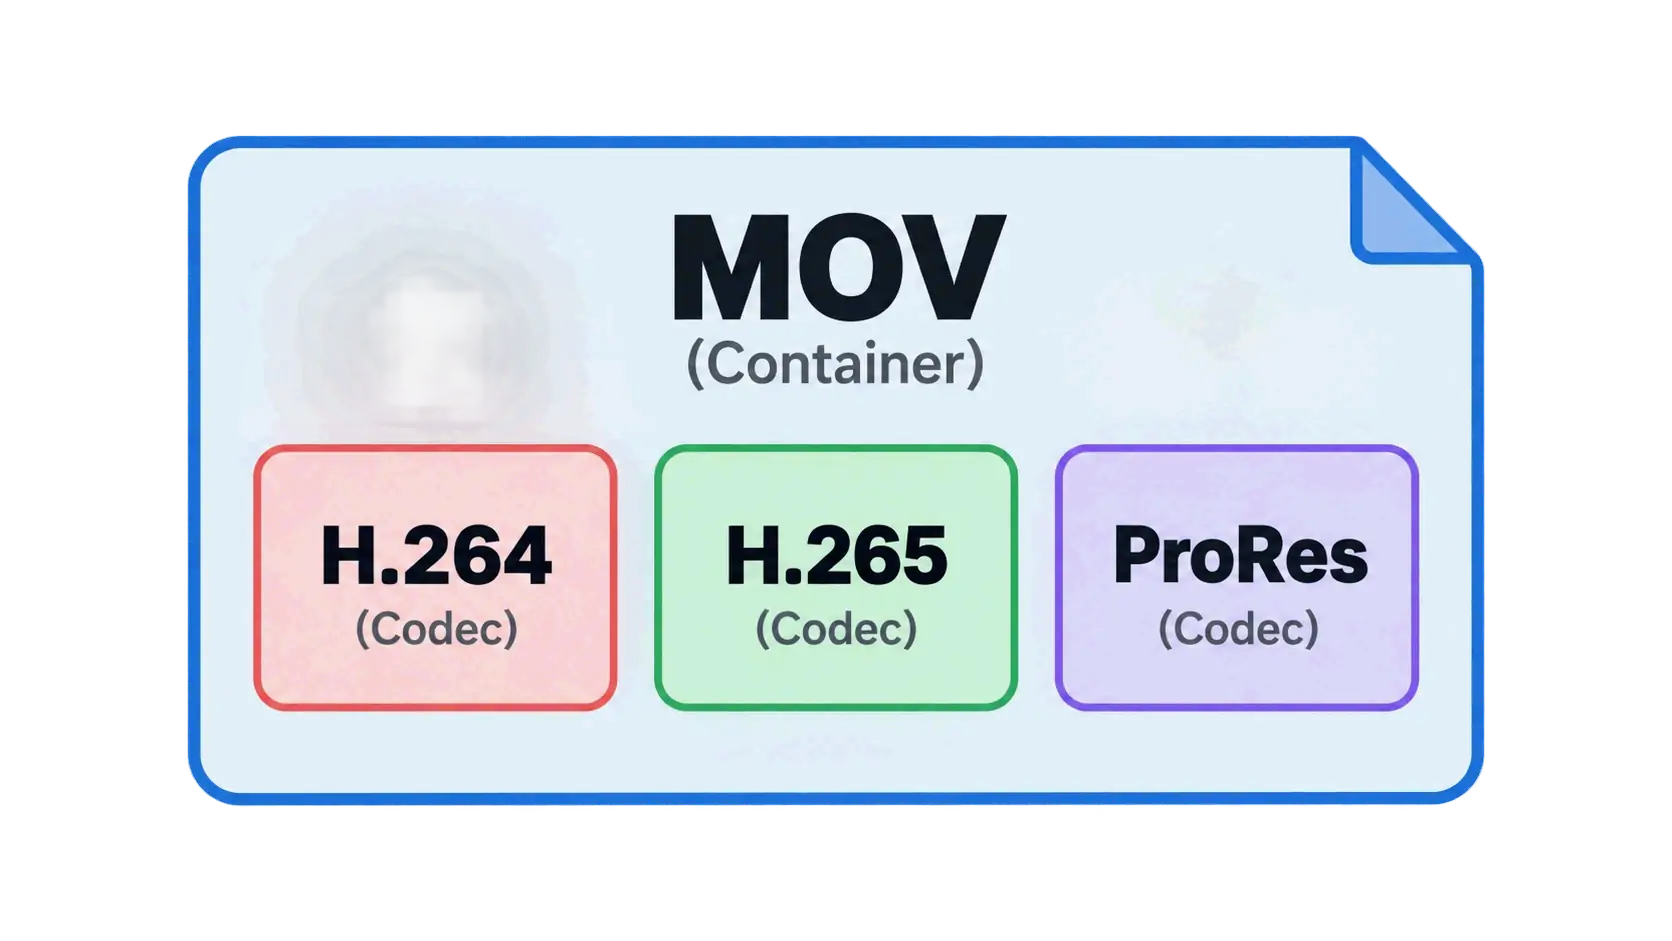
    HandBrake and 7-Zip cover the rest of the toolchain: HandBrake for GUI-driven video re-encoding — iPhone and QuickTime footage has its own quirks, covered in how to compress a MOV file — and 7-Zip or WinRAR for archive compression when the file is a folder of documents or assets rather than media.

    When quality matters, a link beats compression because the file never passes through Discord’s encoders — the core of bypassing Discord’s file limit without Nitro. Choose a host by criteria, not brand. According to TinyGrab, the questions that separate the options are:

    • Does the recipient need an account? WeTransfer allows downloads without an account for basic transfers; Google Drive and Dropbox often require a Google or Dropbox account depending on the sender’s settings.
    • Does the link expire? WeTransfer keeps files available for a limited time on the free tier, while Google Drive, Dropbox, Mega and MediaFire generally keep them available as long as the account is maintained.
    • Does the host re-encode? A cloud drive link preserves the original file; a video streaming preview does not. If the recipient needs the original, permission to download the file itself must be granted.
    • Can you set permissions or an expiry? Public links work for anyone with the URL; private links require authentication and are the better default for sensitive files.
    • Does it work on mobile? Recipients on phones should be able to open the link in a browser without installing a client.

    Mega adds end-to-end encryption and generous free storage, which makes it the fit when the file is sensitive. WeTransfer is the fit when the transfer is one-off and simplicity matters more than permanence.

    Branch 3: Split archives, and when not to bother

    Splitting into volumes with 7-Zip or WinRAR works, but only if each part independently stays under the applicable limit. Every part has to be downloaded before the archive can be rejoined, and on Windows joining RAR parts requires WinRAR — so the recipient needs the right tool. Treat this as a last resort for document bundles and folders, not for a single large video. For simple bundling without the split-and-rejoin dance, zipping a file on Mac and Windows is the lighter option.

    One path worth knowing that skips all three branches: the Tenor and GIPHY GIF picker inside Discord shares a link rather than uploading a file. Per BulkPicTools, using the built-in picker means “the file never touches your upload limit.” Pasting a Tenor or GIPHY URL directly into chat behaves the same way.

    Why Does Discord Reject a File That’s Already Under 20MB?

    The root cause is timing. Since August 2026, Discord checks file size before compression on both desktop and mobile. The Help Center explains it directly: previously on mobile, Discord would try to compress the file first and only tell you afterward if it was still too large, so the limit you saw didn’t always match what applied. Discord then “moved mobile to the same pre-compression check that desktop has always used, so the number you see is the number that counts.”

    That single change explains the most common false alarm. A video that shows as 20MB in your file manager, and that would have compressed well below the limit, is measured at its original size — and if the original is 20.4MB, it fails.

    Order the checks so you don’t waste time. First, confirm the original file size in your OS. Second, note the platform — Android versus desktop or iOS. Third, confirm whether you’re looking at a pre-compression or post-compression number. Fourth, check format restrictions. Fifth, consider content scanning. Sixth, check account and server permissions.

    Two non-size blockers are worth naming because they look like size failures. Only .jpg, .jpeg, .png, .webp and .gif render as inline embedded media per the Discord API reference; other formats still upload but appear as downloadable files, which users often read as a failure. Separately, Discord’s NSFW content scanning can block an upload if the system flags the image, and a missing “Attach Files” permission or role restriction in a server channel blocks it regardless of size.

    The pre-compression check, explained

    The pre-compression check evaluates the source file, not the compressed output. Discord’s stated reason is consistency: evaluating the original prevents the same file from appearing eligible on one device and failing on another after processing. The practical consequence is that you can’t rely on Discord’s own compression to rescue an oversized upload.

    This is why “compress it in the app” isn’t a workaround. If the original is over your limit, the upload is rejected before any processing happens. The fix is to reduce the source file on your device — export a lower-bitrate copy, resize the image, or split the archive — and then upload the smaller file.

    Android: why lowering your recording quality does not fix it

    Discord’s own documentation warns that Android users may hit the limit more often because source files tend to be larger. The Android free upload limit is not different from desktop or iOS; the difference is that an Android device can produce or retain a larger original file before Discord ever sees it.

    Lowering in-app camera or recording quality settings doesn’t change a file that already exists on the device. If a clip was recorded at 4K and saved at 180MB, adjusting the recording setting forward has no effect on that file. The correct fix is to re-export or compress the existing file, or to check the original size in the file manager before trying again.

    The fastest diagnostic is to try the same file on desktop. If it uploads there and fails on Android, the issue is the source file on the phone, not the account. Contact Discord Support only after the file succeeds on one platform and fails on another with the same account.

    Video and GIF Limits: Re-Encoding, 10-Minute Splits, and Auto-Play

    Discord re-encodes uploaded video to its own preferred settings. That’s why gameplay footage or a screen recording can look softer after it’s sent — the file you uploaded is not the file the recipient downloads or streams. The transientfiles.com guide describes this as re-encoding “to Discord’s preferred settings — which is why gameplay footage looks softer after you send it.”

    Long clips are also split. The same source notes videos longer than about ten minutes are split into ten-minute clips by the app itself, commonly around the 10-minute mark. If continuous playback matters, uploading a link to a host that preserves the original is the better route.

    GIFs are subject to the same per-file upload limit as any other file. The much-quoted ~256KB figure is a playback threshold, not an upload rule. Per BulkPicTools, GIFs above a certain size will not animate automatically and sit as static images until someone clicks them, and “the number that comes up most often is 256KB, though Discord hasn’t made this an official published spec.”

    Server asset limits are a different dimension entirely. Animated emoji cap at 256KB, animated stickers at 512KB and must be exactly 320×320px, and both limits are stricter than the chat upload limit and do not change with Nitro status. The 8MB profile avatar and banner figure is a Nitro profile asset limit, not a chat upload limit, and animated avatars are a Nitro-only feature regardless of file size.

    What’s official and what’s community-tested

    Label every number by provenance. The 20MB free limit, the 50MB Nitro Basic ceiling, the up-to-500MB Nitro ceiling, the 20 MiB API default, and the Boost Level 2 (50MB) and Level 3 (100MB) values are documented by Discord. The ~256KB GIF auto-play threshold is community-tested and explicitly not an official published spec. The 19MB / 720p practical target is a cross-platform recommendation, not a Discord rule. The 8MB legacy figure and the 25MB claim are neither official nor current for chat uploads — 8MB matches the Nitro profile avatar and banner asset limit, and 25MB conflicts with Discord’s own documentation.

    Running a Server or a Bot? How Boost Tiers Change the Limit for Everyone

    Boost level is a server-wide setting. Raising it raises the ceiling for every member of that server, including free accounts and accounts that belong to other servers — the higher value applies inside that server regardless of who is posting. A free member in a Level 3 server uses the 100MB ceiling. A Nitro subscriber in a Level 2 server uses whichever of their personal limit and 50MB is higher.

    Bot developers should read the permitted attachment size from the API rather than hardcoding a number. The Discord API reference states the default limit is 20 MiB per file and notes it “may be higher for users depending on their Nitro status or by the server’s Boost Tier,” and the attachment_size_limit value provided in interaction payloads is calculated as the maximum of these values. Reading that field keeps a bot in sync with the account and server context it’s acting in.

    Common practice is to leave about 1MB of headroom under each tier cap so rounding and encoding overhead don’t cause rejections. The Cove bot repository uses 49.0MB for Level 2 and 99.0MB for Level 3 for exactly this reason, and after the August 2026 change it proposed moving Level 0/1 from 9.5MB to 19.5MB. Carrying forward 8MB or 10MB constants causes unnecessary re-compression and visible quality loss for media that would now upload fine.

    The bot’s limit and the client’s displayed limit must agree. If a bot enforces 10MB while the client allows 20MB, users get contradictory error messages and lose quality to compression that was never needed.

    Conclusion

    In 2026, the number is 20MB per file for free accounts — not 8MB, not 25MB — and the cap you actually get depends on your account tier, the server’s Boost level, and where you’re posting. Check the real size of the original file first. If it’s under 20MB and still rejected, test it on desktop. If it’s over, pick your branch deliberately: compress to about 19MB with the FFmpeg recipe, or share a link when quality matters. Confirm your own ceiling in the app rather than trusting any published table, including this one.

    FAQ

    Is Discord’s free upload limit 8MB, 10MB, 20MB or 25MB in 2026?

    20MB per file is current, in force since August 2026. 10MB was correct until that change, and 8MB is older still. The 25MB figure conflicts with Discord’s own Help Center and API reference and should not be treated as fact.

    Is the Discord upload limit per file or per message?

    Per file — you can attach several files in one message. Three 15MB files are fine on a free account because no single file exceeds 20MB. Server Boost and Nitro raise the per-file ceiling, not the number of files you can send.

    Do I need Nitro to send a file larger than 20MB?

    Not necessarily. Nitro Basic gives 50MB and Nitro up to 500MB, but a Boosted server raises the limit for free members too — Level 2 is 50MB and Level 3 is 100MB. Compressing to around 19MB or sharing a cloud link also works without paying.

    Does Discord compress files I send, and does it check size before or after compression?

    Since August 2026, both desktop and mobile check the pre-compression size, so the original file size decides whether the upload is accepted. Discord may still re-encode video after it is accepted, which is why quality can drop even when the upload succeeds.

    Why does Discord reject my upload on Android when the file is under 20MB?

    The pre-compression check means Android’s larger exported source files are what get measured. Lowering in-app recording quality does not change the size of a file already on the device. Test the same file on desktop to confirm it is a source-file issue rather than an account limit.

    Can a server Boost level raise the upload limit for everyone in that server?

    Yes — Boost is server-wide: Level 2 lifts the ceiling to 50MB and Level 3 to 100MB. The higher of your account tier and the server’s Boost level applies inside that server. Boost does nothing in DMs.

    Can I upload a larger file if I’m in a boosted server but my own account is free?

    Yes, inside that server you can use the boosted ceiling, up to 100MB at Level 3. The moment you post in a DM or in an unboosted server, your free 20MB limit applies again. Nitro subscribers keep their own higher limit everywhere.

    Do GIFs have a different size limit than other files on Discord?

    Uploads use the same per-file limit as any other attachment — 20MB on a free account. The ~256KB figure people quote is a community-tested auto-play threshold, not an official upload rule. Sending a GIF through the Tenor or GIPHY picker shares a link and skips the upload limit entirely.}

  • Days Until Christmas 2026: Exact Count and How to Check Today’s Number

    Days Until Christmas 2026: Exact Count and How to Check Today’s Number

    Header: Christmas countdown theme

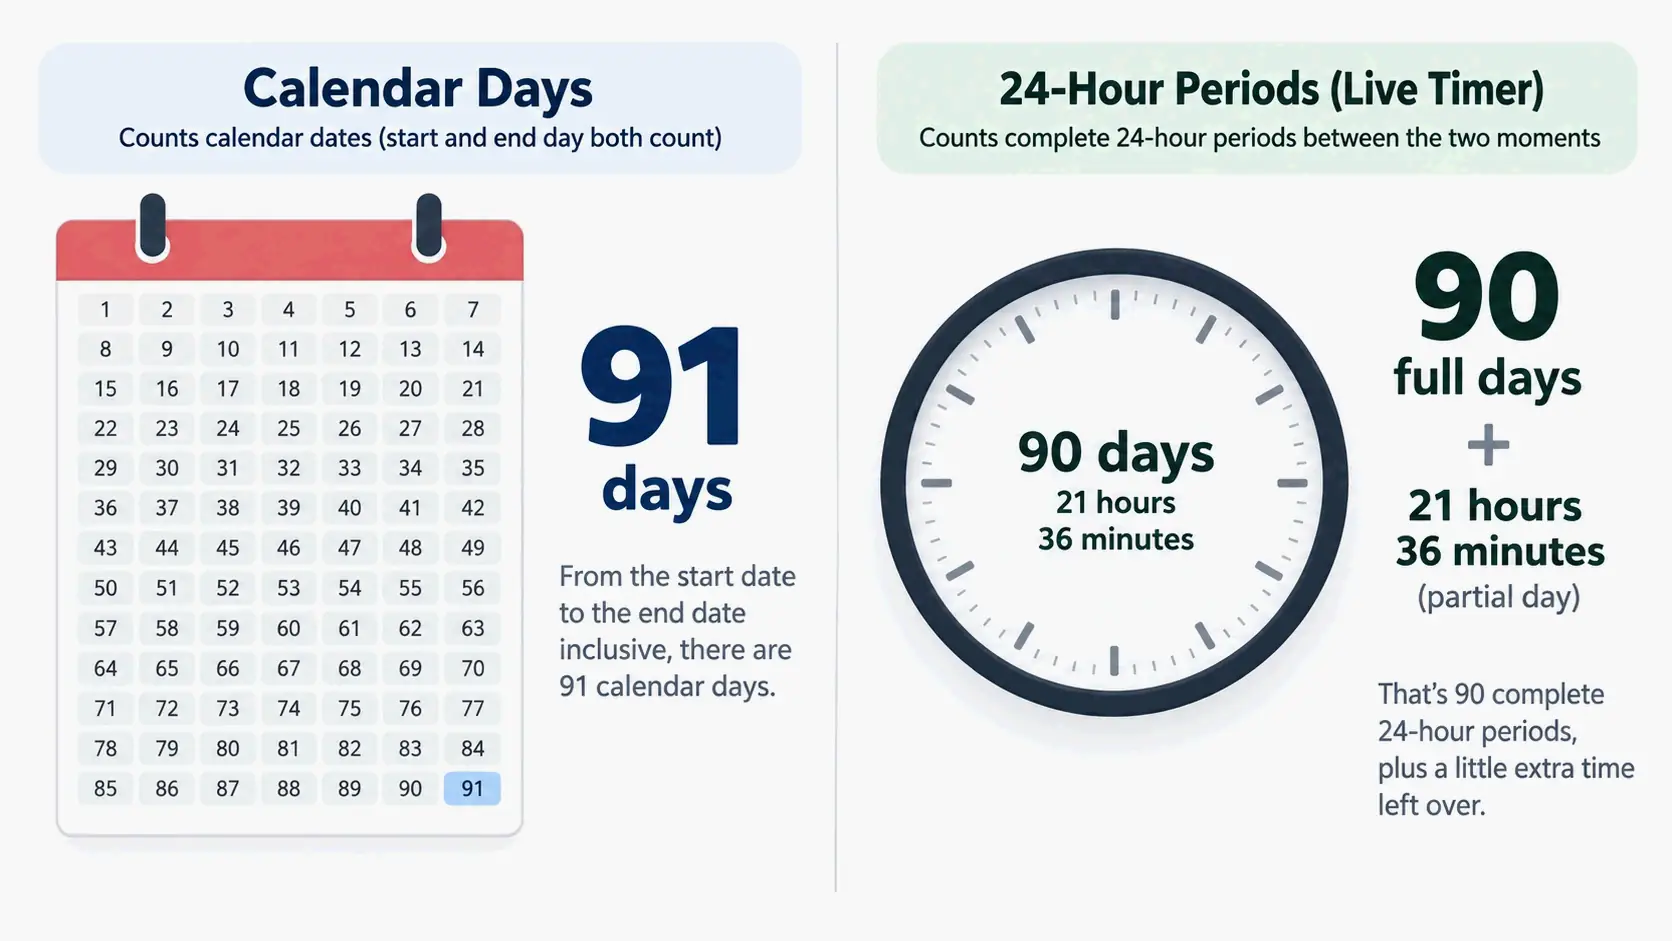
    As of September 25, 2026, there are 91 days until Christmas 2026. Christmas Day falls on Friday, December 25, 2026 — that’s 13 weeks, 13 weekends, or 91 sleeps. A live countdown timer shows 90 full days plus about 12 hours. And because every countdown number on this page drops by one each day, use this table to read the count for the date you’re actually on:

    If today is… Days until Christmas 2026
    October 9, 2026 77
    November 1, 2026 54
    November 26 (Thanksgiving) 29
    November 29 (Advent Sunday) 26
    December 1, 2026 24
    December 15, 2026 10
    December 24 (Christmas Eve) 1
    December 25 (Christmas Day) 0

    The convention throughout: today is not counted, Christmas Day is. Every row follows the same rule the article unpacks below — and the spreadsheet formula near the end gives you a number that updates itself daily.

    How Many Days Until Christmas 2026? The Direct Answer

    There are 91 days until Christmas Day 2026, which falls on Friday, December 25, 2026. Days.To breaks the same wait down as 13 weeks, 13 weekends, 64 weekdays, 2,184 hours, and 91 sleeps.

    Quick answer: 91 days, 13 weeks, 91 sleeps

    How Many Days Until Christmas reports 91 calendar days from September 25, 2026 in New York, or exactly 13 weeks and 0 days. Inch Calculator also lands on 91 days, or 13 weeks and 2,184 hours, and notes that Christmas is a U.S. federal holiday.

    As-of date and timezone: America/New_York

    Every number on this page is tied to an as-of date of September 25, 2026 and to the America/New_York timezone. That phrase — “as of September 25, 2026 in New York, there are 91 calendar days” — matters because the count drops by one each day. Inch Calculator shows 95 days on September 21, 94 on September 22, 93 on September 23, 92 on September 24, and 90 on September 26. If you read this on a later date, expect a smaller number.

    Why Your Live Christmas Countdown Timer Shows 90 Days, Not 91

    The 90-versus-91 gap isn’t an error. It comes from two different ways of measuring the same stretch of time: calendar date labels and complete 24-hour periods.

    A calendar-day count leaves out today, September 25, and includes December 25. That gives you 91 days. A live timer measures full 24-hour blocks left until midnight starts Christmas Day, so it shows 90 full days plus a partial day. Days.To displays both on one page — a timer reading 90d:12h:10m:26s next to a written answer of “91 days until Christmas Day.” That side-by-side display is the most common source of confusion. How Many Days Until Christmas explains the same split in its FAQ: one display counts New York date changes, the other counts complete 24-hour cycles, and a partial day can push the full-day figure down by one.

    Calendar days vs. 24-hour periods: the rule to remember

    Use calendar days when you want a date-to-date answer: September 25 to December 25 is 91 days. Use the live timer when you want the exact time remaining: roughly 90 days and 12 hours from the moment the timer was read. Neither is wrong. They answer slightly different questions.

    Which number should you quote?

    Quote 91 days for conversations, planning, and headlines tied to a date. Quote “90 days plus about 12 hours” only when someone wants precision down to the current hour. If a friend insists the real answer is 90, they are reading a live timer, not a calendar.

    Concept: 91 calendar days vs. 90 days + 12 hours

    91 Days in Other Units: 13 Weeks, 13 Weekends, and 91 Sleeps

    The same 91 days can be broken into a few useful units. Each one suits a different planning purpose.

    Weeks, weekends, and sleeps

    How Many Days Until Christmas gives 13 weeks and 0 days, 13 weekends, and 91 sleeps. Days.To agrees on 13 weeks, 13 weekends, and 91 sleeps, and adds 2,184 hours. Your Christmas Countdown explains the sleep convention plainly: add 1 to the number of days shown, and that is how many sleeps remain. Sleeps are the version most families and classrooms use, because each night marks one visible step toward Christmas morning.

    Hours and minutes (if you really want precision)

    Two sources report slightly different hour totals — 2,184 from Days.To and Inch Calculator, versus 2,177 from How Many Days Until Christmas — because each page measures from the moment it was loaded. Treat any hour or minute figure as a snapshot, not a fixed fact. Re-check it if you need the number for a specific moment.

    Shopping days and business days

    How Many Days Until Christmas counts 90 potential shopping dates after September 25 through Christmas Eve, December 24, 2026 — noting that this does not check store hours, holidays, stock, or delivery cut-offs. One older convention is worth retiring: skipping Sundays as shopping days predates online carts and Sunday trading, as FailFlow points out. Workday counts get their own section below, because sources disagree.

    Christmas Day 2026 Falls on Friday: What It Means for Christmas Eve and Boxing Day

    Christmas Day 2026 is Friday, December 25, 2026. That puts Christmas Eve on Thursday, December 24, and Boxing Day on Saturday, December 26.

    The 2026 Christmas week at a glance

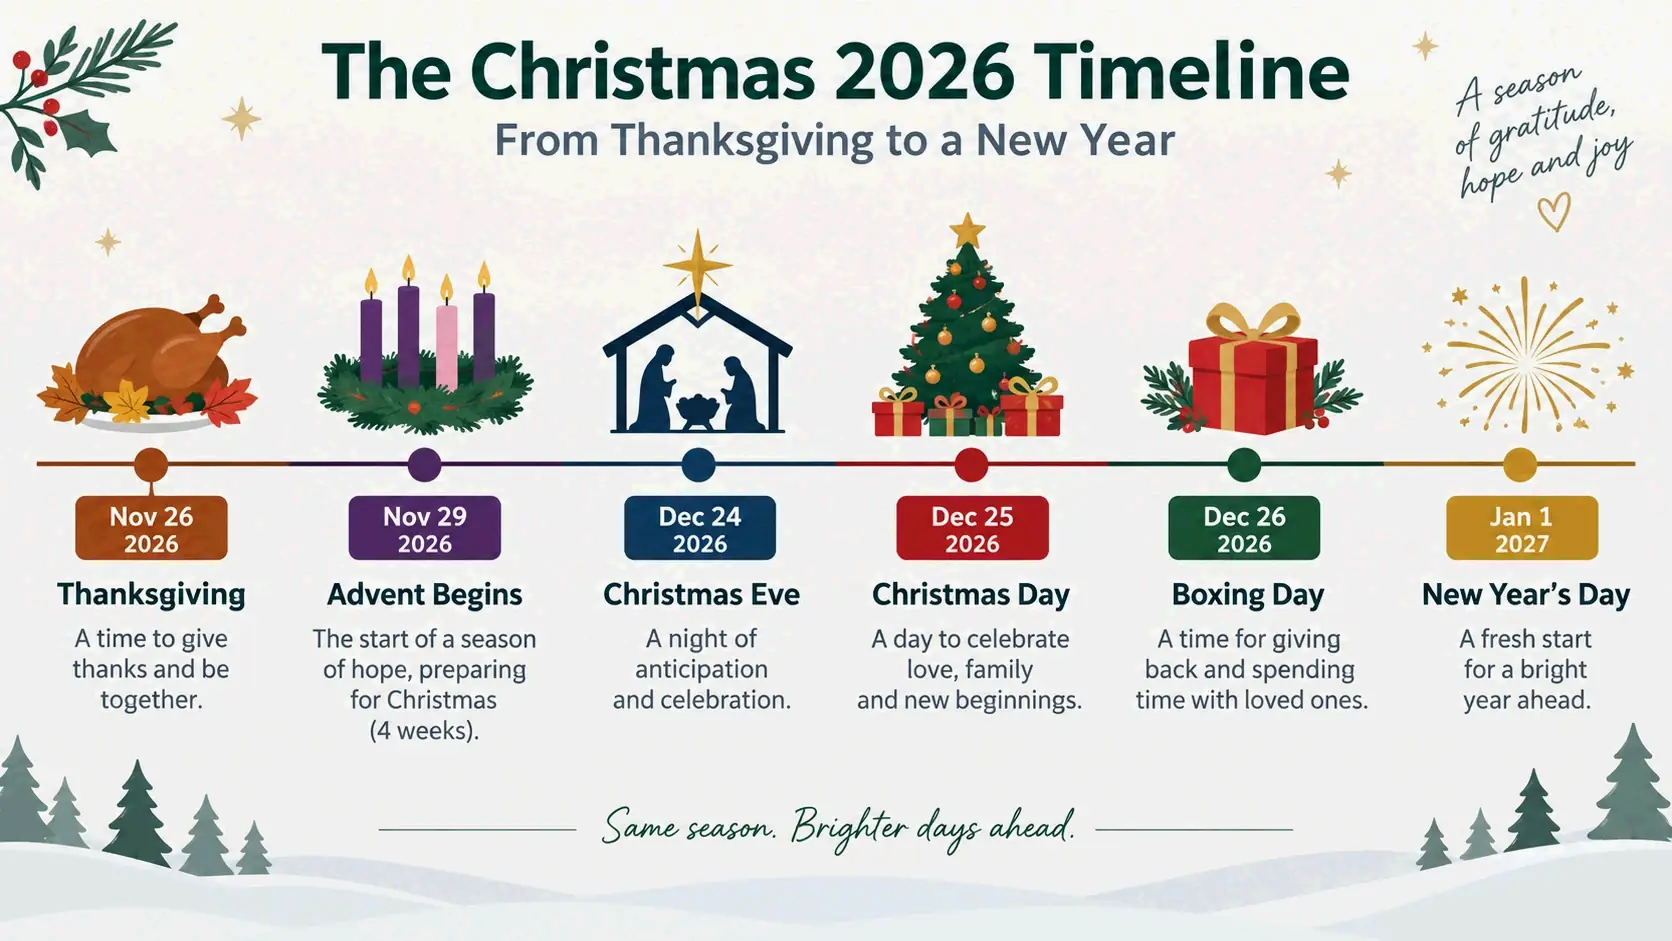
    How Many Days Until Christmas lists the surrounding U.S.-relevant dates for 2026: Thanksgiving on Thursday, November 26; the First Sunday of Advent on November 29; Christmas Eve on Thursday, December 24; Christmas Day on Friday, December 25; Boxing Day on Saturday, December 26; New Year’s Eve on Thursday, December 31; and New Year’s Day on Friday, January 1, 2027.

    Timeline: key dates around Christmas 2026

    Boxing Day is not a U.S. federal holiday. WatchIsUp notes that December 26 is a holiday in the UK, Ireland, Canada, Australia, and New Zealand, but in the United States it is an ordinary working day, so many businesses stay open. Christmas Day itself is a U.S. federal holiday, according to Inch Calculator.

    Is Christmas 2026 a long weekend?

    Whether a Friday Christmas creates a long weekend depends on your employer, your state, and applicable holiday rules. How Many Days Until Christmas states it directly: Thursday and Monday are not automatically days off, so check school calendars, opening hours, and travel availability before booking anything.

    One pattern to remember: the same source’s Christmas Day-of-Week History table shows 2024 on Wednesday, 2025 on Thursday, 2026 on Friday, 2027 on Saturday, 2028 on Monday, 2029 on Tuesday, and 2030 on Wednesday.

    Weekdays and Business Days Until Christmas 2026

    Workday counts for the same 91-day window differ by one depending on the source and the counting convention.

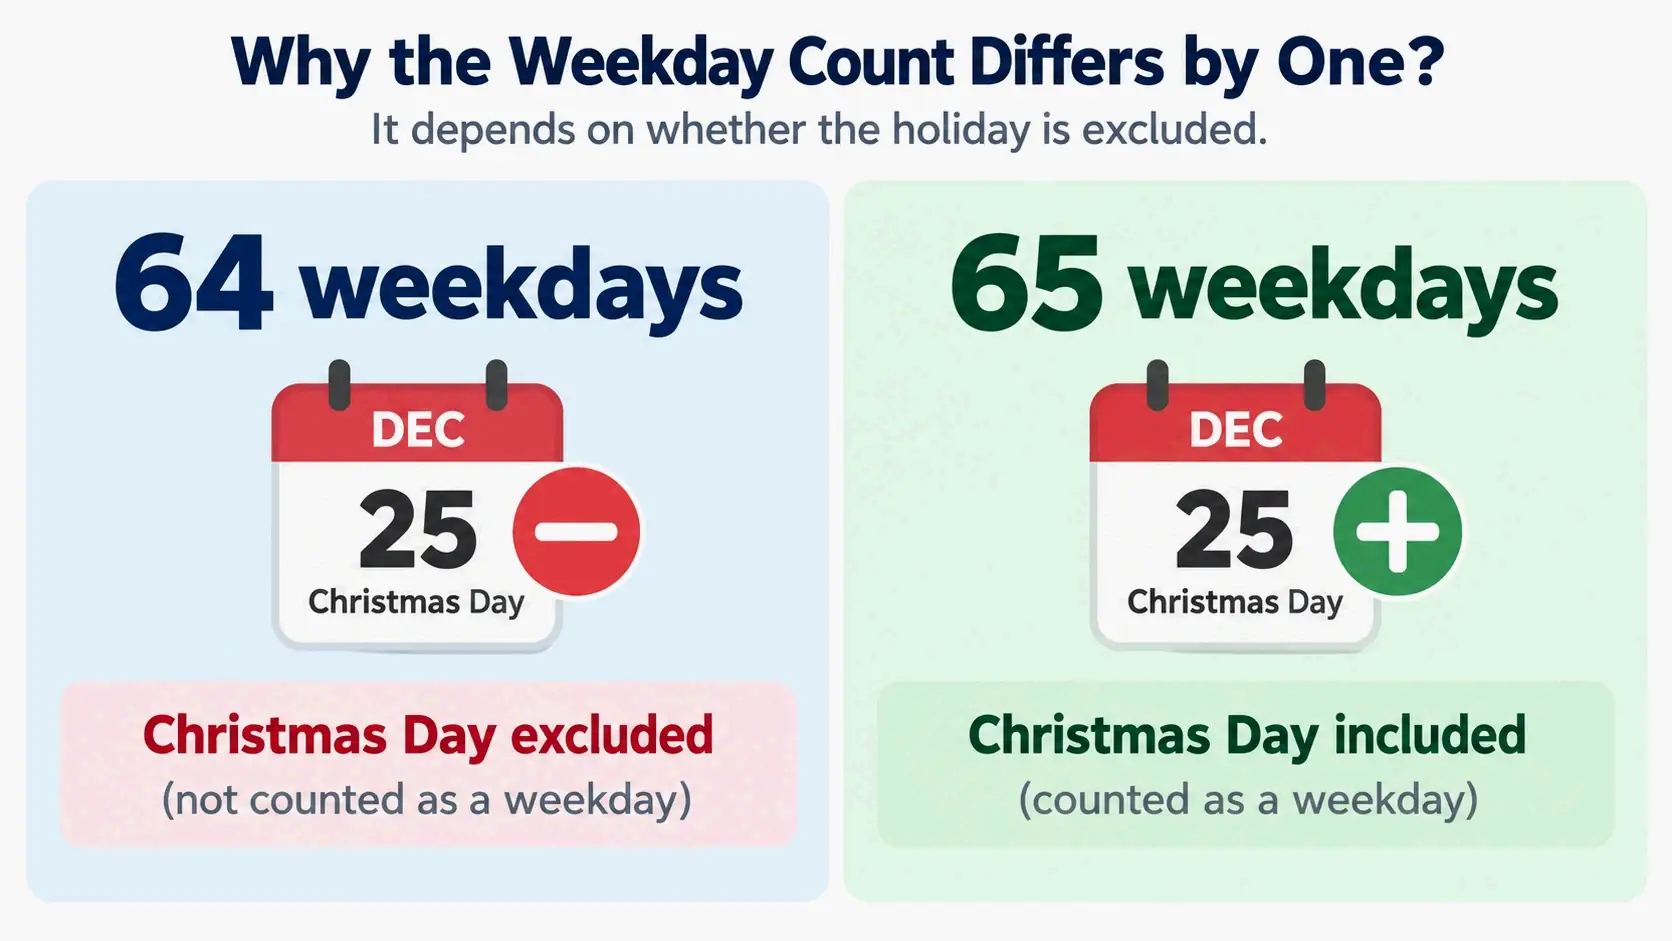
    Days.To reports 64 weekdays (Monday to Friday) until Christmas Day, not counting the day itself. Inch Calculator reports 65 weekdays and warns that its figure does not account for holidays falling on weekdays, such as Thanksgiving. FailFlow also lands on 65 business days counting weekdays only, with public holidays not subtracted.

    How weekdays are counted

    The typical method counts Monday-through-Friday dates between today and the target date. September 25, 2026 falls on a Friday, so the count includes every remaining weekday in September, all of October and November, and the December weekdays before Christmas — except for the holiday adjustments each source chooses to apply or ignore.

    Why 64 vs 65 matters

    Christmas Day is a U.S. federal holiday, so a business-day calculation can legitimately exclude December 25 as a non-working day. That is why the totals sit one apart. For office planning, commutes, and deadline-setting, use 64 weekdays as the conservative figure and subtract any additional company holidays you observe.

    Comparison: 64 vs 65 weekdays and the holiday exclusion

    Advent 2026 and US Thanksgiving: Your Next Countdown Anchors

    Ninety-one days is too long to hold in your head. Two late-November anchors — Thanksgiving and Advent — break the wait into manageable phases.

    Thanksgiving 2026 countdown

    US Thanksgiving is Thursday, November 26, 2026. How Many Days Until Christmas places it in the 2026 key-dates list as the unofficial start of the American Christmas season. Days.To listed 62 days to Thanksgiving when its Christmas page was captured on September 25, 2026. That gives you roughly two months from the as-of date to plan menus, travel, and early decorating.

    Advent 2026: November 29 vs December 1

    In Western Christian calendars, Advent 2026 begins on Sunday, November 29, 2026, according to How Many Days Until Christmas, which also records Advent at 65 days out from September 25. WatchIsUp adds the seasonal range: Advent counts the four Sundays before Christmas, so it starts between November 27 and December 3 each year. A chocolate Advent calendar is a different convention entirely — those always begin on December 1. Keep the two separate when you plan, or you will be four days off.

    From Countdown to Action: A US Christmas Planning Timeline

    With 91 days and roughly 90 potential shopping dates through December 24, the practical move is to split the countdown at U.S. holiday anchors rather than treat it as one long block.

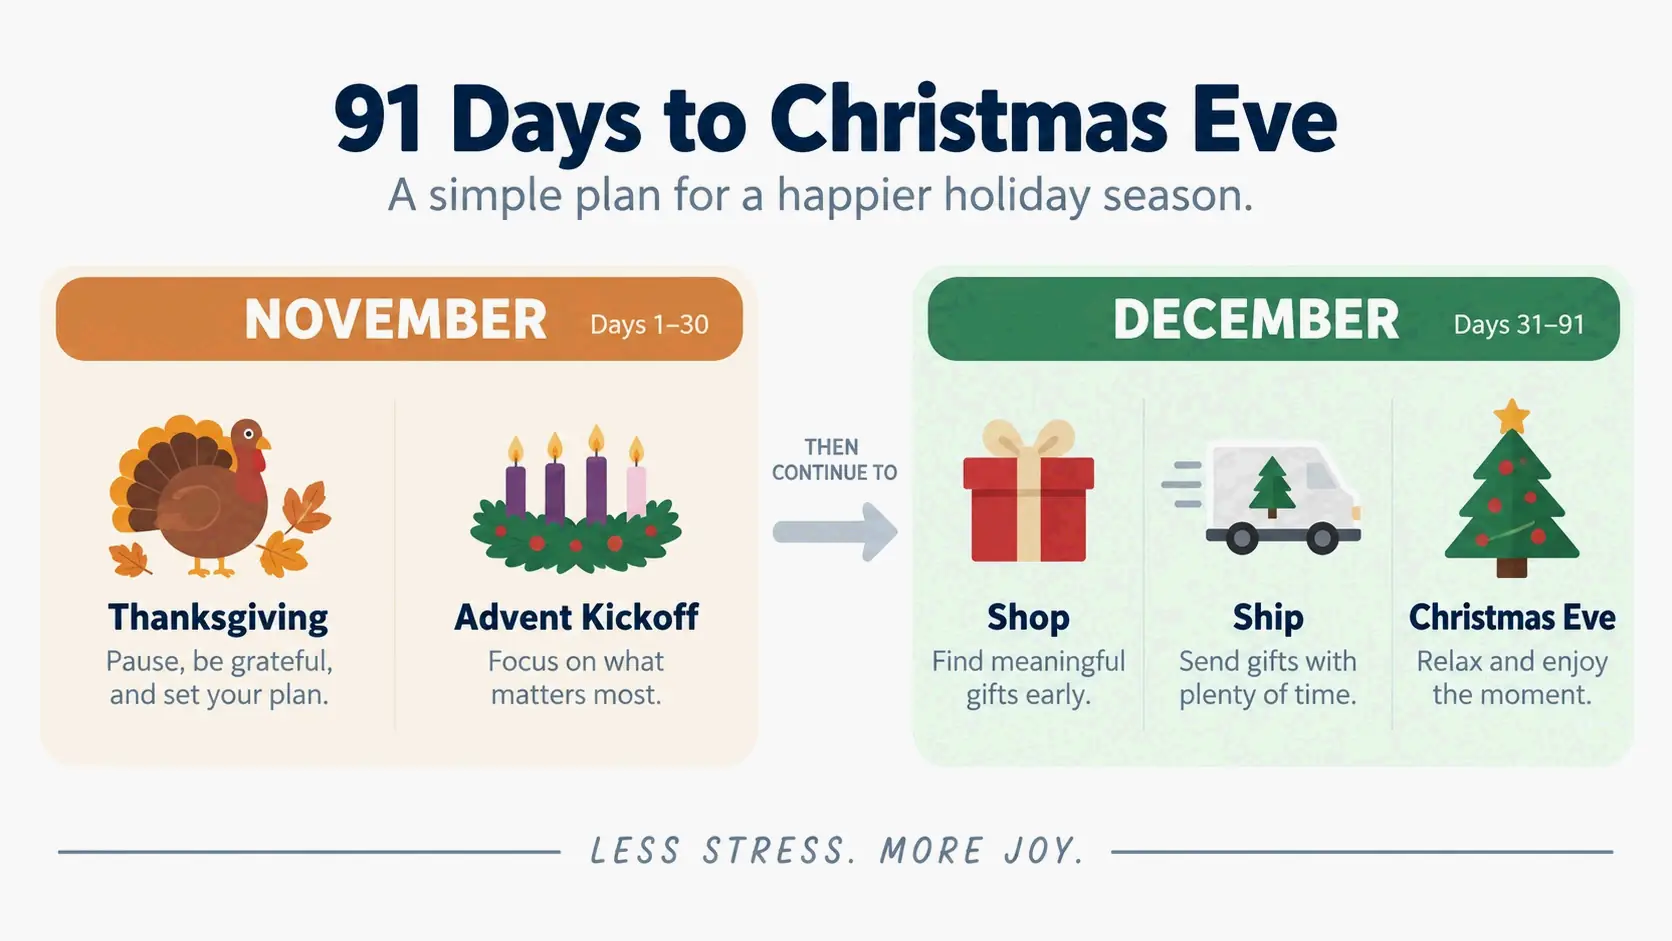
    November: Thanksgiving and Advent kickoff

    Thanksgiving on November 26 and Advent on November 29 sit four days apart in 2026, so late November is your natural planning checkpoint. Use the days before them to agree on budget, recipients, and likely guests, and to verify long-lead items — custom orders, travel bookings, and shared family dates — because those decisions need the most lead time. How Many Days Until Christmas frames this as a flexible sequence: set limits, check long-lead plans, choose details, confirm final arrangements, and leave room for changes.

    December: shopping, shipping, and Christmas Eve

    December holds the compressed work. Days.To counts 64 weekdays for planning, and Christmas Eve lands on Thursday, December 24 — one day before the holiday. FailFlow notes that Christmas Eve comes 90 days after September 25, 2026, and that all 91 days count as shopping days under modern retail conditions. Work backward from December 24 for gifts that must ship, and treat the last week as buffer rather than primary shopping time.

    Planning timeline: November and December phases

    What to verify instead of copying dated shipping deadlines

    Carrier deadlines are the least reusable content in Christmas planning. Countdown Christmas publishes Royal Mail and Parcelforce posting dates tied to UK addresses and a specific year — a useful illustration of why any deadline table you find may be both out of date and in the wrong country. Instead, check the official carrier page for the year and destination you are shipping to, and confirm processing times, stock, delivery estimates, and return terms before paying. Finally, remember that countdown answers expire daily: always match a number to its as-of statement.

    How to Calculate Days Until Christmas 2026 Yourself (Google Sheets / Excel)

    If you want a number you control, a spreadsheet handles it in one cell — and the same calendar-day conventions (exclude today, include the target) are exactly the rules covered in how many days between two dates, applied to a fixed destination.

    Basic days formula

    Type =DATE(2026,12,25)-TODAY() into any cell and press Enter. Inch Calculator documents this formula and a variant for a fixed start date in another cell: =DATE(2026,12,25)-A1. The result updates automatically as TODAY() moves forward.

    Weeks and business days formulas

    For whole weeks, use =INT((DATE(2026,12,25)-TODAY())/7), the method Inch Calculator lists for weeks until Christmas. For workdays, the standard =NETWORKDAYS(TODAY(), DATE(2026,12,25)) counts Monday through Friday but does not subtract holidays, so add a holiday range or edit the result manually — Thanksgiving and Christmas Day both fall on weekdays in 2026. Set the spreadsheet timezone to America/New_York so your count matches the countdown pages referenced here.

    Classroom Countdown Ideas: 91 Sleeps and 64 Weekdays

    Countdown numbers work well in classrooms because they are visual, finite, and easy to update each morning.

    Paper chain and daily countdown

    How Many Days Until Christmas describes the classic approach: make one paper chain loop for every remaining sleep, then remove one after waking each day. With 91 sleeps as of September 25, 2026, a full chain is long enough to fill a wall and visibly shrink. Teachers tracking working days only can use the 64-weekday figure instead, which fits a classroom calendar better than calendar days.

    Advent calendar vs. Advent Sunday in the classroom

    Advent 2026 begins Sunday, November 29, and a numbered December calendar starts December 1 — four days apart. Label which one your class is following, or the count will look wrong to students. Optional add-ons mentioned by countdown sites include watching one Christmas film a week from mid-November and using an Elf on the Shelf routine, which Your Christmas Countdown links to as a family and classroom activity.

    2026 Christmas News and Entertainment Updates

    Updated September 2026. The items below are the entertainment stories countdown trackers were covering in late September 2026. They are listed with their reporting dates rather than treated as confirmed schedules.

    Your Christmas Countdown reported that Mariah Carey is bringing her Christmas show to the UK in 2026, that Tyler Perry’s The Gospel of Christmas is coming to Netflix in 2026, and that its Christmas Movies 2026 roundup of confirmed films was updated in September 2026. Treat announcements as announcements: verify release dates on the platform or ticketing page before planning around them, and expect titles without a firm date to shift.

    Conclusion

    As of September 25, 2026, there are 91 days until Christmas 2026, and Christmas Day lands on Friday, December 25, 2026. Pick one anchor rather than tracking all 91 days: US Thanksgiving on November 26, Advent on November 29, or a December shopping milestone that forces early decisions. Use the live countdown for daily motivation, but check any number against its as-of date and timezone, because every countdown answer on this page drops by one tomorrow.

    FAQ

    Does the Christmas countdown include today?

    No. The standard calendar-day count leaves out today and includes Christmas Day. That is why the answer as of September 25, 2026 is 91 days. How Many Days Until Christmas shows the same convention in action, displaying 1 on Christmas Eve and 0 throughout Christmas Day. Including today would give 92, but most countdowns do not count the current day.

    Why does the live timer show 90 days when the calendar says 91 days?

    The calendar answer counts date labels: September 25 to December 25 spans 91 days. A live timer measures full 24-hour periods, so it shows 90 full days plus about 12 hours. Days.To displays both a 90d:12h timer and the written answer “91 days” on the same page, which is exactly where the confusion starts.

    How many sleeps until Christmas 2026 for kids?

    There are 91 sleeps until Christmas 2026 as of September 25, 2026, according to both Days.To and How Many Days Until Christmas. Sleeps are a family-friendly count because each night marks one step closer to Christmas morning. Naps do not reduce the total, and the number drops by one each morning after waking.

    When does Advent start in 2026?

    In Western Christian calendars, Advent 2026 begins on Sunday, November 29, 2026, per How Many Days Until Christmas. An Advent calendar with numbered doors usually starts December 1, a different convention. WatchIsUp confirms the range: Advent begins between November 27 and December 3 depending on the year.

    What day of the week is Christmas 2026, and does that create a long weekend?

    Christmas Day 2026 is Friday, December 25, 2026, with Christmas Eve on Thursday and Boxing Day on Saturday. Whether that becomes a long weekend depends on your employer, state, and federal holiday rules. How Many Days Until Christmas warns that Thursday and Monday are not automatically days off.

    How many shopping days or business days are left until Christmas 2026?

    How Many Days Until Christmas counts about 90 potential shopping dates through December 24, 2026. Business-day totals vary: Days.To reports 64 weekdays, while Inch Calculator reports 65, a difference driven by whether Christmas Day is excluded as a federal holiday.

    Is Christmas always on December 25?

    For most Western Christian traditions, Christmas is observed on December 25, and 2026 is no exception. The date is not universal: How Many Days Until Christmas notes that churches using the Julian calendar currently observe Christmas on January 7 in the Gregorian calendar. Other traditions follow their own calendar practices for gift-giving and observance.

    When is Christmas 2027?

    Christmas Day 2027 falls on Saturday, December 25, 2027, one day later in the week than 2026. Days.To listed it as 456 days away when its Christmas page was captured on September 25, 2026. That 456 is simply the 91 days to Christmas 2026 plus the 365 days of 2027 — and because 365 is 52 weeks plus 1 day, the weekday slides one slot each year.

  • Unicode Escape Sequence: \uXXXX Syntax, Surrogates & Fixes

    Unicode Escape Sequence: \uXXXX Syntax, Surrogates & Fixes

    Header: ASCII-only notation carrying Unicode characters across systems

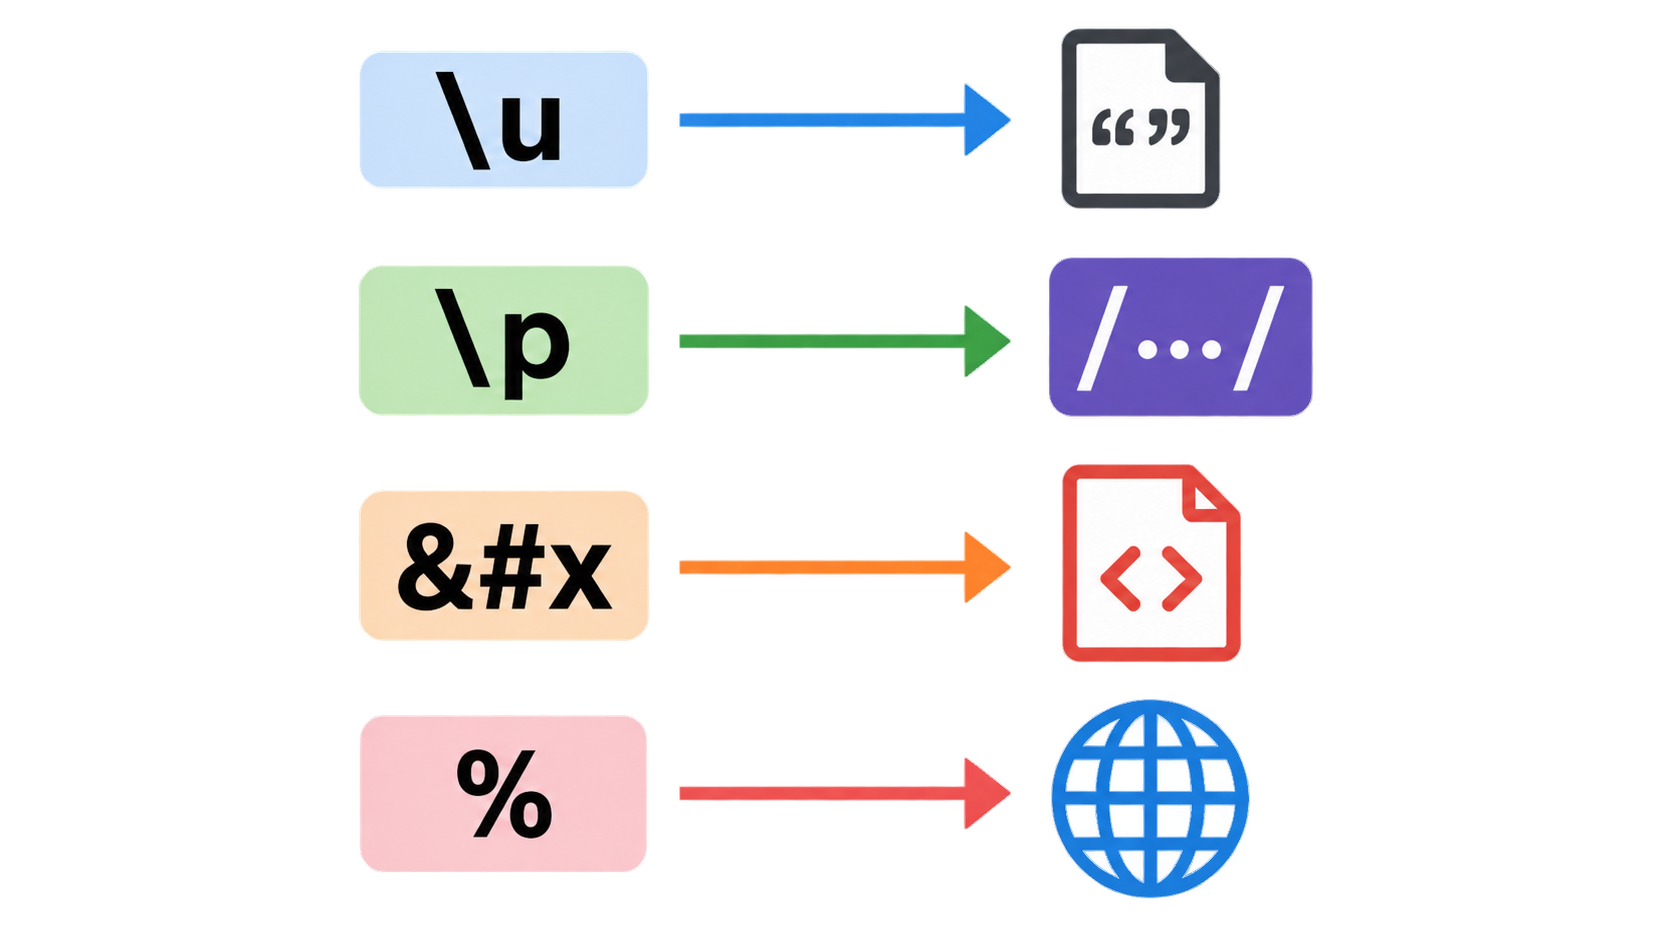
    A Unicode escape sequence is an ASCII-only way to write a Unicode character — usually \uXXXX, where XXXX is the character’s hexadecimal code point. Java and JSON require four hex digits, JavaScript adds \u{...} and \p{...}, HTML uses &#xhhhh;, and URLs percent-encode UTF-8 bytes as %XX.

    What Is a Unicode Escape Sequence?

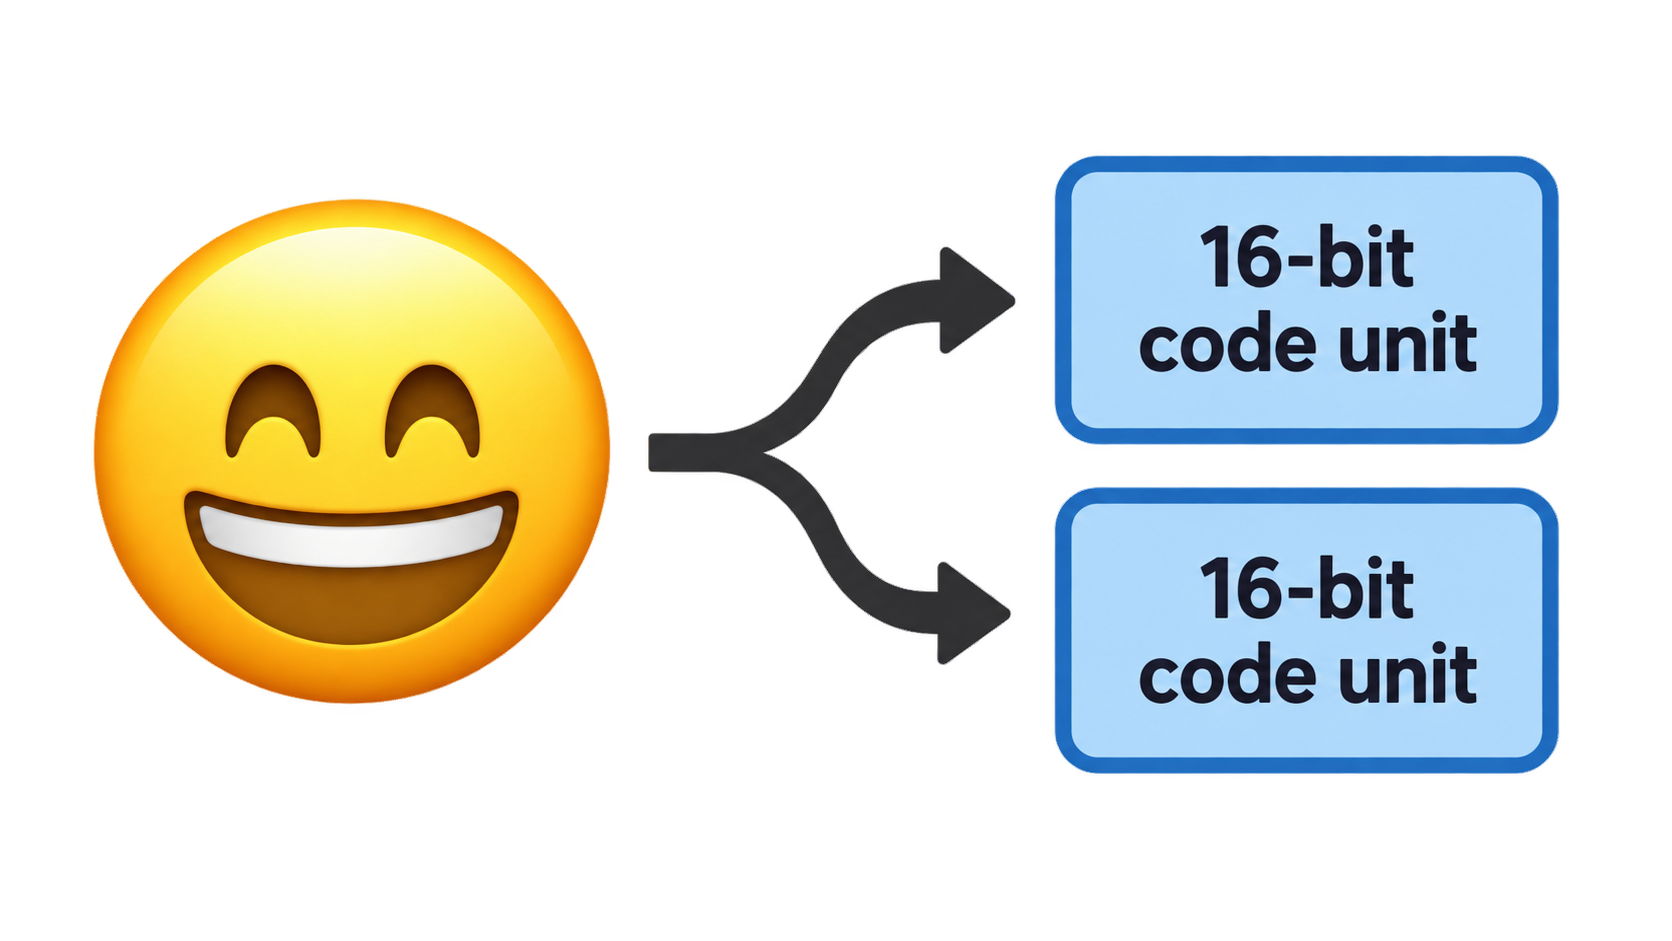
    A Unicode escape sequence is a notation that writes any Unicode character using only ASCII characters, so the text survives tools and protocols that never learned about anything beyond ASCII. The most common form is \uXXXX, where XXXX is four hexadecimal digits giving either a code point or, in UTF-16-based languages, the 16-bit code unit at that value.

    Unicode itself identifies characters with U+ notation: U+0000 is NUL, U+001B is the escape character, U+FFFF is the last code point in the Basic Multilingual Plane, and U+1F600 is 😀. Specifications, documentation, and error messages all use the U+XXXX form to name a character; \uXXXX is how that same character gets written inside source code, string literals, and wire formats.

    The scale behind that notation is large. According to Wikipedia’s list of Unicode characters, Unicode 18.0 assigns 310,351 characters with code points across 175 modern and historical scripts, plus multiple symbol sets. No single page can enumerate them, which is exactly why a compact escape notation exists.

    Unicode Escape vs. Property Escape vs. HTML Character Reference vs. Percent-Encoding

    Four notations look alike but solve different problems. \uXXXX — and JavaScript’s \u{...} — represent a code point or UTF-16 code unit inside a string or source file. \p{...} and \P{...} are Unicode property escapes, which per MDN match a set of characters by Unicode property and are only supported in Unicode-aware mode; outside that mode, \p is merely an identity escape for the letter p.

    HTML and XML numeric character references get resolved by the markup parser, not by a string parser. Wikipedia describes the format as &#nnnn; for decimal code points, &#xhhhh; for hexadecimal, and &name; for a predefined entity name. URL percent-encoding is a fourth system again: %XX encodes bytes, not characters.

    Here’s the one-line rule: read the prefix. \u means a code-point escape, \p means a property class, &#x means a markup character reference, and % means percent-encoded bytes.

    Four prefixes pointing to four different interpreters

    Why Escapes Exist: ASCII-Only Representation

    The purpose is stated directly in the Java Language Specification (Java SE 7, §3.3): Unicode escapes let a program include any Unicode character “using only ASCII characters.” ASCII-only is the lowest common denominator that compilers, JSON parsers, log pipelines, configuration files, and older protocols all handle.

    With 310,351 assigned characters in Unicode 18.0, no toolchain can be expected to carry every character natively. A toolchain can reasonably be expected to carry backslash, u, and hexadecimal digits — so those characters become the transport layer for everything else.

    How to Write \uXXXX in Java, JavaScript, JSON, HTML and URLs

    No reference page on the search results lays the same character side by side across all five contexts. The table below does that, using é (U+00E9, one code unit) and 😀 (U+1F600, a surrogate pair) as the test characters.

    Context Form é (U+00E9) 😀 (U+1F600)
    Java source / string literal \uXXXX, exactly four hex digits "\u00e9" "\uD83D\uDE00"
    JavaScript string \uXXXX for BMP, \u{...} for any code point "\u00e9" or "\u{e9}" "\u{1F600}"
    JavaScript regex \p{...} / \P{...} — a property class, not a character \p{Letter} not applicable
    JSON string \uXXXX only "\u00e9" "\uD83D\uDE00"
    HTML / XML &#xhhhh;, &#nnnn;, &name; é or é 😀
    URL %XX octets of UTF-8 one or more octets four octets (surrogate pair)

    Java Source: Escapes Are Processed Before Tokenization

    JLS §3.3 defines three lexical translation steps applied in order: Unicode escapes are translated first, line terminators are recognized second, and input elements and tokens are formed third. Because escape processing happens before tokenization, the character an escape produces does not participate in further escapes.

    The canonical example: the raw input \u005cu005a yields the six characters \ u 0 0 5 a, not the character Z. The escaped backslash is not reinterpreted as the start of a second escape. Two related rules matter in practice: the u marker may be repeated (\uuuu0041 is legal), and a backslash can only begin an escape when the number of contiguous backslashes immediately before it is even.

    JavaScript: \uXXXX, \u{…} and \p{…}

    \uXXXX in JavaScript covers the Basic Multilingual Plane; \u{...} is used for code points above U+FFFF. \p{...} and \P{...} are a different construct — Unicode property escapes for regular expressions, with \P building a complement class instead of a single character.

    According to MDN, property escapes have been Baseline widely available across browsers since July 2020, and with the v flag \p can match finite-length strings, which is useful for emoji sequences made of multiple code points.

    JSON: What JSON.stringify Actually Emits

    JSON string escaping uses \uXXXX. The failure mode is not in the format but in the serializer: JSON.stringify emits \u0000 and lone surrogates verbatim and performs no validation of whether a downstream store will accept them.

    That is the step where a bad value escapes memory and reaches the database. The serializer’s job ends at producing valid JSON text; whether the JSON text is storable in a particular column is a separate question that the serializer never asks.

    HTML &#xhhhh; and URL %XX Are Not \uXXXX

    An HTML numeric character reference is read by the markup parser. So é and é are the same character to a browser, but mean nothing to a JavaScript string parser. If you need to go the other way and resolve a page of &#xhhhh; and &name; references back to text, an HTML entity decoder does that at the markup layer. Named entity references cover only a limited, predefined set of names.

    URLs take a different route entirely. MDN’s encodeURI() reference explains that the function replaces characters with one, two, three, or four escape sequences representing the UTF-8 encoding of the character, and that four sequences appear only for characters composed of two surrogate units. Because percent-encoding works on bytes rather than code points, one character can become several %XX groups.

    Why Do Emoji Need Two \uXXXX Escapes? Surrogate Pairs Explained

    A character inside the Basic Multilingual Plane corresponds to one escape. A character above U+FFFF is represented in UTF-16 as a pair of 16-bit code units, so it takes two consecutive escapes to write one character.

    JLS §3.3 states this as a rule rather than an edge case: representing supplementary characters requires two consecutive Unicode escapes. The string literal rules in the same specification make the split explicit — one escape sequence for characters in the range U+0000 to U+FFFF, two escape sequences for the UTF-16 surrogate code units of characters in the range U+010000 to U+10FFFF.

    The worked example is 😀. Its code point is U+1F600, and in UTF-16 it is written as \uD83D\uDE00 — a high surrogate from U+D800–U+DBFF followed by a low surrogate from U+DC00–U+DFFF. That’s two escapes for one character, which is why length counts, substring operations, and truncation behave in ways that surprise anyone who assumes one escape equals one character.

    One emoji code point splitting into a high and low surrogate pair

    BMP vs. Supplementary Characters: One Escape or Two

    The dividing line is U+FFFF. Characters from U+0000 to U+FFFF need one \uXXXX escape, because four hexadecimal digits cannot express anything larger. Characters from U+010000 to U+10FFFF need two, because each \uXXXX escape writes exactly one 16-bit code unit.

    This also explains why Java character literals cannot hold supplementary characters at all — the specification limits a char literal to values from \u0000 to \uffff, so a supplementary character must be written as a surrogate pair in a char sequence or as an integer, depending on the API.

    What a Lone Surrogate Actually Is

    A lone, or unpaired, surrogate is one half of an emoji with the other half missing. It is not a character. It shows up when a surrogate pair is truncated, or when arbitrary bytes are decoded as UTF-16.

    Lone surrogates fail loudly in several places. MDN notes that encodeURI() throws a URIError when it encounters a surrogate that is not part of a high-low pair, and that String.prototype.toWellFormed() can replace lone surrogates with the Unicode replacement character U+FFFD, while String.prototype.isWellFormed() can check for them. PostgreSQL jsonb rejects them outright, as the next section shows.

    One consequence deserves emphasis: paired surrogates must be preserved exactly. A sanitizer that treats every high or low surrogate code unit as an illegal character will delete legitimate emoji, which is a hidden bug in a lot of cleanup logic.

    How to Fix “unsupported Unicode escape sequence” (SQLSTATE 22P05)

    This error is the reason many people arrive at this topic at all. Roughly half the results surfaced for this query are issue reports opened in the September 11–24, 2026 window that exist because of this specific database error, yet none of the reference pages explain it. If you are holding a stack trace, the definition of an escape sequence is not the useful part — the fix is.

    What PostgreSQL Rejects and What It Accepts

    The boundary is narrow, and it is worth proving with a runnable statement. In standard-conforming SQL strings, \\ is a literal backslash, so the JSON text below contains a real \uXXXX escape:

    select '{"t":"a\\u0000b"}'::jsonb;        -- ERROR: unsupported Unicode escape sequence (22P05)
    select '{"t":"a\\ud800b"}'::jsonb;        -- ERROR: unsupported Unicode escape sequence (22P05)
    select '{"t":"\\ud83d\\ude00"}'::jsonb;   -- OK
    select '{"t":"\\u0001"}'::jsonb;          -- OK
    

    According to GitHub issue #1493 in THU-MAIC/OpenMAIC, PostgreSQL rejects exactly two escape families that serializers emit verbatim: \u0000 (a NUL byte) and lone UTF-16 surrogates such as \ud800. It accepts \u0001, \u007f, and other control characters, and it accepts paired surrogates such as \ud83d\ude00. The distinction is NUL and unpaired surrogates — not control characters in general, and not escaping as such.

    Two buckets: what PostgreSQL jsonb rejects versus accepts

    Sanitizing Before the Write, Not After Serialization

    The fix that issue #1493 converged on is to sanitize string values while serializing, using the replacer argument of JSON.stringify, so the check runs against the in-memory string rather than against already-serialized text. The replacer walks code units: drop 0x0000; when a high surrogate is followed by a low surrogate, keep the pair and skip past it; drop any remaining lone high or lone low surrogate.

    The issue records a second, harder-won lesson: do not run a regular expression over the serialized JSON. A regex cannot distinguish a real lone-surrogate escape from the literal characters \ and ud800 appearing in content, and stripping those produces invalid JSON — the issue’s author reports hitting SQLSTATE 22P02 that way, which is a worse failure than the original error.

    Two variants of the same fix are noted in the issue. \u0000 can be replaced with U+FFFD instead of dropped if you’d rather keep a placeholder. And the sanitizer must not touch paired surrogate code units, since stripping them destroys valid emoji.

    Binary content needs separate handling. According to GitHub issue #403 in LabsConnected/litlabs-website, an .ico or .jpeg asset read as UTF-8 produced lone surrogates, and the whole deployment failed at the file-write step with unsupported Unicode escape sequence. The issue’s suggested direction is to base64-encode binary assets before the write, reject or sanitize non-text-safe content with a per-file error naming the offending path, and add a regression test. For URL paths, MDN’s recommendation is to pass the string through String.prototype.toWellFormed() — or check isWellFormed() first — before calling encodeURI().

    Three-step sanitize-before-write flow: drop NUL, keep pairs, encode binary

    The impact justifies the guard rails. Issue #1493 reports that a single NUL character or lone surrogate aborts an entire session run, destroying 3–4 already-generated lessons per occurrence during batch course generation on PostgreSQL 16.11 with Node v24.18.1. Issue #403 reports that one bad binary file fails an entire deployment because there is no per-file guard or fallback. Per-record and per-file checks with a fallback path limit the blast radius.

    When a Failed Record Cannot Even Be Logged as Failed

    There is a second-order failure mode that few write-ups mention: the system cannot even record that it failed. According to GitHub issue #901 in readur/readur, the null-byte guardrail added in PR #308 / v2.6.0 does not cover every database write path. On the current latest image, PDFs whose OCR text contains \u0000 still fail, and the follow-up attempt to insert into failed_documents was itself rejected — this time by a check_failure_reason constraint.

    The result is a document that is permanently stuck. It cannot be ingested, it cannot be logged as failed, and it therefore never appears in the “Failed OCR” UI, so the retry function cannot pick it up. A prior database inspection in the same issue showed 105 rows stuck in pending in ocr_queue, and manually resetting statuses did not help because ingestion fails before a queue entry is created.

    The issue’s expected behavior is a reasonable template for any pipeline that stores escape-bearing text: sanitize before any database write, including the failure-logging path; fall back to a generic failure reason instead of raising a constraint violation that masks the original error; and always persist failed records so they remain visible and retryable.

    Reading Escapes You Didn’t Write: Literal \u00e9 Text vs. Mojibake

    Not everyone arriving at this topic is writing escapes. Some are staring at a literal \u00e9 in a dialog box, or at café in a string, and trying to work out whether the escape was never interpreted or interpreted one time too many. Pasting the escape into a Unicode escape decoder confirms what the four hex digits name; what follows is about why the surrounding text went wrong.

    Symptom Likely cause One-line check
    \u00e9 appears as literal text to a human The layer rendering it does not interpret \u, or the text was escaped for one context and injected into another, such as JavaScript-escaped text placed into an HTML attribute Does the layer that displays the string know how to interpret a \u prefix?
    café instead of café A string that was already decoded got decoded again with the wrong encoding — typically UTF-8 bytes read as latin-1 Compare the character count against the expected value and look for à or  where accented letters belong
    The escape resolves correctly but the non-ASCII text beside it is destroyed A codec that expects bytes was applied to a str Check what input type the codec expects before calling it

    Two recent reports map cleanly onto the first and third rows. According to GitHub issue #17357 in mautic/mautic, a confirmation cancel button label stored through a data attribute renders as literal \uXXXX text in the Russian locale instead of the localized word; the proposed fix is to render the label with HTML-attribute escaping rather than JavaScript escaping, and to read it in JavaScript instead of passing HTML content through a data attribute.

    According to GitHub issue #53 in colinta/SublimeStringEncode, a Unicode Escape command built on codecs.decode(text, 'unicode-escape') corrupts every non-ASCII character in the selection, because the codec takes bytes and the plugin’s str is first encoded to UTF-8 and then decoded as latin-1. Selecting café produces café, and selecting \u00e9 é produces é é — the escape decodes correctly while the literal é next to it is destroyed.

    The reusable rule is to identify what the current layer expects before changing anything. Confirm whether that layer consumes escape text or already-decoded characters, then fix that layer, rather than re-encoding repeatedly at the wrong level.

    Which Edition and Version Should You Cite?

    Version context across the current search results is thin and in places self-contradictory. The only Java source surfaced for this topic is the Java SE 7 specification rather than the current edition. Wikipedia’s character list states that Unicode 18.0 assigns 310,351 characters, yet elsewhere on the same page cites Unicode 17.0 for the number of characters classified as Latin script — two different versions in one article. Only the MDN pages display current revision dates, both last modified on September 2, 2026.

    The practical rule is to name the version on every citation rather than treating any edition as “the current rule.” Where a rule has been stable across editions — such as the processing order of Unicode escapes and the non-recursive expansion rule, both of which come from JLS §3.3 and are stated in the same terms in the Java SE 7 edition cited here — say so explicitly and attribute the source. That way a reader is not misled by an older edition’s wording.

    Character counts must be version-bound for the same reason. The figure of 310,351 assigned characters across 175 scripts is a Unicode 18.0 figure and changes with each version of the standard, so it should not be mixed with counts drawn from an earlier release.

    Conclusion

    A Unicode escape sequence is just a notation for writing any Unicode character in ASCII — but the notation takes different forms in Java, JavaScript, JSON, HTML, and URLs, and the edge cases are where it breaks. Surrogate pairs and U+0000 are the two boundaries that cause most real incidents. Start by identifying which of the four escape families you are holding, using the cross-context table above. Before any database write, sanitize at the in-memory string level with a JSON.stringify replacer: drop \u0000, keep paired surrogates intact, and base64-encode binary assets. When you see literal \uXXXX text or café, determine whether the string was never interpreted or interpreted twice, then fix that specific layer.

    FAQ

    What is the difference between a Unicode escape sequence, an HTML numeric character reference (&#xhhhh;), and URL percent-encoding (%XX)?

    They encode different things. \uXXXX encodes a code point, or a UTF-16 code unit in languages that use UTF-16. &#xhhhh; is a markup character reference resolved by an HTML or XML parser. %XX encodes UTF-8 bytes, so one non-ASCII character can become several %XX groups. Reading the prefix — \u, \p, &#x, or % — tells you which system must interpret the text.

    Why do emoji and other supplementary characters need two \uXXXX escapes instead of one?

    One \uXXXX escape writes a single UTF-16 code unit, and its four hexadecimal digits cannot express anything above U+FFFF. Characters above that boundary are stored in UTF-16 as a high surrogate plus a low surrogate, so they need two consecutive escapes. U+1F600 is written \uD83D\uDE00: two escapes, one character. Delete either half and you have a lone surrogate.

    Why does PostgreSQL reject my data with “unsupported Unicode escape sequence”?

    The error carries SQLSTATE 22P05, and it triggers on a payload containing \u0000 (NUL) or a lone surrogate such as \ud800. It does not reject all control characters — \u0001 and \u007f write successfully, and a paired surrogate like \ud83d\ude00 is accepted. The usual source is JSON.stringify emitting those escapes verbatim, so sanitize the in-memory string before the write. To see which escapes a failing payload actually contains, run it through an online Unicode decoder first.

    How many hexadecimal digits does \uXXXX require, and can extra u characters be added?

    The standard form is \u followed by exactly four hexadecimal digits. Java permits a repeated u marker, so \uuuu0041 is legal, but the digit count is unchanged. Expansion is not recursive: \u005cu005a produces the six literal characters \ u 0 0 5 a, not Z. The \u{...} form belongs to JavaScript’s supplementary-character syntax, not to an extended \uXXXX.

    What is the escape character U+001B, and why is this notation called “escape”?

    U+001B is ASCII 27 in decimal, Unicode U+001B, and the Ctrl+[ combination — the character the Esc key produces. Wikipedia’s article on the Esc key attributes the idea of putting that functionality into a character-encoding convention, and calling it escape, to Bob Bemer’s contributions to ASCII around 1960. Terminals used it to begin control sequences; \u001b today is that control character itself.

  • Birthday Facts: 60+ Verified Stats, Month Data & History

    Birthday Facts: 60+ Verified Stats, Month Data & History

    Header: abstract visualization of birthday data and calendar patterns

    A birthday is the yearly anniversary of a person’s birth, marked with cake, candles, gifts, and songs. Here are the birthday facts worth knowing first: just 23 people give a 50.7% chance of a shared birthday, and September 16 is the most common US birthday. Sources and dates appear throughout.

    What Are Birthday Facts? Definition, Scope, and How We Verify Them

    Birthday facts cover a narrower, more testable territory than most birthday-themed pages suggest. This guide sticks to statistics, month symbols, celebrity birthdays, history, and probability math — and leaves out anything that can’t be traced to a named source.

    The one-sentence definition of a birthday (and why dates, not hours, matter)

    A birthday is the anniversary of a person’s birth — or, figuratively, the birth of an institution — as Wikipedia defines it. The distinction that matters for everything below is between a birth day and a birth date. The birth day comes around every year: January 15 is January 15. The birth date is the complete timestamp, like January 15, 2001. Paste that timestamp into a birthday calculator and you get both back at once: the day of the week you were born, your zodiac sign and birthstone, and how many days remain until the next anniversary.

    That calendar-based reckoning — not an hour-by-hour count — is exactly what makes the birthday paradox work. Two people match if they share a month and day, no matter what year they were born.

    What counts as a birthday fact — and what we leave out

    This guide sticks to five verifiable categories: statistical distributions and rankings; birth month symbols (zodiac sign, birthstone, birth flowers); celebrity birthdays and age calculation; history and cultural practice; and probability math.

    Deliberately excluded: any claim that a birth month determines personality, destiny, or guaranteed health outcomes. Birth month associations do surface occasionally as weak, dated correlations in research, and those show up in Chapter 7 with their sample years attached — never as predictions about a specific person.

    One reader trap worth flagging early: sharing a birthday with someone does not mean sharing a birth year. Working out age always takes the birth year plus today’s date.

    How we source and date every fact in this guide

    Every data point below carries its source and, where relevant, its year. Statements fall into two buckets: historical analyses (such as the 2006 New York Times birth-date table) and current facts (such as Google’s 2026 anniversary count).

    When a study is more than a few years old, treat it as a reference value, not a snapshot of the present. That rule applies to the 2011 longevity research and the 2014 athletic-development reporting cited later — both still useful, neither a current-year finding.

    Birthday Statistics: The Most Common Birthday and Why the Calendar Isn’t Flat

    If you only remember one number from this section, make it this: September 16 is the most common birthday in the United States. Everything else here explains why the calendar year is lopsided instead of evenly spread — and which dates sit down at the low end.

    What is the most common birthday in the United States?

    Researchers at Harvard University analyzed US birth records and found that September 16 is the most common birthday in the United States — with September 9 right behind at No. 2 — as reported by The New York Times in 2006.

    That dataset is still the most widely cited baseline for US birth-date distribution, which is why the year stays attached here. It’s a historical analysis, not a live count — if you need current-year figures, check the latest official natality statistics.

    September is also the peak birth month overall in the US, not just a single standout date. The busiest stretch of the year runs through late summer and early fall.

    One more headline number, as a preview: According to Wikipedia’s “Birthday problem” entry, 23 people are enough for a 50.7% chance that two of them share a birthday, and 70 people push that probability to 99.9%. The full derivation is in Chapter 5.

    Why birth dates cluster: seasonality, holidays, and scheduled births

    US birth dates aren’t evenly spread, and the causes are mostly mechanical rather than mystical.

    Conception seasonality is the first driver. A peak in conceptions nine months earlier shows up as a peak in births — part of why the September window carries so much volume.

    Scheduling is the second. Planned inductions and C-sections tend to avoid weekends and major holidays, which pushes births down on dates like December 25 and January 1 and concentrates them on nearby weekdays. Hospital staffing and operating-room calendars reinforce the same pattern.

    So when someone asks why their birthday feels like it keeps colliding with other people’s, the answer is usually that it sits inside one of these high-volume weekday clusters, not on a holiday.

    The rarest birthdays: February 29 and December 25

    February 29 is the rarest birthday on the calendar because it only exists in leap years. As Wikipedia notes, it’s the one date that doesn’t occur annually — every other birth day comes back each year regardless of the calendar cycle.

    Roughly speaking, that date appears about once every 1,461 days, which is why people born on it accumulate “real” birthdays at about a quarter of everyone else’s rate. Chapter 7 covers how that affects legal age and ID renewals in the US.

    December 25 sits at the opposite end for a different reason. It’s a real, annual date, but births on it get pushed down by the same holiday-avoidance scheduling that lifts weekday counts elsewhere. The practical upshot: fewer people share Christmas as a birthday than the calendar’s symmetry would suggest.

    US birth date distribution showing peak (Sep 16) and low-volume dates

    Birth Month Facts: Zodiac Signs, Birthstones, and Birth Flowers for All 12 Months

    Most sites split zodiac signs, birthstones, and birth flowers across three separate pages. The table below puts all three side by side so one lookup answers the whole thing.

    The 12-month table: zodiac sign, birthstone, and birth flowers side by side

    The zodiac ranges below follow the conventional Western sun-sign boundaries used by the Random Birthday Generator. Birthstones follow traditional month associations.

    Month Zodiac sign (conventional range) Birthstone Birth flower(s)
    January Capricorn (Dec 22–Jan 19), Aquarius (Jan 20–Feb 18) Garnet Carnation, snowdrop
    February Aquarius (Jan 20–Feb 18), Pisces (Feb 19–Mar 20) Amethyst Violet, primrose
    March Pisces (Feb 19–Mar 20), Aries (Mar 21–Apr 19) Aquamarine Daffodil, jonquil
    April Aries (Mar 21–Apr 19), Taurus (Apr 20–May 20) Diamond Daisy, sweet pea
    May Taurus (Apr 20–May 20), Gemini (May 21–Jun 20) Emerald Lily of the valley, hawthorn
    June Gemini (May 21–Jun 20), Cancer (Jun 21–Jul 22) Pearl, alexandrite Rose, honeysuckle
    July Cancer (Jun 21–Jul 22), Leo (Jul 23–Aug 22) Ruby Larkspur, water lily
    August Leo (Jul 23–Aug 22), Virgo (Aug 23–Sep 22) Peridot, spinel Gladiolus, poppy
    September Virgo (Aug 23–Sep 22), Libra (Sep 23–Oct 22) Sapphire Aster, morning glory
    October Libra (Sep 23–Oct 22), Scorpio (Oct 23–Nov 21) Opal, tourmaline Marigold, cosmos
    November Scorpio (Oct 23–Nov 21), Sagittarius (Nov 22–Dec 21) Topaz, citrine Chrysanthemum, peony
    December Sagittarius (Nov 22–Dec 21), Capricorn (Dec 22–Jan 19) Turquoise, zircon Narcissus, holly

    Two boundary details matter because people commonly get them wrong. Libra covers September 23 through October 22, and Scorpio begins October 23 — the switch does not happen at mid-month. Likewise, Virgo runs from August 23 through September 22, and Leo covers July 23 through August 22.

    People born within a day or two of a boundary are often called “on the cusp” — a label the generator notes is conventional, not scientific.

    October birthday facts: opal, tourmaline, marigold, and the Libra-to-Scorpio cusp

    October is one of the symbol-richest months of the year, carrying two birthstones, two birth flowers, and a zodiac split.

    October babies have two birthstones — opal and tourmaline — according to Happiest Baby. Opal is known for its color-shifting quality, while tourmaline comes in multiple shades: black tourmaline is associated with confidence and protection, pink tourmaline with love and compassion, and green tourmaline with strength and stamina.

    The month’s two birth flowers are marigold and cosmos. Marigolds, also called calendula, show up frequently in healing lotions, and cosmos is the second traditional bloom for October.

    Zodiac placement splits cleanly: birthdays through October 22 fall under Libra, and October 23 onward falls under Scorpio. Since the current date is early October 2026, anyone born this month sits in the Libra-to-Scorpio transition window and inherits both the dual gems and the dual flowers.

    September birthday facts: the most common birth month’s symbols

    September’s birthstone is sapphire, traditionally linked with wisdom, sincerity, and faithfulness. The classic sapphire is deep blue, though the gem appears in several colors.

    September also carries two birth flowers — aster and morning glory. Asters have daisy-like blooms often tied to love and wisdom, while morning glories are known for colorful, trumpet-shaped flowers.

    The September zodiac split runs Virgo through September 22 and Libra from September 23 onward. Add in September 16’s status as the most common US birthday, and the month pairs unusually high birth volume with a full set of symbols.

    Do birth months predict personality or health?

    Birth month and personality are not connected in any way this guide treats as established. Zodiac descriptions are traditionally assigned traits, and the generator itself labels its zodiac ranges as conventional rather than scientific.

    The health and performance research that does exist is correlational and date-stamped. Two examples appear in Chapter 7 — a 2011 longevity study and 2014 reporting on athletic development — and both come with specific samples, years, and caveats.

    The honest summary: birth month is a real, useful label for symbols and statistics. It is a weak, heavily qualified variable for anything about the actual person.

    Celebrity Birthdays: How Age Is Calculated and Why ‘Famous Birthdays’ Became a Data Business

    Celebrity birthday pages look simple, but they contain one recurring arithmetic trap. Reading them correctly takes about ten seconds of subtraction.

    How to calculate a celebrity’s age in 2026

    The rule: read the birth year first, then compare today’s date against the birthday. If the birthday has already passed this year, age equals current year minus birth year. If it hasn’t arrived yet, subtract one more.

    Keanu Reeves was born on September 2, 1964. As of September 2, 2026, he turns 62; before that date in 2026, he was 61. That parenthetical format — age shown as current-until-birthday — is the standard convention on celebrity birthday pages, and it’s why the same page can show two different numbers a week apart. To skip the subtraction, an online age calculator applies the same rule automatically: enter a birth date and it reads out the exact age as of today.

    The same logic applies across the board. Andrea Bocelli, Joan Jett, and Tom Felton all share a September 22 birthday, and Bored Panda’s 2026 list records their ages as 68, 68, and 39 respectively — numbers that only hold from that date forward until the next birthday.

    Simple 3-step age calculation decision flow

    Inside the Famous Birthdays catalog: scale and influence

    Famous Birthdays is an American website based in Santa Monica, California, dedicated to cataloging famous people’s birthdays alongside other biographical facts.

    Its history has two distinct phases. The original site was created by Edward Morykwas, a Michigan schoolteacher, in 1996, and it offered e-cards. The current format launched on November 7, 2012, under Evan Britton, who has described the site as “Wikipedia for Generation Z.”

    The scale figures are the part worth keeping dated: as of January 2018, it held over 150,000 biographies, and as of June 2024, it drew 20 million unique visitors each month.

    Its cultural weight is a separate matter. Journalist Taylor Lorenz, writing in 2019, described a Famous Birthdays page as a “status symbol” or “badge of honor” for internet personalities, noting the site’s teenage and Generation Z audience. The site’s growth tracked a shift from traditional celebrities toward internet personalities, after Britton noticed visitors searching for people he did not recognize.

    How to read a celebrity birthday list critically

    Celebrity birthday roundups are frequently AI-assisted or user-submitted. The Bored Panda list cited above carries an explicit “AI-assisted post” label and credits Wikimedia Commons for its images — a transparency practice worth checking for.

    For casual sharing, that’s fine. For citation, the reliable move is to trace the birth date back to a primary or well-documented secondary source rather than repeating the aggregator.

    Age deserves a second caution. Any list that hard-codes an age without a reference date will drift out of accuracy within twelve months. Treat every stated age as valid only for the date it was published.

    The Birthday Paradox: The Math That Makes Birthday Facts Feel Impossible

    This is the part of birthday math that reliably surprises people, and it’s genuinely counterintuitive — not a trick.

    The birthday paradox in numbers: 23 people, 253 pairs, 50.7%

    According to Wikipedia’s “Birthday problem” entry, in a group of 23 randomly chosen people, the probability that at least two share a birthday is 50.7%. At 70 people, it reaches 99.9%. At 366, a repeat is guaranteed.

    Why it feels wrong: your intuition is answering a different question. People mentally calculate the chance that someone shares their birthday, which stays low. The actual problem compares every possible pair.

    With 23 people, there are 23 × 22 ÷ 2 = 253 pairs to consider. That’s the whole trick: 253 comparisons at roughly a 1-in-365 match rate each produces a coin-flip outcome.

    Wikipedia’s probability table lays out the curve: 5 people give 2.7%, 10 give 11.7%, 23 give 50.7%, 30 give 70.6%, 50 give 97.0%, and 70 give 99.9%. The problem is generally attributed to Harold Davenport around 1927, though the first published version came from Richard von Mises in 1939.

    Birthday paradox: 23 people creating 253 pairs to reach 50.7% probability

    Real-world proof: shared birthdays among the Apollo astronauts

    The most frequently cited real-world example comes from the lunar astronauts. Among 24 Apollo astronauts, there are 276 comparable pairings, and 3 of those turn out to be shared birthdays — as illustrated in the birthday-attack comparison chart in Wikipedia’s birthday problem article.

    That’s a small sample behaving exactly as the math predicts, and it makes a clean classroom demonstration: the group is small enough to list by name and large enough that the match isn’t a fluke.

    Why tech cares: birthday attacks, hash collisions, and test data

    The same structure that produces party surprises also breaks cryptographic assumptions. The birthday attack uses this probabilistic model to cut down the complexity of finding a collision for a hash function, and the same math estimates collision risk for a given population size.

    The practical rule: the expected number of N-bit hashes generated before a collision is not 2^N but roughly 2^(N/2). Wikipedia’s comparison table shows the collision thresholds across hash sizes, with the birthday problem placed alongside a SHA-256 example using 16 variants each of benign and harmful contracts — 1 collision appeared out of 256 pairings.

    The birthday problem has non-security uses too. It has been applied under the name capture-recapture statistics to estimate fish populations in lakes, and it’s a standard tool for modeling coincidences and for stress-testing data pipelines where duplicate keys are assumed to be rare.

    Birthday History and Culture: Cake, Candles, Wishes, and Coming-of-Age Milestones

    Modern birthday customs blend ancient ritual, medieval naming practice, and industrial-era economics.

    Where birthday cake and candles come from

    One origin thread traces the candle-topped cake to ancient Greece, where round cakes topped with lit candles were offered to Artemis, with the round shape referencing the moon. A second thread runs through 18th-century Germany and the Kinderfeste tradition, where a cake with candles marked a child’s birthday.

    The most repeated explanation — that the smoke carries the wish to the gods — is an inherited piece of custom rather than a documented historical fact, and it should be described that way.

    The mechanics of the modern wish are better documented. As Wikipedia notes, a birthday cake may be decorated with the person’s name and age, or studded with as many lit candles as the person’s age. The celebrant makes a silent wish and tries to blow out every candle in one breath; if they succeed, superstition holds the wish will be granted. In many cultures the wish has to stay secret or it won’t come true.

    The shift from aristocratic custom to mass practice came with economics. Falling sugar prices after the Industrial Revolution and the spread of commercial baking made cake affordable well beyond the nobility.

    Coming-of-age birthdays: Sweet 16, quinceañera, bar/bat mitzvah

    Different cultures mark the same biological milestone with different birthdays and different ceremonies.

    In Canada and the United States, families often mark a girl’s 16th birthday with a “sweet sixteen” celebration — something popular culture has reinforced heavily. In some Hispanic countries and in Brazil, the quinceañera — or festa de quinze anos — traditionally marks a girl’s 15th birthday.

    Jewish boys have a bar mitzvah on their 13th birthday. Jewish girls have a bat mitzvah on their 12th birthday, or sometimes on their 13th in Reform and Conservative Judaism. As Wikipedia explains, this marks the transition where they become obligated in commandments from which they were previously exempted and are counted as part of the community.

    Japan’s Coming of Age Day celebrates everyone who has turned 18. The Philippines holds a debut for young women at 18 and young men at 21. Korea marks both Baek-il, the 100th-day feast, and Doljanchi, the child’s first birthday.

    How different countries mark the same day

    The core legal concept is shared even where customs diverge. In most legal systems, a person becomes a legal adult on the birthday when they reach the age of majority — usually somewhere between 12 and 21 — and specific ages unlock specific rights: leaving full-time education, military enlistment, marriage with or without parental consent, voting, running for office, buying alcohol or tobacco, buying lottery tickets, or getting a driver’s license.

    Some places complicate the counting itself. In China, traditional birthdays were reckoned using the lunisolar calendar, which can vary from the Gregorian calendar by as much as a month in either direction; celebrating the lunisolar birthday remains common in Taiwan while growing less common on the mainland. South Korea used multiple age systems until June 2023, when all Korean ages were set back at least one year and official ages became reckoned only by birthdays.

    One more wrinkle worth knowing: many cultures also observe a name day, or saint’s day — celebrated much like a birthday, but keyed to the saint sharing the person’s name rather than their birth date.

    US Birthday Facts: Peak Dates, Age Milestones, and Being Born on February 29

    This section concentrates the US-specific data readers most often need to cite, with each figure’s year attached.

    US birth distribution: peak months and the quietest dates

    The headline US figure is still September 16 as the most common birthday, based on a Harvard University analysis of US birth records reported by The New York Times in 2006. September is the busiest birth month overall.

    The quietest stretch of the calendar runs through weekends and major holidays, where scheduled deliveries are deliberately steered away. December 25 and January 1 are the standard examples. February 29 is the rarest date overall because it only exists in leap years.

    Cross-referencing with symbol data adds a practical detail: a September 16 birthday falls under Virgo (Virgo runs through September 22), carries sapphire as a birthstone, and picks up aster and morning glory as birth flowers.

    Age milestones in the US: what actually changes at 18 and 21

    Two ages carry the most cultural weight in the US. Eighteen is generally when voting rights and legal adulthood arrive in most states; 21 is when the drinking age applies nationwide.

    Beyond those two, the picture fragments. Renting a car, signing a contract, buying a firearm, and other rights vary by state — and whether a right activates on the birthday itself or on a different administrative date depends on the jurisdiction and the specific law.

    The safe way to phrase any of these: reaching 18 or 21 marks the general threshold, but the exact effective date and scope should be checked against the relevant state’s rules, not assumed.

    February 29 births create a set of small but real administrative questions. Because the date doesn’t occur in non-leap years, US practice commonly treats February 29 babies as reaching a given age on March 1 or February 28 of non-leap years for legal and identification purposes.

    The generator tool’s software convention offers a useful contrast: it advances February 29 ages on March 1 in non-leap years, and explicitly labels that as a software convention rather than a legal age rule. That distinction is worth keeping — agencies and systems don’t all handle it the same way, so a leap-day birthday is one case where checking the specific rule ahead of time saves trouble.

    The celebratory math is simpler. A February 29 baby accumulates roughly one quarter as many “actual” birthdays as peers of the same age, which is why many choose February 28 or March 1 for parties in common years.

    One more US data point worth carrying with its year: a 2011 study in the Journal of Aging Research found that people born from September to November were more likely to reach age 100 than those born in other months. The study compared American centenarians with their siblings and spouses, and it’s a historical analysis rather than a current-year finding.

    A second dated finding: research reported by The Guardian in 2014 indicated that autumn-born children showed stronger athletic performance, with the leading explanation being the “relative age effect” — being older and bigger than classmates within the same school cohort. Both findings are correlational, and neither predicts an individual outcome.

    Time-Sensitive Birthday Facts for 2026: Google’s Birthday and Today’s Celebrity Lineup

    This section holds the numbers that change from year to year. Last updated: October 2026.

    When is Google’s birthday, and how old is it in 2026?

    Google’s birthday has a genuine ambiguity built into it. The company was incorporated on September 4, 1998, but it officially celebrates its birthday on September 27 each year — and ClickOnCare’s 2026 milestone summary notes that tradition has been tied to September 27, with the celebration reported as running since 2002.

    In 2026, Google marks its 28th birthday. The 1996 predecessor project, “Backrub,” was built by Larry Page and Sergey Brin at Stanford; the domain google.com was registered in 1997, and the company was officially founded in 1998.

    That gap between incorporation date and celebration date is the interesting part. A business can pick a birthday; a person can’t.

    Today’s celebrity birthdays: how to keep this section current

    Daily celebrity birthday lists exist at scale. Bored Panda maintains a running Celebrity Birthdays hub with daily posts, and the September 22, 2026 edition lists ten figures: Andrea Bocelli, Joan Jett, Tom Felton, Tatiana Maslany, Billie Piper, Bonnie Hunt, Nick Cave, Teyonah Parris, Mireille Enos, and Jessie Murph.

    The ages in that list — 68, 68, 39, 41, 44, 65, 69, 39, 51, and 22 — were correct as of September 22, 2026 and change on each person’s next birthday. Apply the Chapter 4 formula instead of copying the number.

    This is the section readers should re-check rather than trust from memory. Any age, anniversary count, or daily lineup listed here carries an implicit expiration date.

    Global birthday traditions: cake, candles, and coming-of-age ceremonies

    How to Use These Birthday Facts: Party Icebreakers, Classroom Math, and Content Ideas

    The data above works better as an activity than as a fact list. Here are three settings where it shines, plus one tool that removes the manual labor.

    Party and classroom activities using birthday statistics

    The strongest opener is the 50.7% figure from Wikipedia’s birthday problem entry. At a gathering of 23 or more, announce the number, then have guests pair up and compare birthdays. The result validates the paradox live, and the explanation — 253 pairs, not 22 comparisons — is the payoff.

    For a classroom, run the same activity, then move to the Apollo astronaut case: 24 astronauts, 276 pairings, 3 shared birthdays. Students can check the predicted range against a real, nameable group, which turns an abstract probability lesson into a data-checking exercise.

    The extension for advanced groups is the birthday attack. Same math, different stakes: a collision that’s a party trick in one context is a security vulnerability in another.

    Generating sample birthday data for tests, games, and content

    Manual birthday generation doesn’t scale. The Random Birthday Generator produces fictional dates in batches of up to 1,000, with three generation modes: age range, custom date range, or month-and-day only (no birth year).

    Each result can include the date, calculated age, weekday, Western zodiac sign, and birthstone. Exports come as CSV or JSON, and there’s a no-duplicates option plus an explicit February 29 toggle. Everything runs in the browser — the tool states that generation, exports, and card creation happen on the user’s device, with no account required.

    The intended uses are character profiles, tabletop games, form and calendar testing, and classroom sampling. The tool’s own documentation is clear that results are fictional sample data and should never be used as identity information, for verification, or in official records.

    One implementation detail worth knowing if you’re building on top of it: the tool labels its zodiac ranges as approximate Western sun-sign dates intended for entertainment, and its birthstones as traditional month associations.

    Content and quiz ideas built on birth month symbols

    The 12-month table in Chapter 3 is designed to be reused directly. Three recurring formats work well:

    • Month symbol posts. One month per post, combining its zodiac range, birthstone, and birth flowers. Chapter 3 covers September and October as worked examples.
    • Same-day challenges. Pair a shared birthday (like September 22, 2026) with the ages and the paradox math to produce a “who else shares your day” post.
    • Quiz questions. Turn the probability table into a five-question quiz: how many people for 50.7%? How many for 99.9%? How many pairings exist among 23 people?

    Any content built this way should carry its source and year, exactly as this guide does.

    Conclusion

    Birthday facts are a set of verifiable data points: a 50.7% shared-birthday chance at just 23 people, September 16 as the most common US birthday, and a full 12-month table of zodiac signs, birthstones, and birth flowers. Use this guide selectively — cite Chapters 2 and 7 for US statistics with their years attached, run the Chapter 9 activities for parties and classrooms, and export CSV or JSON from the generator when you need sample data in bulk. Any number that changes over time should be re-checked against the last-updated date noted in each section.

    FAQ

    What is the most common birthday in the United States?

    September 16, according to a Harvard University analysis of US birth records reported by The New York Times in 2006. September 9 is a close second in the same dataset. September as a whole is the peak birth month, while weekends and major holidays see noticeably lower birth rates because scheduled deliveries avoid them. That figure is a historical dataset — check current official natality statistics for year-by-year data.

    How many people need to be in a room for a 50% chance of a shared birthday?

    Twenty-three people produce a 50.7% probability. The reason: the comparison covers every pair, not just one person against the rest — 23 people create 253 pairs. At 70 people the probability reaches 99.9%, and at 366 a repeat is guaranteed. Among 24 Apollo astronauts, 3 shared birthdays appeared across 276 pairings.

    Which birthstones and birth flowers belong to October babies?

    October carries two birthstones, opal and tourmaline, and two birth flowers, marigold and cosmos. Opal is known for its shifting color, and tourmaline appears in black, pink, and green varieties. On the zodiac side, Libra runs through October 22 and Scorpio begins October 23, so an October birthday falls on one side of that split.

    Why do we make a wish and blow out candles on a birthday cake?

    One origin thread traces the practice to ancient Greece, where round cakes with lit candles were offered to Artemis — the round shape referencing the moon. A second thread runs through the 18th-century German Kinderfeste tradition of a candle-topped cake. The popular explanation that smoke carries the wish to the gods is inherited custom rather than documented history.

    When is Google’s birthday, and how old is Google in 2026?

    Google was incorporated on September 4, 1998, but officially celebrates its birthday on September 27, a tradition reported as running since 2002. In 2026, Google marks its 28th birthday. The split between incorporation date and celebration date is common for companies, and contrasts with a person’s single legal birth date.

  • Compress BMP Files: 3 Proven Ways to Shrink Them Fast

    Compress BMP Files: 3 Proven Ways to Shrink Them Fast

    Header: A large BMP file becoming smaller PNG, WebP, and JPG files

    BMP stores every pixel uncompressed, so you can’t compress BMP much while keeping the .bmp extension. The practical fix is to re-encode as PNG or WebP for lossless savings, or JPG for photos — usually cutting file size by more than half.

    How to Compress a BMP File: The Three Paths That Actually Work

    Before you open a tool, know that “compress BMP” isn’t a single operation. There are three real paths, and only one of them keeps the .bmp extension. Pick the wrong one, and you can spend an hour dragging sliders only to end up with a file that’s barely smaller.

    Path A — re-encode to PNG or WebP. This is lossless re-encoding. Every pixel you get back matches the one that went in, but the file is usually 60–80% smaller. Why? The encoder removes redundancy BMP never bothered to remove. It’s the best fit for screenshots, line art, logos, and CAD or GIS exports.

    Path B — re-encode to JPG. This is lossy, and it gives you the smallest file for photographs. It also adds visible ringing and blocking around text and hard edges, which is why it’s a poor choice for anything that looks like a diagram.

    Path C — keep the .bmp extension. ZIP or Deflate archiving, RLE encoding, or reducing bit depth and DPI. These are real, working options, but the savings are modest compared with a format change.

    The one-line decision shortcut: photograph → JPG or WebP; screenshot, line art, or scan → PNG; web page asset → WebP; must stay .bmp → ZIP or RLE.

    Three-path BMP compression decision flow

    Path A: Re-encode to PNG or WebP (Lossless)

    PNG is the default lossless target. It applies Deflate compression to the raw pixel data, and according to CoolUtils, that cuts BMP file size by 60–80% with no quality difference. WebP offers a lossless mode that generally goes smaller still, and it is supported by every current major browser.

    Because nothing is discarded, this path is safe for images where accuracy matters: screenshots of application UIs, scanned pages that need to stay legible, monochrome technical drawings, and exported maps. You can verify the result by opening both files side by side at 100% zoom — they should be indistinguishable.

    Path B: Re-encode to JPG (Smallest, Photos Only)

    JPG wins on raw byte count for photographs, where smooth gradients and fine noise tolerate lossy compression well. The trade-off is real but localized. Compression artifacts appear first around sharp transitions, which is precisely where text, table borders, and thin vector-like lines live.

    Use JPG for camera output and continuous-tone imagery. Do not use it for screenshots of documents, terminal windows, or CAD drawings — the text becomes fuzzy at exactly the zoom level people use to read it.

    Path C: Keep the .bmp Extension (Limited but Possible)

    Some pipelines cannot accept PNG. Legacy Windows software, industrial control panels, and older medical imaging systems expect raw bitmap data, and swapping the extension breaks the workflow. In that case your options are general-purpose lossless archiving, BMP’s own RLE encoding for indexed images, or reducing the bit depth or pixel dimensions. Each works; none gets you close to what PNG would deliver. The next section covers each in detail.

    Why BMP Files Are So Large: The Windows Bitmap and Its Uncompressed Pixels

    BMP is one of the oldest image formats on the IBM PC. According to Wikipedia, the format was first released by Microsoft in December 1987, and the modern file structure most applications write today arrived with Windows 3.0 in 1990. Its history is visible in the header sizes: the 12-byte BITMAPCOREHEADER was the original, the 40-byte BITMAPINFOHEADER came with Windows 3.0 in 1990, the 108-byte BITMAPV4HEADER arrived with Windows 95 and NT 4.0, and the 124-byte BITMAPV5HEADER came with Windows 98 and Windows 2000.

    The reason for the size problem sits in the pixel format, not the header. BMP defaults to BI_RGB, meaning every pixel is stored literally on disk. There is no entropy-coding step, no dictionary, no prediction — nothing that looks at the image as a whole and removes repetition. The bytes on disk are essentially a dump of the frame buffer.

    This reframes the entire task: “compressing” a BMP is really a re-encoding decision. It is not a quality slider you drag until the number gets small enough.

    The Pixel Array, Row Padding, and the Size Formula

    For an uncompressed bitmap, the pixel array is written as successive scan lines, each rounded up to a multiple of 4 bytes — the padding is called the stride, and the pad bytes are not necessarily zero. Total pixel data lands at roughly width × height × bytes-per-pixel, plus padding overhead. Color tables, when present for indexed images, add a small fixed amount.

    That formula is also the diagnostic. If a file is unexpectedly huge, either the pixel dimensions are large, the bit depth is 24 or 32, or both. There is nothing hidden to blame.

    Bit Depth and DPI: Why a 300 DPI Scan Hits 25 MB

    Size scales with both bit depth and resolution, and print-oriented scans push both up at once. CoolUtils puts a single A4 page rendered at 150 DPI (1240 × 1754 pixels, 24-bit color) at roughly 6 MB as a BMP. The same page at 300 DPI reaches about 25 MB.

    A 300 DPI A4 page is 2480 × 3508 pixels — four times the pixel count of the 150 DPI version — and at 24 bits per pixel that multiplication lands directly on the file size. This is why scanned documents and PDF-to-BMP exports produce files that resist email attachment limits.

    A4 BMP size at 150 DPI vs 300 DPI

    Compressing a BMP Without Changing the Format

    This is the question most tool pages skip: sometimes the extension simply cannot change. Legacy Windows applications such as Paint, older medical imaging software, and industrial control panels expect raw bitmap data rather than a compressed image, and a PNG renamed to .bmp will not load. If you are in that situation, four options remain.

    Option 1 — general-purpose lossless archiving. Wikipedia notes that because uncompressed BMP files hold a great deal of redundant data, they can often be reduced substantially by general-purpose lossless compression such as ZIP or RAR. Nothing about the image changes; you simply wrap it in a container that removes the repetition. The downside is that the recipient must decompress before opening.

    Option 2 — BMP’s own RLE encoding. BI_RLE4 and BI_RLE8 are run-length encoding modes defined in the format itself. They are limited to 4-bit and 8-bit indexed-color images, which excludes most contemporary content.

    Option 3 — reduce bit depth. Dropping 24-bit true color to an 8-bit indexed palette cuts pixel data by roughly two-thirds. It only works cleanly when the image genuinely uses few distinct colors — screenshots of text, monochrome line art, simple diagrams.

    Option 4 — crop or downsample. Fewer pixels is the only guaranteed byte reduction, but it changes the image dimensions rather than compressing it.

    Set expectations honestly: staying inside .bmp caps your achievable savings well below what PNG or WebP would give you on the same file.

    ZIP and Deflate: Lossless Shrinking Without Touching a Pixel

    ZIP is the safest option because it is fully reversible and requires no format knowledge. The compression ratio depends on how repetitive the pixel data is — a flat white scanned page compresses dramatically better than a photograph, which has high per-pixel entropy. For archival storage of BMPs you cannot convert, ZIP or RAR is the default answer.

    RLE Encoding: Only for Indexed 4- and 8-Bit BMPs

    Run-length encoding replaces sequences of identical pixel values with a count and a value. It works well on flat regions and poorly on noise. In practice, RLE is a legacy capability rather than a routine choice, and most modern encoders do not offer it as an output option at all.

    Lower Bit Depth, Crop, or Downsample

    If the BMP only exists to feed a display or a print at a known size, reducing bit depth or DPI is legitimate. Check whether the image is truly 24-bit color or merely a 24-bit container holding a handful of colors — the difference determines whether an 8-bit palette is lossless in practice. Crop first: removing empty margins costs nothing and reduces the pixel count before any other step.

    PNG vs JPG vs WebP vs PDF: Which Format Shrinks a BMP the Most?

    The best target format depends on what the image contains and where it is going, not on which format has the best reputation.

    Decision Table: Pick the Format by Image Type

    Image type Best target Why
    Screenshot (UI, dialog, terminal) PNG Lossless, keeps text and 1-pixel borders sharp
    Scanned document page PNG, or PDF for archiving Legible text, no artifact buildup
    Line art, logo, icon PNG or lossless WebP Flat colors compress extremely well
    CAD or GIS export PNG Preserves thin lines without ringing
    Photograph JPG or lossy WebP Lossy compression is efficient on continuous tone
    Web page asset WebP (AVIF as a next-gen option) Smaller transfer size, broad browser support

    PNG is the default lossless target and the one with the clearest published numbers: 60–80% smaller than the source BMP with no quality difference, per CoolUtils. WebP usually beats PNG at the same visual quality for web delivery, and AVIF can go smaller still, though support is less universal.

    Tie the choice to the delivery target. For web pages, smaller images support faster Largest Contentful Paint and less layout shift in Core Web Vitals. For email, the constraint is an attachment limit. For print archiving, it is fidelity.

    Why JPG Ruins Text and Line Art

    JPG compresses by discarding high-frequency detail, and text edges are almost pure high-frequency detail. The result is ringing — faint halos around letters — and blocking, where the image breaks into visible 8×8 tiles. On a photograph nobody notices. On a screenshot of a spreadsheet, it makes numbers hard to read.

    Sharp text vs JPG-artifacted text close-up

    WebP, AVIF, and PDF for Specific Delivery Targets

    WebP compresses further than PNG or JPG for the same visual quality at high resolutions, which is why it has become the default recommendation for modern websites. AVIF is a next-generation format offering strong compression with high quality; it is gaining adoption but is worth verifying on your target platform.

    PDF behaves differently from the image formats. It is a container, not a compression codec, and the converter applies Flate or JPEG compression inside the PDF — which CoolUtils says can shrink a file dramatically compared with the raw BMP. That makes PDF a strong choice when the destination is a document to be emailed, printed, or archived rather than an image to be edited. For a sense of magnitude, ResizerPicture demonstrates an 8 MB source photo becoming a 450 KB JPG and then a 220 KB WebP — vendor self-reported figures, useful as an order-of-magnitude reference rather than a promise.

    How to Compress a BMP Online in 3 Steps (No Install)

    Browser-based converters handle the format change without any software. The process is short enough that the harder decisions are the format and quality settings you pick, not the click sequence.

    Step-by-Step: From .bmp Upload to Smaller Download

    Step 1: Upload the .bmp. Drop the file into a browser-based BMP compressor. Some tools also accept a URL or a cloud storage import.

    Step 2: Choose the output format and quality. Pick PNG for screenshots and line art, JPG or WebP for photographs, or PDF if the goal is a shareable document. If the tool exposes a quality slider, start high and step down.

    Step 3: Download the result. Single files download directly. Tools that handle multiple files typically package everything into one ZIP.

    Three-step online BMP compression flow

    Check the free-tier limits before you upload a folder. Aspose’s BMP Resizer allows a maximum of 5 files and 5 MB total per operation on the free tier, while CoolUtils accepts BMP files up to 50 MB. The gap between those two numbers decides which tool is usable for a given job.

    The online-versus-desktop trade-off is straightforward: online means no install and immediate use, desktop means higher or unlimited size ceilings, batch power, and full control over encoder settings. For a one-off screenshot, online wins. For a folder of 300 scans, it does not.

    How to Tell Whether a Tool Uploads Your File

    Look for two specific signals. First, whether the tool states that processing happens locally in your browser. Second, whether it publishes a retention window. Aspose states that documents are stored in secure storage for 24 hours and then deleted; CoolUtils states that both the source and result are deleted automatically after conversion, and in any case within 24 hours.

    A tool that says nothing about either is not automatically unsafe, but you have no basis for trusting it with confidential material. For CAD exports, medical scans, or anything under an NDA, use an offline desktop tool or a local script instead.

    One more check worth running: verify the tool actually re-encodes rather than merely resizing dimensions. A resizer can shrink the byte count by discarding pixels, which is a different operation with a different result.

    Batch-Compressing Dozens or Hundreds of BMP Files

    Single-file web converters do not scale. Uploading one file at a time is tolerable for three images and untenable for a folder of 200 scans or a nightly CAD export.

    Browser-based batch converters occupy a middle ground. BulkImagePro accepts up to 50 files per run, processes them locally in the browser, and packages the output as a single ZIP that downloads automatically. That ceiling is generous for a design team and irrelevant for a production archive.

    Choose by volume: under 20 files, use an online bulk image converter; 20–500 files, use a desktop batch tool; recurring or scheduled jobs, use a script or a watch folder.

    Desktop Batch Converters and ZIP Output

    Desktop tools remove the file-count ceiling and typically preserve folder structure, which matters when you are converting a directory tree rather than a flat list. reaConverter converts hundreds of BMP images at once, works entirely offline so nothing is uploaded, integrates with the Windows right-click menu, and supports Watch Folders for automated runs. Because there is no upload, the privacy question disappears entirely.

    Scripted Pipelines and Watch-Folder Automation

    For repeatable, version-controlled pipelines, command-line conversion is the most reliable option. reaConverter exposes all of its features from the Windows command line, and CoolUtils documents a command-line form for batch BMP-to-PDF work, with a /ProcessRecursively switch to include subfolders. Wrap the command in a batch file and schedule it.

    Watch Folder mode is the natural end state for recurring jobs: set the rules once, and every new BMP that lands in a directory is converted and filed automatically. That removes the manual step from the workflow entirely.

    Compression vs. Resizing: Hitting a Target File Size Without Losing Quality

    The distinction matters more than it sounds, because many tools labeled “compress BMP” only resize. Aspose’s BMP Resizer is explicit that it resizes — increasing or decreasing image dimensions — and does not perform byte-level compression. If a tool only scales pixels, it will never shrink a BMP at fixed dimensions, regardless of its label.

    Compression changes bytes. Resizing changes pixels. When a portal demands a file under 500 KB, you can work backward: choose the format first, then adjust the quality setting or the color depth, and only resize if you still miss the target. Tools that accept an explicit target size do this search for you; a compress BMP to 100 KB tool fixes the ceiling and adjusts quality automatically, and News Appite’s 500 KB compressor lets you enter any target in KB and automatically finds the highest quality that fits, reducing dimensions only when necessary.

    Does Compressing a BMP Reduce Image Quality?

    It depends entirely on the target format, not on the act of compressing. PNG, lossless WebP, and ZIP archival produce output that is pixel-identical to the original BMP. JPG and lossy WebP discard detail, and the artifacts appear first around text and hard edges. Judge lossy output at 100% zoom over a region containing text, not from a thumbnail.

    Stripping EXIF Metadata: Smaller and Safer

    Image files routinely carry EXIF metadata such as GPS location, camera model, and timestamps — CoolUtils notes that BMP uploads can carry this information. Removing it is a modest size win and a meaningful privacy win, particularly for photos taken on phones and shared publicly. Several browser-based tool suites include a dedicated EXIF remover alongside their conversion utilities.

    Conclusion

    You cannot meaningfully compress BMP in place. The format stores raw pixels by design, so the real savings come from re-encoding to PNG, WebP, or JPG, with ZIP or RLE as the only options when the .bmp extension must stay. Pick the target format by image type — PNG for screenshots and line art, JPG for photos, WebP for web pages, PDF for documents you need to archive. Run one file through a converter, compare the before-and-after size and the visual result at full zoom, then scale up to a batch tool or a scripted pipeline for the rest of the folder.

    FAQ

    Can I compress a BMP file without changing it to another format?

    Yes, but only modestly — the BMP specification offers no efficient compression of its own. Your options are ZIP, RAR, or Deflate archiving, RLE encoding for 4- or 8-bit indexed images, or dropping from 24-bit to 8-bit color. Expect far smaller savings than converting to PNG or WebP.

    Does compressing a BMP reduce image quality?

    It depends on the target format, not on the act of compressing. PNG, lossless WebP, and ZIP are lossless — pixels remain identical to the original BMP. JPG and lossy WebP discard detail, and artifacts show up first around text and hard edges. Always check lossy output at 100% zoom.

    How much smaller is a PNG or WebP than the original BMP?

    PNG typically cuts BMP file size by 60–80% with no quality difference, according to CoolUtils. WebP generally goes smaller still than PNG for the same image and quality level, especially at high resolutions. Multi-megabyte BMPs from 300 DPI scans can drop by well over 80% when re-encoded.

    Why is my BMP file so large in the first place?

    BMP stores every pixel literally as width × height × bytes-per-pixel, with row padding, and applies no compression. File size therefore scales directly with resolution and bit depth. A single A4 page is roughly 6 MB at 150 DPI and about 25 MB at 300 DPI as an uncompressed BMP.

    Can I batch-compress hundreds of BMP files at once?

    Yes. Browser-based batch converters handle about 50 files per run and deliver a ZIP download. Desktop batch tools and command-line scripts scale to thousands of files. For recurring jobs, a Watch Folder or scheduled script converts new BMPs automatically as they arrive, with no manual step.

    Is it safe to compress BMP files with a free online tool?

    Check two things: whether the file is processed locally in the browser, and what the retention policy says. Reputable tools state either that files never leave your device or a clear auto-delete window such as 24 hours. For confidential scans, CAD exports, or anything under an NDA, use an offline desktop tool or a scripted local pipeline instead.

  • Lua Beautifier: Format Lua Code Free in Your Browser

    Lua Beautifier: Format Lua Code Free in Your Browser

    Header: Browser-based Lua beautifier turning messy code into clean, readable format

    A Lua beautifier — also called a Lua formatter or pretty-printer — rewrites Lua source into clean, consistent indentation and spacing without changing how the code runs. In 2026, most are free browser tools that format pasted Lua 5.5, LuaJIT, or Luau code locally, while editors can auto-format Lua on save.

    How to Beautify Lua Code in 3 Steps

    The browser workflow is short: paste, configure, take the result back.

    Step 1 — paste. Drop raw Lua into the online Lua beautifier. No account, no install, no download. The code stays in the tab you pasted it into.

    Step 2 — configure. Choose your indentation before you format: 2 spaces, 4 spaces, or tabs. Two spaces is the common default in Lua and Luau codebases, so stick with it unless a project’s existing style says otherwise.

    Step 3 — copy or download. Run the format, then copy the output straight back into your editor or download a .lua file. That’s it.

    Three-step browser workflow: paste, configure, copy or download

    Does the Lua beautifier upload my code?

    It depends on the tool, and the privacy-first pattern is worth looking for explicitly. Browser formatters that process locally state no upload and no account required, and they cap in-browser preview length rather than server-side file size — Phoenix Code’s HTML formatter (updated September 28, 2026) puts that ceiling at 2,000,000 characters and runs the formatting client-side, which is the same pattern a Lua tool can follow. Before you paste proprietary code, look for a local-processing statement instead of trusting a generic “secure” badge.

    What you get back: copy, download, or paste straight into your editor

    The output is plain text, so it goes into whatever you already have open. Copy it into the file you were editing, or download a .lua file and drop it beside the project. When the input is production code, diff the result against the source first and confirm that only whitespace moved.

    A full Lua parser fits in a web page because Lua itself is small. According to Lua.org, the Lua 5.5.1 tarball — source code plus documentation — is 390K compressed and 1.5M uncompressed, around 32,000 lines of C. That’s a reasonable payload for a client-side tool.

    What a Lua Beautifier Changes — and What It Leaves Alone

    A beautifier normalizes indentation, spacing around operators, blank lines, and line breaks. It does not rename, reorder, evaluate, or delete code.

    Clear split between whitespace changes and code behavior left untouched

    That behavior-preserving property is structural, not a promise: the token stream is untouched and only the whitespace between tokens moves. A file that formats cleanly should produce byte-identical output when it runs.

    It also won’t find syntax errors or logic bugs. That’s a validator’s or a linter’s job, and the strongest formatter-shaped tools draw that line explicitly. Phoenix Code states the distinction in one sentence — a formatter changes whitespace, a validator checks conformance, and a browser parser may infer missing elements and repair a document tree. The same split applies to Lua.

    Long bracket strings ([[ ... ]]) and long comments (--[[ ... ]]) have to be preserved byte-for-byte, for the same reason formatters protect raw-content regions in HTML: the text inside is literal, and re-indenting it changes rendered output.

    Is a Lua beautifier the same as a Lua formatter, minifier, or validator?

    A beautifier and a formatter are the same job under two names — rewriting whitespace for readability. “Beautifier” usually implies re-expanding something minified or unreadable, but the implementation is identical.

    A minifier does the opposite: it strips whitespace to shrink the file. A validator neither reflows nor shrinks; it reports whether code conforms to a syntax or rule set, and it leaves your layout alone.

    Beautifier vs. linter vs. AI code generator

    A linter reports suspicious or incorrect code without changing layout. An AI code generator is a different category again: it writes new Lua from a description rather than rearranging Lua you already have. Zenifiq’s Lua generator page makes the limitation plain — generated code still has to be verified, because the tool cannot test against your host and won’t keep pace with API changes.

    So the division of labor is: the beautifier reflows, the linter inspects, the generator authors.

    Which Lua Do You Have: Lua 5.5, LuaJIT, or Roblox Luau?

    Lua.org describes Lua as “a powerful, efficient, lightweight, embeddable scripting language” that supports procedural, object-oriented, functional, data-driven, and data-description styles. That breadth is exactly why one canonical layout can’t fit every Lua file — and why the answer to “which beautifier” depends on which grammar you pasted.

    Plain Lua 5.x — the current line is 5.5.x — is the baseline grammar most beautifiers target first. LuaJIT is the runtime behind Neovim’s init.lua and LÖVE2D, and its accepted syntax is a superset-with-caveats of standard Lua. Roblox Luau adds type annotations, continue, and changed standard-library behavior, so a formatter tuned only for plain Lua can mangle or reject Luau type syntax outright.

    Three Lua dialects: plain Lua 5.x, LuaJIT, and Roblox Luau

    Lua has existed since 1993 and was profiled at HOPL III in 2007, so no single frozen grammar covers every file a reader will paste into a box.

    What host is your Lua embedded in? Roblox, Neovim, LÖVE2D, Redis, or standalone

    Lua is almost always embedded, and the host API — not the syntax — decides what a script can do. Roblox runs Luau. Neovim uses Lua for configuration. LÖVE2D drives games with it. Redis exposes redis.call with KEYS and ARGV as the only way in. Formatting expectations differ per host: the type annotations a Roblox team expects carry no meaning inside a Redis script.

    Real embedded Lua can be long and unusual. On the darktable forum, a user wrapped image tagging in a Lua script that scores every photo against a fixed vocabulary of roughly 1,000 labels — the 365 scene categories of Places365 plus the 601 object classes of OpenImages V7 — then rewrote it to run purely in Lua against imported .dtmodels files with no Python involved. Scripts at that scale are exactly where formatting stops being cosmetic.

    Roblox Luau: type annotations a plain Lua beautifier may not expect

    Luau is not Lua with a different name. It adds a type system and its own features, and some standard Lua behavior is absent. A formatter built for plain Lua may treat local x: number = 1 as a syntax error, or strip the annotation because it doesn’t recognize the construct.

    Check the tool’s stated dialect coverage before pasting Luau, and treat “supports Lua” as an unverified claim until you’ve tested a typed snippet. A dedicated Luau formatter handles the typed grammar natively, and a one-line annotation test tells you more than a feature list does.

    Who maintains Lua — and why the MIT license matters for browser tools

    Lua is designed, implemented, and maintained by a team at PUC-Rio, the Pontifical Catholic University of Rio de Janeiro in Brazil, and is now housed at LabLua within the university’s Department of Computer Science. It’s free open-source software under the MIT license and may be used for any purpose, including commercial purposes, at no cost.

    That licensing is what makes a client-side beautifier straightforward: a browser tool can ship a Lua parser without navigating a restrictive redistribution term.

    Lua Beautifier Settings That Actually Matter

    Most options are cosmetic. A few change how readable your code stays in version control.

    The clearest model for a Lua beautifier’s option set is a formatter UI that exposes indentation, wrapping, and preserve-newline controls directly rather than burying them in a config file.

    2 spaces, 4 spaces, or tabs: picking a Lua convention

    Two spaces is the common default in Lua and Luau codebases. Four spaces shows up in many C-adjacent and game-engine shops. Tabs render at whatever width a reader’s editor is set to, which makes diffs inconsistent across machines.

    Match the file you’re editing before you format a project file. Converting a whole file from 4 spaces to 2 is safe but produces a diff with no review value.

    Wrapping, alignment, and the preserve-newlines setting

    Set a max line width, or leave lines untouched. If you hand-grouped a table across multiple lines for a reason, enable the preserve-existing-newlines option — otherwise a formatter may collapse the grouping into one long line.

    Keep long bracket strings and long comments verbatim; reflowing inside [[ ]] can change rendered output. Trailing whitespace removal and a single final newline are cosmetic, safe, and worth turning on. When the input is production code, look at the preview or diff before you copy.

    Format Lua on Save: VS Code, Neovim, and CLI Without a Web Tool

    A browser tool handles a one-off paste. Once a project has a style worth keeping, wire formatting into the editor so it happens without a decision.

    VS Code: Lua language server plus format on save

    Install a Lua language server, enable format-on-save, and let the server handle indentation on every write. The formatter that runs is the same kind of formatter a browser tool ships — the difference is that it fires automatically instead of on paste.

    Neovim: vim.lsp.buf.format on BufWritePre (and the version trap)

    In Neovim, formatting is wired to BufWritePre, so every :w reformats the buffer:

    vim.api.nvim_create_autocmd('BufWritePre', {
      group = vim.api.nvim_create_augroup('my.format', {}),
      callback = function(ev)
        if #vim.lsp.get_clients({ bufnr = ev.buf, method = 'textDocument/formatting' }) > 0 then
          vim.lsp.buf.format({ bufnr = ev.buf, timeout_ms = 2000 })
        end
      end,
    })
    

    Check versions before writing that config. As of October 2026, per Terminal Skills’ Neovim skill (updated October 1, 2026), vim.pack requires Neovim 0.12, vim.lsp.config and vim.lsp.enable require 0.11, and nvim-lspconfig requires 0.11.3 or newer. The stable line referenced is 0.12.5.

    Migrating off the deprecated require('lspconfig').<server>.setup{} framework means replacing each call with vim.lsp.config (settings) plus vim.lsp.enable (activation), and moving on_attach logic into an LspAttach autocommand. Verify it headlessly:

    nvim --headless -c 'if v:errmsg != "" | cquit 1 | endif' -c qa
    

    Then confirm :checkhealth vim.lsp lists your servers under Enabled Configurations. Follow that documented migration path and the deprecation warning goes away, with the servers appearing there.

    CLI formatters for CI and pre-commit hooks

    For CI and pre-commit hooks, run a standalone Lua formatter — StyLua or LuaFormatter — against a file or a directory, so formatting is enforced before review. The same guidance applies: for editor-agnostic tasks like formatting in CI, call the formatter or linter directly instead of routing through an editor.

    Which route to pick: paste into a browser tool for a snippet you can’t install anything for, and move to format-on-save once a project has a style to keep.

    From one-off browser paste to editor format-on-save to CLI enforcement in CI

    Is Beautifying Lua Safe? nil Gaps, 1-Based Indexing, and Behavior

    Beautifying is safe when it’s purely whitespace-level, and the failure modes worth knowing about are the ones formatting never touches.

    Does beautifying Lua code change how it runs?

    No. Whitespace between tokens is not significant in Lua, so indentation and spacing changes are behavior-preserving by construction. Long strings and long comments must survive verbatim, or embedded text inside them would change — the same guarantee a formatter gives when it protects raw-content regions during transformation.

    Safe doesn’t mean correct, though. A beautifier never fixes nil gaps, indexing errors, or host API misuse.
    What no formatter can fix: nil gaps, 1-based indexing, host API misuse

    Three traps catch newcomers and generated code alike. A table’s length is undefined once the table contains nil gaps. Array indexing starts at 1, not 0. And the host API dictates what any script is allowed to do. Zenifiq’s Lua generator documentation names all three and points at the pattern where they meet: generated Lua that removes items from an array mid-loop.

    A formatter will happily preserve a nil gap inside a table, and #t will still return an unexpected length afterward. Indentation is not a correctness check.

    Formatting also can’t fix architectural problems inside embedded scripts. On the darktable forum, the script’s author warns that tagging hundreds of images at once can freeze the application’s UI — “it is in the end a Lua script” — and another user reports Argus taking about two minutes to prepare its model and Artemis about eight on Windows 11. No beautifier changes that.

    The practical verification is to re-run your tests after formatting, or diff the token stream rather than the text.

    Conclusion

    A Lua beautifier only rewrites whitespace — which is exactly why it’s safe, and exactly why it can’t fix the dialect, version, or semantic problems hiding in your Lua. It solves readability; it does not solve correctness.

    Paste one snippet into a browser Lua beautifier now and confirm which dialect you’re looking at — plain Lua 5.x, LuaJIT, or Roblox Luau. Then, once the style is settled, wire format-on-save into your editor so formatting stops being a manual step and becomes something that happens when the file is saved.

    FAQ

    Is a Lua beautifier the same thing as a Lua formatter or a Lua linter?

    A beautifier and a formatter are the same job under two names: rewriting whitespace for readability. A linter is different — it reports suspicious or incorrect code without changing layout. Most tools keep the two separate, and some offer beautify, minify, and validate as distinct actions.

    Does beautifying Lua code change how it runs?

    No. Whitespace between tokens is not significant in Lua, so indentation and spacing changes are behavior-preserving. Long strings and long comments must be preserved verbatim, or embedded text inside them would change. Safe doesn’t mean correct: a beautifier never fixes nil gaps, indexing errors, or host API misuse.
    Does an online Lua beautifier support Lua 5.4, Lua 5.5, LuaJIT, and Roblox Luau?

    Support varies by tool. Plain Lua 5.x is the usual baseline, and the current line is Lua 5.5.x. LuaJIT (Neovim, LÖVE2D) and Roblox Luau are separate grammars; Luau adds type annotations and changed standard-library behavior. Check the tool’s stated dialect coverage before pasting Luau, and treat “supports Lua” as an unverified claim until you test a typed snippet.

    Is my Lua code uploaded to a server when I use an online beautifier?

    It depends on the tool. The privacy-first pattern is client-side processing entirely inside the browser tab. Browser formatters that advertise local processing state no upload and no account required, and cap in-browser preview length instead of server-side size. For proprietary or NDA-covered scripts, use a local editor or CLI formatter rather than trusting a claim you can’t verify.
    Can I auto-format Lua on save in Neovim or VS Code without a web tool?

    Yes — wire the LSP formatter to a write event: BufWritePre plus vim.lsp.buf.format in Neovim, format-on-save in VS Code. Check versions first: Neovim 0.12 for vim.pack, 0.11 for vim.lsp.config/enable, and 0.11.3+ for nvim-lspconfig as of October 2026. Verify the config headlessly and with :checkhealth vim.lsp so a broken formatter never silently skips a file.

  • Bar to PSI: Quick Conversion Formula, Chart & Examples

    Bar to PSI: Quick Conversion Formula, Chart & Examples

    Pressure gauge showing both bar and psi units to illustrate the conversion theme

    To convert bar to psi, multiply by 14.5038. That means 1 bar = 14.5038 psi, or about 14.5 psi for quick math. To go the other way, multiply psi by 0.0689476. One atmosphere is close but not identical: 1 atm = 1.01325 bar = 14.696 psi. For example, 2.5 bar is roughly 36.3 psi, and 10 bar is about 145 psi.

    How to Convert Bar to PSI: Step-by-Step Formula Using 14.5038

    The whole conversion comes down to one multiplier: psi = bar × 14.5038. As Tradukka shows, 1 bar equals 14.5038 psi. To reverse the calculation, multiply psi by 0.0689476, which is the same relationship turned around. You really only need to remember one direction.

    Follow these steps to convert any bar reading to psi:

    1. Identify the bar value. Look at the tire label, compressor manual, gauge, or product spec to find the pressure in bar.
    2. Choose your precision level. Use 14.5038 for exact engineering work or spreadsheets. Use 14.5 for quick field estimates.
    3. Multiply. bar × 14.5038 = psi for exact conversion, or bar × 14.5 for a fast approximation.
    4. Round only at the end. Keep full decimals during the calculation, then round the final psi value to a practical precision such as one decimal place.

    Simplified four-step flowchart for converting bar to psi

    Here’s a worked example. Convert 2.5 bar: 2.5 × 14.5038 = 36.2595 psi, which most people round to 36.3 psi. You can do the same in a calculator by typing 2.5 * 14.5038, or in a spreadsheet with =A2*14.5038 if cell A2 holds the bar value.

    The bar to psi formula

    The exact formula is psi = bar × 14.5038. That factor stays the same no matter what you’re measuring. For instance, 3 bar × 14.5038 = 43.5114 psi, and 5 bar × 14.5038 = 72.519 psi.

    Reverse conversion: PSI to bar formula

    To convert psi back to bar, use bar = psi × 0.0689476. For example, 30 psi × 0.0689476 = 2.068 bar. That’s the same as dividing by 14.5038, so 145 psi ÷ 14.5038 ≈ 10 bar.

    Mental math shortcut for bar to psi

    A quick mental shortcut: multiply bar by 14.5, then add a small correction of about 0.026% if you need more precision. For example, 10 bar × 14.5 = 145 psi, and the correction takes it to 145.038 psi. For everyday tire checks, 14.5 is usually close enough.

    Bar to PSI Conversion Chart: Common Values (1–100 Bar)

    The table below uses the standard 14.5038 factor, matching the conversion data published by Tradukka and Besto Calculator.

    Bar PSI (bar × 14.5038)
    1 14.5038
    2 29.0076
    3 43.5114
    5 72.519
    10 145.038
    50 725.19
    100 1,450.38

    These values cover common ranges, from low-pressure water systems up to industrial hydraulics. As a quick reference, 1 bar is close to 14.5 psi, 10 bar is close to 145 psi, and 100 bar is close to 1,450 psi.

    When should you use the exact 14.5038 instead of the rounded 14.5? Stick with 14.5 for tire inflation, home appliances, or rough comparisons where a fraction of a psi won’t affect safety or performance. Use 14.5038 for engineering calculations, calibration, certification, or anything where small pressure differences matter.

    PSI to bar quick reference table

    PSI Bar (psi × 0.0689476)
    10 0.689
    30 2.07
    50 3.45
    100 6.895
    145 10.0

    This reverse table comes in handy when a US tire gauge shows psi but the vehicle manual lists bar. For example, a common passenger tire at 30–35 psi is about 2.1–2.4 bar, which lines up with the range you see above.

    What Are Bar and PSI? Unit Definitions and the Pascal Bridge

    The bar is a metric pressure unit equal to exactly 100,000 pascals. It’s widely used in Europe and in industrial and scientific work. Besto Calculator points out that the bar isn’t an official SI unit, but it’s accepted in practice because it gives convenient numbers for tire pressure, hydraulic systems, air compressors, and gas systems. One bar is roughly equal to average atmospheric pressure at sea level, which is why it feels intuitive in many situations.

    PSI, or pounds per square inch, is the imperial/US unit of pressure. It measures force per unit area: PSI = Force (pounds) ÷ Area (square inches). Besto Calculator notes that psi is the standard for vehicles, tires, and mechanical systems in the United States. A typical passenger vehicle tire may need around 30–35 psi.

    The pascal (Pa) is the SI base unit for pressure, equal to one newton per square meter. It connects bar and psi because both can be expressed in pascals. According to Best Tool Online, 1 psi equals 6,894.757 pascals, or 6.895 kPa. Since 1 bar equals 100,000 Pa, the bridge is complete: 100,000 Pa is one bar, and 6,894.757 Pa is one psi.

    Diagram showing the conversion relationship between bar, psi, and pascal

    Gauge Pressure vs Absolute Pressure: Why It Matters for Bar to PSI Conversions

    Most everyday pressure readings are gauge pressure, written as psig or bar gauge. Gauge pressure measures pressure relative to the surrounding atmosphere, not from a perfect vacuum. Absolute pressure, written as psia or bar absolute, includes atmospheric pressure in the total.

    Tires, air compressors, and pressure cookers normally display gauge pressure. So a tire reading of 32 psi gauge isn’t 32 psi absolute; absolute pressure would be about 46.7 psi at sea level because standard atmospheric pressure is about 14.7 psi. The same logic applies to bar: a reading of 2.1 bar gauge is about 3.1 bar absolute at sea level.

    This distinction only changes your conversion when you’re comparing gauge and absolute readings. If you convert 2.1 bar gauge to psi using 14.5038, you get 30.5 psi gauge. But if you mistakenly compare that to an absolute psi specification, the numbers won’t line up because absolute includes the atmosphere.

    Pressure cooking gives a clear example. According to Wikipedia’s pressure cooker reference, a gauge pressure of 1.0 bar (15 psi) produces a cooking temperature of about 121 °C (250 °F). That 1.0 bar is gauge pressure, not absolute pressure; the absolute pressure inside the cooker is about 2 bar because standard atmospheric pressure is already about 1 bar.

    Diagram comparing gauge pressure and absolute pressure reference points

    Psig vs psia: Which one does your device show?

    Check the label or manual for abbreviations. psig and bar gauge mean gauge pressure; psia and bar absolute mean absolute pressure. Tire gauges, compressor regulators, and pressure cookers almost always use gauge units. Scientific instruments, weather reports, and some industrial sensors may report absolute pressure. If the unit isn’t labeled, see whether the reading returns to zero when open to air: gauge pressure reads zero, while absolute pressure reads about 14.7 psi or 1.013 bar at sea level.

    Real-World Bar to PSI Conversions by Use Case

    Different applications use different reference points, but the same 14.5038 multiplier applies once you know whether the reading is gauge or absolute.

    Use case Bar PSI Notes
    Passenger car tire 2.1–2.4 bar 30–35 psi Gauge pressure
    Espresso machine 9 bar 130.5 psi Brew pressure, usually gauge
    Watch water resistance 10 bar 145 psi Equivalent to 100 m depth rating
    Pressure cooker 1.0 bar gauge 15 psi About 121 °C cooking temperature
    Air compressor varies varies US models usually in psi; European models often in bar

    Automotive and bike tire pressure

    According to Besto Calculator, a typical passenger vehicle tire needs around 30–35 psi, which is about 2.1–2.4 bar. Many European vehicles show tire pressure recommendations in bar, while American vehicles often use psi. For example, a 2.2 bar tire spec equals 2.2 × 14.5038 = 31.91 psi, close to 32 psi. Always check the vehicle’s door sticker or owner’s manual—not the tire sidewall—for the correct pressure.

    Espresso, water resistance, and home appliances

    Espresso machines commonly brew at 9 bar. Multiply by 14.5038 and you get 9 × 14.5038 = 130.53 psi, usually cited as about 130.5 psi. That’s one of the higher everyday pressures, though still below many hydraulic systems.

    For watch water resistance, the Hamilton Khaki Field Murph 38mm specification lists a water resistance of 10 bar (100 m) / 145 psi (328 ft). That 145 psi figure is the direct conversion of 10 bar using 14.5038, which confirms that watch ratings expressed in bar can be read as a pressure equivalent in psi.

    Pressure cookers work at lower gauge pressures. According to Wikipedia, a gauge pressure of 1.0 bar (15 psi) corresponds to a cooking temperature of about 121 °C (250 °F). Home espresso machines and pressure cookers both show why gauge pressure matters: the pressure value you see is above ambient pressure, not the total absolute pressure.

    Air compressors show a regional split. Besto Calculator notes that European equipment often uses bar, while US models typically display psi. Before setting a compressor, check which unit the regulator shows and convert as needed to avoid over-pressurization.

    Pressure scale showing common real-world application values

    Bar vs atm vs kPa: Complete Pressure Unit Conversion Matrix

    Pressure units overlap, and the standard atmosphere is a common source of confusion. According to Wikipedia’s atmospheric pressure reference, the standard atmosphere (atm) is defined as 101.325 kPa, which equals 1,013.25 hPa, 14.696 psi, and 1.01325 bar. The same values appear in the pressure unit guide from Best Tool Online.

    The table below covers the most common pressure units.

    Unit Equivalent
    1 bar 100,000 Pa = 100 kPa = 14.5038 psi = 0.986923 atm
    1 psi 6,894.757 Pa = 6.895 kPa = 0.0689476 bar = 0.068046 atm
    1 atm 101.325 kPa = 1.01325 bar = 14.696 psi
    1 kPa 0.01 bar = 0.145038 psi = 0.00986923 atm
    1 MPa 10 bar = 145.038 psi = 9.86923 atm

    For automotive work, psi and bar are the most practical units. For scientific and meteorological use, kPa and hPa often appear. MPa is common in high-pressure engineering and material specifications because 1 MPa equals exactly 10 bar.

    Why bar and atm are not exactly the same

    The bar was defined as a convenient multiple of the pascal, while the standard atmosphere is defined from the average sea-level pressure on Earth. According to Best Tool Online, 1 atm equals 1.01325 bar, so the difference is about 1.3%. In psi terms, that’s 14.5038 psi for 1 bar versus 14.696 psi for 1 atm. For most practical conversions, this difference is small, but it matters in calibration, weather data, and scientific work where a 1.3% gap can affect results.

    Conclusion

    Converting bar to psi comes down to one multiplier: 14.5038. But using the right pressure type and real-world context matters more than the math itself. Gauge pressure and absolute pressure describe different things, and mixing them up can lead to incorrect settings. Save the formula, keep the conversion chart nearby, and always confirm whether your device reads gauge or absolute pressure before applying a conversion. With that check in place, bar to psi conversion becomes a fast, reliable step rather than a source of error.

    FAQ

    Is 1 bar the same as 1 atmosphere (atm)?

    No. One atm equals 1.01325 bar and 14.696 psi, while 1 bar equals 14.5038 psi. The difference is about 1.3%, small for everyday use but relevant in scientific or calibration work.

    What is 2.5 bar in psi?

    Multiply 2.5 by 14.5038 to get 36.2595 psi. For practical use like tire inflation or equipment settings, that’s typically rounded to 36.3 psi.

    How do I convert psi back to bar?

    Divide the psi value by 14.5038, or multiply by 0.0689476. For example, 30 psi × 0.0689476 = 2.068 bar, which matches a common passenger car tire pressure range.

    What does 10 bar water resistance mean in psi?

    Ten bar equals about 145 psi and corresponds to a water resistance rating of approximately 100 meters. This rating appears in watch and diving equipment specifications, such as the Hamilton Khaki Field Murph 38mm.

    Does car tire pressure use bar or psi?

    US vehicles typically display tire pressure in psi, while European vehicles often use bar. A common passenger tire range is 30–35 psi, or about 2.1–2.4 bar. Always check the vehicle’s door sticker for the recommended value.

  • UPC vs EAN-13: Which Barcode Do US Sellers Actually Need?

    UPC vs EAN-13: Which Barcode Do US Sellers Actually Need?

    Header: one GS1 number printed in two regional lengths

    UPC vs EAN-13 really comes down to one digit. UPC-A is the 12-digit retail barcode for the US and Canada; EAN-13 is the 13-digit code used almost everywhere else. Both encode GS1 GTINs from the same system — a UPC-A is an EAN-13 with a leading zero. For US retail, license a GTIN from GS1 US and print UPC-A. Sunrise 2027 does not ban it.

    UPC vs EAN-13: The 3 Differences That Actually Matter

    For a US seller, this is a short answer. If your product gets scanned at a US or Canadian checkout, you print a UPC-A. UPC-A carries 12 digits and serves the US and Canada. EAN-13 carries 13 digits and serves almost everywhere else, as BoxHero describes the split.

    Neither format is technically better than the other. Both are GTINs drawn from the same global numbering system administered by GS1 — two regional lengths of one identifier family, not competing standards. That single fact removes most of the anxiety around this decision.

    It also helps to separate the number from the picture of the number. The bars are only a carrier. The licensed number is the product’s identity, and the symbol is simply how a scanner reads it. Vxceed puts it plainly: the GTIN, UPC, and EAN are the same idea at different lengths, all licensed from one standards body, while the barcode isn’t a number at all — it’s a picture of one.

    Why there are 12-digit and 13-digit versions of the same number

    The US grocery industry built the 12-digit UPC first, and the rest of the world standardized on a 13-digit version shortly after. Retail Scan & Stock describes the UPC-A as introduced in North American supermarkets in 1974, with the European Article Number developed shortly after to include a country code prefix. Because the 13-digit form needed room for that prefix, US numbers effectively became the same numbers with a zero in front.

    UPC vs EAN-13 at a glance (comparison table)

    Attribute UPC-A EAN-13
    Digit count 12 13
    GTIN equivalent GTIN-12 GTIN-13
    Primary region US and Canada Everywhere else
    Issuing body GS1 / GS1 US GS1 / GS1 US (regional member organizations)
    Scans at US checkout Yes Yes
    Typical package level Retail unit Retail unit

    Barcode vs GTIN vs SKU: three different things

    A GTIN is the global identity of a product configuration. A barcode is the machine-readable symbol that carries it. A SKU is a private, merchant-defined code that sits alongside the GTIN inside your own systems — it never replaces it. SKUs are internal and unregulated; GTINs are globally unique and licensed.

    Three-part concept diagram: GTIN, barcode, and SKU as different roles

    Which Barcode Should You Print? A Decision Tree for US Sellers

    Here’s the one-line rule: if you’re selling physical consumer goods in the US, print UPC-A from a GS1 US-licensed GTIN. Most readers won’t need an exception to that.

    The table below maps five real situations to a format.

    Your situation What to print Why
    US marketplace only (Amazon, Walmart Marketplace) UPC-A from a GS1 US GTIN The marketplace validates the number against the GS1 registry
    US retail shelf or big-box UPC-A from a GS1 US GTIN Retailers require a licensed GTIN and a unit-level symbol
    US seller exporting abroad The same GTIN, printed as EAN-13 The number does not change — only the printed length does
    Book or audiobook EAN-13 Bookland barcode from an ISBN Books use the ISBN, not a GS1 GTIN
    Internal inventory only Code 128 or your own store codes No GS1 license needed, because the code never leaves your building

    A single GS1 GTIN covers both markets. The same number prints as UPC-A domestically and as an EAN-13 with a leading zero abroad, so nobody needs to buy two numbers for one product.

    Internal-only labels never need a GS1 license, because they never leave your four walls. BoxHero states the rule directly: a GS1 barcode is required only when the product is sold through a retailer or marketplace that scans it at checkout or verifies it in a catalog.

    Three questions settle almost every case: where the item will be scanned, who verifies the number, and whether the code must resolve in a global registry.

    Simple decision flow for US sellers: US retail, export, or internal only

    US retail shelf vs US marketplace: same barcode, different validation

    The symbol is identical in both channels — a UPC-A at unit level. What differs is who checks it. A retail shelf buyer may accept your packaging spec after a vendor onboarding review, while a marketplace validates your GTIN programmatically against the GS1 database before your listing goes live.

    Selling internationally from the US: do you need an EAN-13 too?

    No. You need a 13-digit number the moment you print for a market that expects EAN-13, but you don’t need a second identifier. Add the leading zero to the same GTIN and render it as EAN-13. That’s a formatting step, not a licensing step.

    If your product is a book: ISBN / Bookland EAN instead of a UPC

    Books are the one common exception. According to ISBN Services, the 13-digit ISBN is converted into an EAN-13 barcode commonly printed on the back cover, often called the Bookland EAN barcode. The ISBN itself comes from the national agency — Bowker in the United States — so you don’t license a GS1 GTIN for the book edition. For the printing side, our guide to generating an ISBN barcode walks through the Bookland EAN requirements step by step. Non-book items bundled with a book, such as a tote, toy, or media accessory, still need their own GS1 GTIN.

    UPC vs EAN-13 Digit by Digit: Prefix, Item Reference and Check Digit

    Once you know what each position controls, you know which digits are yours and which ones you must not touch.

    What each digit position means in a UPC-A and an EAN-13

    Wikipedia’s UPC entry describes the UPC-A structure as SLLLLLLMRRRRRRE, where S, M, and E are guard patterns and the L and R sections carry the 12 digits. The first digit is a number system digit, and the last is an error-detecting check digit. In practice, the first section holds a GS1 company prefix assigned by the local GS1 organization, the middle holds the product reference, and the final digit validates the whole thing.

    EAN-13 follows the same logic with one extra position at the front. Vxceed summarizes every GTIN as three parts: a GS1 company prefix, an item reference assigned by the manufacturer, and a mathematical check digit at the end that verifies scanning integrity.

    Format Position 1 Company prefix Item reference Final digit
    UPC-A (12 digits) Number system digit Assigned by GS1 member organization Assigned by the brand Check digit
    EAN-13 (13 digits) Issuing-region prefix Assigned by GS1 member organization Assigned by the brand Check digit

    One caution about the EAN-13 prefix: it’s an issuing-region indicator, not a country of manufacture. It identifies which GS1 member organization issued the number. A product manufactured in China and sold by a US brand still carries a US prefix, because the US brand’s GS1 member organization issued that GTIN.

    How does the check digit work in a 12- vs 13-digit number?

    The check digit is the final modulo-10 computed digit used for error detection. For a UPC-A, you sum the digits in odd positions, multiply by 3, add the digits in even positions, take the remainder modulo 10, and subtract from 10. Wikipedia walks through the example 03600029145x, where the odd-position sum is 14, multiplied by 3 gives 42, plus the even-position digits gives 58, and 58 mod 10 = 8, so the check digit is 10 − 8 = 2.

    For an EAN-13, the developer walkthrough on DEV Community uses the same weighted logic with a different weight order: take the first 12 digits of 400638133393, multiply odd positions by 1 and even positions by 3, sum to 89, and reach the next multiple of ten — 90 — so the check digit is 1, giving the complete number 4006381333931.

    The error-detection math is worth knowing, because it explains why the check digit isn’t a formality. Wikipedia reports that UPC-A detects 100% of single-digit errors and roughly 89% of transposition errors — a transposition escapes detection only when the difference between two adjacent digits is 5, which works out to about 11.111% of transpositions being undetectable.

    GTIN-8, -12, -13 and -14: unit, inner pack, case and store-issued codes

    The GTIN family covers more than the two retail lengths. Retail Scan & Stock lays out the hierarchy: GTIN-8 for very small retail packages such as gum or cosmetics, GTIN-12 encoded in UPC-A for US and Canadian units, GTIN-13 encoded in EAN-13 globally, and GTIN-14 encoded in ITF-14 or GS1-128 symbols on outer shipping cartons and master cases.

    Two further categories sit outside that hierarchy. Variable-measure and restricted-circulation codes are store-assigned numbers for items weighed or priced at the point of sale — Wikipedia notes that number system 2 is reserved for local use for items sold by variable weight, where the store assigns an item number and the remaining digits carry weight or price. These aren’t GTINs at all, and they’re scoped to the store that issued them. Separately, JAN is Japan’s implementation of the EAN system — a regional name for the same 13-digit structure, not a different standard.

    Is a UPC-A Just an EAN-13 With a Leading Zero?

    Yes — mathematically. A 12-digit UPC-A is identical to the 13-digit EAN-13 formed by prefixing a zero. Retail Scan & Stock gives the worked example: UPC 012345678905 is represented in global 13-digit databases as 0012345678905. The same equivalence is corroborated by BoxHero and Vxceed, both of which describe the leading-zero relationship in the same terms.

    One GTIN shown as a 12-digit UPC-A and a 13-digit EAN-13 with leading zero

    The practical consequences are simple. You don’t buy a new number to sell the same item internationally, and you don’t need to convert anything on the package artwork beyond choosing which length to render.

    Conversion is a formatting operation, not an identity change. A genuinely new product, size, flavor, or multi-pack still needs its own GTIN — reusing one number across variants is a separate mistake that has nothing to do with the UPC-versus-EAN-13 question.

    Do US checkout scanners actually read EAN-13 barcodes?

    Yes. Modern US point-of-sale systems are built to read 13-digit EAN-13, since a US UPC-A is the leading-zero form of the same number. Retail Scan & Stock notes that since the 2005 GS1 Sunrise initiative, virtually all modern retail scanners and smartphone camera decoders read both UPC-A and EAN-13 formats. A US product should still print UPC-A, because that’s what US packaging standards, retailers, and marketplace listings expect.

    UPC-E and EAN-8: the compressed formats people confuse with UPC-A and EAN-13

    These are separate small-package symbologies, not shortened versions you generate by trimming digits. BoxHero describes UPC-E and EAN-8 as compressed forms for items like a stick of gum or a small cosmetic tube. If you’re weighing the small-package forms, this EAN-13 vs EAN-8 comparison covers the shorter format in detail. Wikipedia adds that UPC-E suppresses the number system digit, trailing zeros in the manufacturer code, and leading zeros in the product code, and can only correspond to UPC-A number systems 0 or 1.

    How to Get a UPC or EAN-13 in the US: GS1 Licensing and Costs

    GS1 US is the authoritative issuer in the United States. You license numbers — you don’t buy a barcode image from a generator.

    There are two routes. A single GS1 US GTIN covers one product. A GS1 Company Prefix covers a catalog, and the prefix is what lets you assign numbers yourself per item and per packaging level.

    On reported pricing, BoxHero states that a single GS1 US GTIN costs a one-time $30 with no annual renewal fee, and that a GS1 Company Prefix carries an initial fee based on how many numbers you need plus an annual renewal fee, with published first-year figures starting at a few hundred dollars. Retail Scan & Stock reports the same $30 individual GTIN figure and notes that other GS1 member organizations apply regional fee structures. Treat these as published figures to verify at source — check gs1us.org before you budget.

    Assign a distinct GTIN to every sellable variant and to each packaging level: each, inner pack, and case. Reusing one number across variants is the most common expensive mistake, because it corrupts stock records, orders, and sales history at the same time — and the damage tends to surface late.

    Single GTIN vs a GS1 Company Prefix: how to choose

    Choose a single GTIN if you’re listing a handful of products and don’t expect to change packaging levels soon. Choose a company prefix the moment you have a catalog, multiple sizes, or case-level labeling to manage, because the prefix is what lets you assign the next number yourself instead of starting a new purchase each time. BoxHero notes that once you license the number, the GS1 US Data Hub generates the barcode image as a PNG or EPS file at one fixed size.

    Are third-party reseller barcodes safe to use?

    Cheap reseller codes are real numbers, but they carry a hidden mismatch. According to BoxHero, these codes come from GS1 company prefixes bought before 2002 that remain legally transferable under a court settlement, and for some purposes they scan fine. The problem is ownership: a code registered to the reseller’s original company name can fail a marketplace check even though the bars scan correctly at a register.

    Free barcode generators and validators render symbols and check digits accurately — Yotpo’s generator, for example, handles the specific digit rules and check digit calculation for UPC-A and EAN-13 — but none of them grant you a licensed number. Marketplaces check the registry, not the image.

    US Barcode Launch Checklist: From GS1 License to Printed Symbol

    This sequence runs from licensing to a scanned proof. Each step names the failure point it prevents.

    1. License the GTIN from GS1 US. Failure point: buying a reseller code whose registry owner does not match your brand.
    2. Assign a number per variant and per packaging level. Failure point: two flavors or two sizes sharing one code, which corrupts stock records and listings.
    3. Create artwork with the correct symbology for the number. Failure point: applying an EAN-13 symbol to a 12-digit payload, or the reverse.
    4. Meet size and quiet-zone rules. Failure point: a barcode placed outside the quiet zone, which produces a symbol that will not scan.
    5. Scan-test a printed proof with a real scanner. Failure point: discovering a rendering problem after the full print run.
    6. Store the number as text. Failure point: database or spreadsheet handling that silently alters the identifier.
    7. Verify the number against marketplace metadata. Failure point: a catalog mismatch that reads as an invalid GTIN during listing review.
    8. Keep the human-readable digits complete. Failure point: truncated digits printed under the bars, which breaks manual key entry when a scanner fails.

    The print specifications your printer needs

    Treat these as the spec you hand your printer, not trivia. Wikipedia gives the nominal x-dimension for UPC-A as 0.33 mm (0.013 in) and the nominal symbol height as 25.9 mm (1.02 in), with guard pattern bars extended downward by five times the x-dimension. A complete UPC-A is 95 modules wide: 84 modules for the 12 digits plus 11 modules for the start, middle, and end guard patterns. A quiet zone at least 9 times the x-dimension wide must be present on each side. UPC-A can be reduced or magnified anywhere from 80% to 200%.

    For developers and ops: storing, normalising and validating barcode data

    Spreadsheet and database handling is where clean identifiers go wrong. Retail Scan & Stock identifies three specific failure modes: leading zeros dropped because a spreadsheet reads 012345678905 as the number 12345678905; long digit strings displayed in scientific notation; and a 15-digit numeric precision limit that converts digits past the 15th position to zeroes. Microsoft Support documentation confirms the 15-significant-digit limit, and the recommended fix is to format the column as Text before entering or importing identifiers.

    The DEV Community validator walkthrough makes the same point from the engineering side: keep barcode values as strings, never pass them through Number(), and validate the check digit before rendering anything. That author also draws a boundary worth keeping: a passing check digit means the number satisfies the mathematical rule — it does not mean the number was licensed correctly, that the product exists, or that a marketplace will accept it.

    Why Amazon, Walmart and Target Reject Some Seller Barcodes

    Marketplaces verify the GTIN against the GS1 registry and expect the brand and company on record to match the listing. A real but mismatched number fails that check and is treated as an invalid GTIN.

    The rejection mechanism is catalog mismatch — not a broken barcode, and not a UPC versus EAN-13 format problem. This distinction matters, because sellers often respond to a rejection by reprinting the symbol, which fixes nothing.

    How marketplace GTIN validation actually works

    BoxHero describes the process: Amazon checks the barcode you enter against the GS1 database and expects the brand and company on record to match your listing, and Amazon’s barcode policy states that it verifies UPCs through the GS1 database and treats codes that do not match GS1’s information as invalid. A reseller code registered to the reseller’s original company name can fail that check, so even when the code scans, a listing may be rejected for an invalid GTIN. The practical safeguard is to license codes directly from GS1 US for anything going to Amazon, Walmart, or Target, and to keep the GS1 certificate on hand — these marketplaces can ask you to prove the code is registered to your company.

    ASIN is not a GTIN (and a case code is not a unit code)

    Two further mismatches cause avoidable rejections. An ASIN is Amazon’s own catalog identifier and does not replace a GTIN anywhere else, as Vxceed notes in its list of external identifiers a SKU maps to online. And a GTIN-14 case code will not scan as a retail unit — Retail Scan & Stock warns against scanning a master carton symbol as an individual piece count on the sales floor.

    Sunrise 2027 and 2D Barcodes: What Changes for Your UPC-A

    Sunrise 2027 is a GS1 target for retail point-of-sale systems to read 2D codes — QR, GS1 DataMatrix, GS1 Digital Link — alongside the 1D barcodes they read today. It is a target, not a government mandate.

    Sunrise 2027 in one paragraph: target, not mandate

    In BoxHero’s rendering, GS1 states that “by the end of 2027, retail point-of-sale systems should be able to read and process 2D barcodes in addition to the 1D barcodes they read today.” Three things keep this in proportion: the UPC is not being banned, there is no fine for skipping it, and the pressure comes from large retailers rather than regulators. A 1D barcode holds one piece of information — the GTIN — while a 2D code holds several thousand characters, including batch number, expiration date, serial number, and a web link tied to the product. Adoption is already underway: GS1 reports the transition is being tested in 48 countries representing 88% of the world’s GDP, per a 2024 GS1 statement cited by BoxHero.

    The practical action now is small. Keep printing the UPC-A, leave label real estate for a future 2D carrier, and make sure your GTIN data is clean enough to power one. GS1 suggests printing both the 1D and 2D barcode on the same package during the switch.

    1D barcode and 2D code coexisting on the same product label

    From the first 1974 scan to 2D in 2027

    The 1D retail barcode has been in continuous use since the first UPC scan. Wikipedia records that the first UPC-marked item scanned at retail checkout was a 10-pack of Wrigley’s Juicy Fruit chewing gum, purchased at the Marsh supermarket in Troy, Ohio, at 8:01 a.m. on 26 June 1974, ringing up 67 cents on an NCR cash register.

    That longevity was deliberate. Murray Eden, a consultant on the team that created the UPC barcode and chairman of a committee of scientists at MIT, helped, in his 1970s-era phrasing, “select a symbol that would endure the inevitable rush of technology that lay ahead.” He also chose the font and introduced the human-readable digits below the bars as a fail-safe in case a reader malfunctioned. GS1 now frames Sunrise 2027 as coexistence rather than replacement — which is exactly consistent with a symbol chosen for endurance more than fifty years ago. The history of QR codes tells the same story from the other direction: a 2D carrier invented for Toyota factory floors that now shares labels with the 1D symbol it was never meant to replace.

    Conclusion

    UPC vs EAN-13 is not a choice between competing standards — it is one GS1 number printed in two regional lengths, and US sellers print the 12-digit UPC-A. License a GTIN from GS1 US (verify current pricing at gs1us.org before budgeting), assign a separate number to every variant and packaging level, generate the symbol to spec, scan-test a physical proof, and store the number as text. Reserve label space for a 2D carrier, but do not reprint anything for Sunrise 2027 — it is a target, not a mandate.

    FAQ

    Can I convert a 12-digit UPC to an EAN-13, or do I need to buy a new number?

    No purchase is required. Add a leading zero to the 12 digits and the result is the valid EAN-13 for the same item — for example, 012345678905 becomes 0012345678905. The conversion changes formatting only, never identity. You still need a new GTIN for a genuinely new product, size, flavor, or multi-pack.

    Do US checkout scanners actually read EAN-13 barcodes?

    Yes. Modern US point-of-sale systems are built to read 13-digit EAN-13, since a US UPC-A is the leading-zero form of the same number — Retail Scan & Stock notes that virtually all modern retail scanners read both formats. A US product should still print UPC-A, because that is what US retailers and marketplace listings expect.

    Can I just make up my own barcode number for my product?

    No. The number must come from a GS1-issued prefix so it resolves uniquely in the global registry. A self-invented number may render and even scan locally, but marketplaces and retailers that validate against GS1 will reject it. Internal-only labels for your own warehouse can use your own codes, because they never need to resolve globally.

    Is a UPC the same thing as a GTIN?

    A GTIN is the umbrella identifier family, and UPC-A (GTIN-12) and EAN-13 (GTIN-13) are two of its lengths. GTIN-8 covers small packages and GTIN-14 covers cases and pallets, so “GTIN” is the safe general term. Most US retail listings that ask for a “UPC” will accept any valid GTIN.

    Why does my barcode turn into scientific notation in Excel?

    Spreadsheets treat long digit strings as numbers, strip the leading zero, and switch to scientific notation past 15 digits. Retail Scan & Stock notes that Excel numeric precision is limited to 15 significant digits, so digits past the 15th position can become zeroes. Store barcode values as text and validate the check digit before exporting to artwork — and always keep the leading zero on a 13- or 14-digit GTIN.

    Will my UPC stop working in 2027 because of Sunrise 2027?

    No. Sunrise 2027 is a GS1 target for retail POS to read 2D barcodes alongside 1D, not a ban or a deadline for brands. There is no fine for non-compliance and UPC-A and EAN-13 remain scannable. The practical move is to keep printing your UPC and reserve label space for a future 2D carrier.

    Do books need a UPC, or is the ISBN barcode enough?

    Books carry a 13-digit ISBN encoded as an EAN-13 Bookland barcode, not a UPC-A, according to ISBN Services. ISBNs come from Bowker in the US, so you do not license a GS1 GTIN for the book itself. Non-book items bundled with a book — a tote, a toy, a media accessory — still need their own GS1 GTIN.

    Do I need a separate UPC for each size, color, or multi-pack?

    Yes. Every sellable variation that a retailer scans or stocks separately needs its own distinct GTIN. Different packaging levels also differ: each unit, inner pack, and case carry their own GTIN, with GTIN-14 and ITF-14 on cases. Reusing one number across variants is a leading cause of listing rejections and inventory errors.

  • How to Compress a MOV File Without Losing Quality

    How to Compress a MOV File Without Losing Quality

    Large MOV compressed to a smaller MP4 while keeping quality

    The fastest way to compress a MOV file without losing quality is to re-encode it with a modern codec: convert ProRes or high-bitrate MOV to H.264 for compatibility, or H.265 for smaller files, lower the bitrate, and export as MP4. Expect 50–90% reductions with little visible quality loss — but verify a 15-second sample first.

    Why Your MOV File Is So Big: It’s a Container, Not a Codec

    MOV is a container format, not a video format. The same .mov extension can hold H.264, H.265, Apple ProRes, DNxHD, Motion JPEG, or uncompressed audio, and the file size depends entirely on what’s inside. Two files with the same duration and the same filename can differ by a factor of twenty.

    MOV container holding different codecs like H.264, H.265, ProRes

    ProRes is the single most common reason a MOV is huge. ProRes looks excellent and edits smoothly, but it eats storage fast: a short 4K ProRes clip can hit several gigabytes within minutes, while the same footage encoded as H.264 takes up a fraction of that space. Screen recordings balloon the same way when the capture tool defaults to a high bitrate. That’s why a two-minute clip can take longer to upload than it took to record.

    File size ≈ bitrate × duration, which makes bitrate the biggest single lever you control. According to WowTechHub, re-encoding high-bitrate or ProRes MOV to H.264 or H.265 typically cuts size by 50% to 90% — a 4 GB 1080p MOV recorded at 60 Mbps becomes roughly a 600 MB file at 10 Mbps, with very little visible loss. The same lever drives compressing any video without losing quality; MOV is just the container where it shows up most.

    Encoder choice compounds that gain. WonderFox illustrates it with a 100-minute 4K source: the same footage lands at roughly 30 GB in MPEG-4, about 10 GB in H.264, and around 5 GB in H.265 or VP9 — a 3x to 6x overall reduction. The point isn’t to make every file tiny. As Ava Taylor of WowTechHub puts it, “Compression is not about making every file tiny. It is about making the file small enough for its purpose while keeping viewers from noticing the tradeoff.”

    Check What’s Inside Your MOV in 30 Seconds

    Before you change a single setting, identify what the file actually contains. Open it in QuickTime Player and use the movie inspector to read the codec, resolution, and data rate. Or inspect the file with a utility such as MediaInfo or ffprobe and look at three numbers: video codec, bitrate, and resolution.

    Those three values decide everything downstream. A 50 Mbps H.264 source has enormous headroom; a 5 Mbps H.264 source has almost none. Note the audio codec at the same time — uncompressed audio inside a MOV is rare, but it inflates a file noticeably when present.

    The Formula That Predicts Your Result: Bitrate × Duration

    Size math is simple enough to do in your head. Multiply the bitrate by the duration, and you get the approximate file size — a 60 Mbps clip runs about 7.5 MB per second, or roughly 450 MB per minute, before audio.

    Use that to set expectations before encoding. If the input bitrate is 60 Mbps and your target is 8 Mbps, you’re asking for a 7.5x reduction, which a modern codec handles comfortably. If the input is already 6 Mbps, the same target demands visible sacrifices. Resolution and frame rate feed into this too: higher resolutions and frame rates like 60 fps, 90 fps, or 120 fps require proportionally more data to stay sharp. That’s why a 4K60 clip is so much heavier than a 1080p30 clip of the same length.

    How to Compress a MOV File: The 3-Step Method

    The practical workflow comes down to three decisions — codec, quality target, and output container — plus one optional set of geometry levers if you still need more space.

    Three-step workflow: choose codec, set CRF, export container

    Step 1: H.264 or H.265 — Which Codec Should Your MOV Become?

    H.264 (AVC) is the compatibility default: it plays almost everywhere, on nearly every device made in the past decade. H.265 (HEVC) delivers smaller files at the same visual quality, which matters most for 4K and long clips, but it encodes far more slowly and older hardware may fail to play it.

    Choose H.264 when the file’s destination is unknown or broad. Choose H.265 when you control playback and size is the priority. Either way, remember that ProRes is a source codec, not a delivery codec — it belongs in your editing pipeline, not in an email.

    Step 2: CRF 22 as Your Default (and When to Go Lower)

    Use Constant Quality (CRF) rather than guessing a bitrate. According to Uploadex, CRF 22 is the everyday “looks the same to me” setting: high-bitrate sources can drop by roughly 80% with no visible loss, while H.265 pushes the savings further. HandBrake’s own scale treats 18 as visually lossless at a large file size, 20–22 as visually lossless to most viewers, 23 as showing slight loss on a side-by-side, and 24–28 as noticeably compressed.

    Recommended ranges: H.264 → CRF 18–23; H.265 → CRF 22–28. The first-pass sanity command in FFmpeg looks like this:

    ffmpeg -i input.mov -c:v libx264 -crf 22 -preset slow -c:a aac -b:a 128k output.mp4
    

    -preset slow trades encoding time for better compression efficiency. For H.265, swap in libx265 and CRF 24.

    Step 3: Export as MP4, or Keep the MOV Wrapper?

    Converting MOV to MP4 is the most common path because MP4 balances size, compatibility, and sharing. Keeping the MOV wrapper makes sense when the file is heading back into an editing pipeline that expects ProRes-class handling.

    Audio deserves its own decision. AAC at 128 kbps is enough for voice and screen recordings; 192–256 kbps is safer for music-heavy content. Over-compressing audio makes otherwise good video feel cheap. And since audio is a small share of total size, there’s little to gain from cutting it below 128 kbps.

    If the file is still too large after codec and CRF are set, then reach for geometry: downscale resolution, then reduce frame rate from 60 to 30 fps. Change codec and CRF first, geometry last.

    Source Type × Target Use: The MOV Compression Decision Table

    Most guides mix ProRes sources and already-compressed H.264 sources into the same advice, but their headroom is completely different — one can shrink by 80%, the other barely moves. This table separates them.

    High-bitrate source has large compression headroom; already-compressed source has little

    Source bitrate (MOV contents) After CRF 22 H.264 After CRF 22 H.265 Visible quality loss
    4K ProRes master → delivery copy ~80% smaller Smaller still None
    50 Mbps (raw camera H.264) ~6 Mbps ~4 Mbps None visible
    20 Mbps (high-quality export) ~4 Mbps ~3 Mbps None visible
    10 Mbps (typical online video) ~3 Mbps ~2 Mbps None visible
    5 Mbps (already compressed) ~3 Mbps ~2 Mbps Slight at busy scenes

    Source: Uploadex, which frames the rule plainly — you can drop a high-bitrate source by 80% without visible loss, but you cannot drop an already-compressed file by another 80%, because there is no quality left to throw away.

    Match the output to its destination rather than to a single universal setting. WowTechHub offers typical bands by use case:

    Use case Resolution Codec Typical bitrate
    Email preview 720p H.264 2–5 Mbps
    Website video 1080p H.264 or H.265 5–10 Mbps
    4K sharing copy 4K H.265 20–35 Mbps
    Archive master Original ProRes or high bitrate Keep original

    Resolution downscaling (4K to 1080p) is one of the few remaining levers once CRF is fixed, but only apply it when the destination platform never displays 4K. For screen recordings, confirm small text is still legible before committing.

    Keep the original as a master. The compressed file is a delivery copy, not a replacement. That single habit prevents the re-compression death spiral where a file is squeezed again and again until artifacts dominate.

    Reading the Table: Same MOV, Five Very Different Outcomes

    Batch results show how much this matters at scale. One marketing team holding 200 product clips went from 800 GB to about 120 GB by re-encoding delivery copies while masters stayed on a backup drive, according to WowTechHub. A creator’s review folder of ten 3 GB 4K MOV files dropped from 30 GB to roughly 5 GB — about 83% — the same way.

    Frame-rate reduction is an optional last row in this table: 60 → 30 fps where the platform does not need 60 fps.

    Screen-Recording MOV Files Compress Differently

    QuickTime and OBS screen recordings are among the most common .mov sources, and the generic “just drop the resolution” advice backfires on them. Static UI and slideshow-style frames compress extremely well, so raise CRF to 26–30 before touching resolution at all.

    Keep resolution when the recording contains small text, code, or UI labels. Downscaling destroys readability in a way that CRF never does — a slightly softer gradient is forgivable, an unreadable menu bar is not. Validate with a 15-second sample at full size before committing to a 40-minute render.

    Frame-rate reduction is usually safe here, since most recordings do not need 60 fps. A Microsoft Tech Community thread from September 2026 captures the classic version of this problem: a user named Rhysin had QuickTime screen recordings over 1 GB plus other movies stored on a Windows 10 PC, and needed both smaller files and something small enough to email.

    How to Compress a MOV File on Mac: QuickTime, iMovie, and Finder

    Mac users have three built-in options, and all three are convenient but limited in the same way: they give you presets, not parameters.

    QuickTime’s Export As Options (and Their Limits)

    QuickTime Player is both the main source of .mov files and a limited export tool. File → Export As offers 1080p, 720p, and 480p options plus a “Smaller File Size (HEVC)” choice, but it gives no CRF control and no reliable size estimate before you commit. QuickTime’s Share → Email path does show an estimated output size along with frame rate and codec details, which makes it useful for rough email targets, though still not precise.

    When you need CRF 22, a specific megabyte count, or batch processing, QuickTime is the wrong tool.

    iMovie Share → File / Email: Resolution Presets Explained

    iMovie is free and built in, and exports smaller files through Share → File or Share → Email with resolution and quality presets. The File route displays an estimated output size in the corner of the export dialog, which is enough for a rough cut. It is not built for precise size targets, and it offers no codec choice beyond what the presets imply.

    Finder’s Encode Selected Video File Only Works on MOV

    Finder’s right-click “Encode Selected Video File” is MOV-only and preset-limited — it will not help with MP4 or MKV files, so do not expect it to be a general-purpose compressor. Within that boundary it is fast and simple, letting you pick a resolution, convert to Apple ProRes, or extract audio only.

    Note also where the file is headed. Editing pipelines often want MOV or ProRes, so exporting the delivery MP4 and keeping the MOV master is the correct split, not a compromise.

    How to Compress a MOV File on Windows with HandBrake

    HandBrake is the free, cross-platform default for MOV compression, and it is what most of the practical advice in this guide assumes.

    HandBrake Settings for a MOV File: Fast 1080p30 + Constant Quality RF 20–23

    Load the .mov into HandBrake, pick the Fast 1080p30 preset, then switch to the Video tab and set Constant Quality to RF 20–23 — RF 22 is the standard “preserve quality” choice. Set the container to MP4, choose an output location, and start the encode. A 4 GB 1080p source typically lands around 1.5–2 GB at CRF 22, though encoding speed depends heavily on your CPU.

    Use the queue to batch-process dozens of clips instead of repeating the settings dialog. That is the workflow the 200-clip marketing case implies, and it is the difference between a one-off fix and a repeatable process. For whole libraries of mixed media, bulk resizing photos and videos with a privacy-first tool follows the same batch logic.

    VLC’s Media → Convert/Save route works but cannot preview the output size before encoding, which makes it a fallback rather than a planning tool. For exact sizes and scripted batches, move up to FFmpeg; for clips already inside a timeline, Premiere Pro or DaVinci Resolve let you preview an estimated output size while you adjust encoder, bitrate, and resolution.

    A Mac Screen Recording MOV on a Windows PC: What Changes

    Cross-platform work exposes a gap most guides skip. A QuickTime screen recording made on a Mac plays on Windows only if the right codec is present, and installing playback patches treats the symptom. The cleaner fix is to transcode the file once to H.264 MP4 in HandBrake, which produces a file that plays natively and is already compressed to a sensible size.

    Windows users also encounter the “saved movie” case — a .mov downloaded or exported from another app, with no QuickTime ecosystem around it at all. The same HandBrake workflow applies.

    Online MOV Compressors: What the Free Tiers Actually Allow

    Browser-based compressors are convenient, but their limits change frequently and competing sources contradict each other. Verify on the official page before relying on any number below.

    The Dated Tool Comparison Table (Upload Cap, Watermark, Output, Privacy)

    Tool Free upload cap Watermark on free Notes Paid tier
    ScreenApp 2 GB No Encrypted in transit and at rest; no account required $19/month annual
    FreeConvert 1 GB Not stated Supports target size, quality, resolution, max bitrate $12.99/month
    Clideo 500 MB Yes No output format choice Not stated
    VEED 1 GB Yes — Not stated
    Adobe Express 1 GB Not stated 480p–4K output with a live size-estimate slider Free plan available
    FileReducer Guest 50 MB / Free 100 MB / Pro 1 GB / Business 2 GB No Files deleted after 1 hour / 24 hours / 30 days by tier Pro and Business
    Ezgif ~35 MB No Clip testing only —
    Clipchamp Conflicting: 20 GB vs 500 MB Not stated Sources disagree — check the official page —

    Caps and prices for ScreenApp, FreeConvert, Clideo, and VEED were checked by ScreenApp on 2026-09-12 and 2026-09-15. FileReducer’s tier structure and retention policy come from FileReducer (2026). Adobe Express supports files up to 1 GB with resolutions from 480p to 4K and updates an estimated output size as you move the compression slider — its example figures, such as turning a 1 GB drone video into a 90 MB MP4 or a 1 GB travel vlog into 180 MB, are vendor claims rather than independent tests.

    Two caveats worth stating plainly. First, unsupported audio codecs and HDR can make browser-based paths fail even when the file is under the size cap. Second, some third-party sites point two different product names at the same Clideo URL, so treat naming as unreliable.

    Why On-Device Compression Beats Uploading a 1 GB MOV

    Local browser compression avoids uploading your footage at all. SqueezeVid processes MOV up to 2 GB on your device and outputs an H.264 MP4, with a separate 10 GB browser beta at original resolution and a 10 GB server-side channel when uploading is acceptable. It uses FFmpeg in the browser, and it warns that memory-only browsers cap outputs at 512 MiB.

    The same source offers the most honest expectation-setting in this category: savings depend on the source video, duration, resolution, and bitrate, and already-compressed files may barely shrink.

    How to Compress a MOV File to a Target Size (and Why Email Usually Fails)

    Platform limits define the goal, so start there rather than at a quality setting. According to Uploadex, Gmail caps outbound attachments at 25 MB and Outlook at 20 MB.

    The Target-Size Formula (With a Worked Example)

    Target bitrate ≈ (target MB × 8 ÷ duration in seconds) − audio bitrate.

    For a 95 MB target on a 5-minute (300-second) video: 95 × 8 ÷ 300 ≈ 2,530 kbps total. Subtract 128 kbps for audio, and you have roughly 2,400 kbps for video. The same arithmetic works for a 500 MB web-upload cap or a 100 MB WhatsApp limit — each one produces a completely different bitrate budget.

    Two-Pass FFmpeg: Hitting an Exact Megabyte Count

    CRF cannot target a byte count, so exact sizes require two-pass encoding. The first pass writes statistics to a log; the second pass uses them with the calculated bitrate:

    ffmpeg -y -i input.mov -c:v libx264 -b:v 2400k -pass 1 -an -f null /dev/null
    ffmpeg -i input.mov -c:v libx264 -b:v 2400k -pass 2 -c:a aac -b:a 128k output.mp4
    

    Set expectations before you start encoding. If the file is only slightly over the limit, cut audio to 96–128 kbps and raise CRF by one or two points. If it is 40x over the limit, stop encoding and share a link instead — no quality-preserving compression turns a 4 GB MOV into an email attachment. As Surya Prakash of Uploadex notes: “If you’re compressing because you’re trying to email or share the file, compress less — or don’t compress at all — and use a file-sharing service with a download link.”

    Lossless, Visually Lossless, or Visible? How Much Quality Loss Is Acceptable

    Three tiers cover nearly every situation.

    True lossless codecs such as FFV1, HuffYUV, and Lagarith are reversible, but their compression ratios are far lower than lossy codecs — converting an already-compressed H.265 file to a lossless format actually makes it much larger. They belong in source-footage archiving, not delivery.

    Visually lossless is the practical target: CRF 18–22 for H.264, CRF 22–28 for H.265. These settings reduce file size considerably while producing output that looks identical to most viewers.

    Visible loss begins around CRF 28+, where blocking appears in motion and banding shows up in gradients and dark scenes.

    The rule that resolves most confusion: you can drop a high-bitrate source by around 80% without visible loss, but you cannot drop an already-compressed file by another 80%. As Uploadex puts it, there is no quality left to throw away.

    VP9 and AV1 offer better efficiency than H.265, but with slower encodes and narrower device support. Treat them as an advanced option, not a default recommendation.

    To judge your own output, pause on motion, dark, and gradient frames side by side. If you can spot the difference, back the CRF off by two points and re-run.

    Zip vs. Re-encode: Why Your Archive Didn’t Shrink

    Zipping a MOV does not meaningfully reduce it, because video is already compressed data — ZIP typically saves only a percent or two. Zip remains useful for bundling a master with project files — see how to zip a file on Mac and Windows — not for shrinking video.

    Does Compressing a MOV Reduce Audio Quality?

    Only if you lower the audio bitrate; the video codec you choose does not touch audio. AAC 128 kbps is fine for speech, while 192–256 kbps suits music-heavy content. Since audio is a small share of total size, cutting it rarely solves a size problem — keep it at 128 kbps minimum. Poor audio makes viewers perceive the video as worse than it actually is.

    Compressed but Still Too Big? Diagnose It in This Order

    Check 1 — did you actually re-encode, or just re-wrap? Remuxing a MOV into an MP4 container keeps the same bitrate and the same size. Codec is the lever that moves size; the container is cosmetic.

    Check 2 — was the source already compressed? A 5 Mbps MOV has almost no headroom left. According to Uploadex, an already-compressed 5 Mbps source only reaches about 3 or 2 Mbps, with slight loss in busy scenes. Verify the input bitrate before assuming the tool failed.

    Check 3 — did you change codec and CRF, or only the container and filename?

    Check 4 — is your target a hard platform limit? Gmail’s 25 MB and Outlook’s 20 MB are hard constraints, not soft goals. If that is the destination, switch strategy to a share link instead of squeezing further — the same workaround that gets large files past Discord’s 20MB file limit.

    Check 5 — are resolution and frame rate still untouched? Downscaling 4K to 1080p or 60 fps to 30 fps is the remaining lever once CRF and bitrate are optimized.

    Check 6 — did the export silently fall back to a default preset? Confirm the output’s actual resolution, codec, and bitrate rather than trusting the filename.

    Keep the Original as a Master: Verifying Your Compressed MOV

    The compressed file is a delivery copy. Keep the untouched MOV master on separate storage so you never re-compress an already-compressed file. That is exactly how the 800 GB → 120 GB marketing team reduction worked: masters stayed on a backup drive while only delivery copies were re-encoded.

    Verification follows four steps. Compress a 15-second sample of the busiest section at full resolution and watch it before rendering the whole clip. Compare motion, dark, and gradient scenes side by side, and if artifacts appear, raise quality by two CRF points and re-run. Check orientation on portrait footage and confirm small on-screen text is still readable. Then name the output with resolution, codec, and bitrate — product-demo_1080p_h264_8Mbps.mp4 — so a future replacement is a lookup rather than a guess.

    Verify a 15-second sample before encoding the full clip

    Store masters and delivery copies in separate folders with different backup rules: masters get redundancy, copies get deleted after the campaign.

    Conclusion

    How to compress a MOV file comes down to knowing what is inside the container. Re-encode ProRes or high-bitrate footage to H.264 at CRF 22 — or H.265 when size matters more than compatibility — and keep the original as a master.

    Diagnose your file first, pick the row in the decision table that matches your source and destination, run a 15-second sample, verify it at full size, then encode the full clip. HandBrake’s Fast 1080p30 preset with RF 20–23 handles most jobs; FFmpeg handles exact targets. And if the goal is a 25 MB email attachment, skip the squeeze entirely and send a share link.

    FAQ

    What is the best codec for compressing MOV files?

    H.264 is best for maximum compatibility and playback everywhere. H.265 (HEVC) delivers the smallest file at the same quality, which matters most for 4K and long clips. The trade-off: H.265 encodes slower and older devices may not play it. ProRes is a source codec, not a delivery codec.

    Should I convert MOV to MP4 when compressing?

    Yes for sharing, uploading, and email-size targets — MP4 is the most portable container and adds no extra quality loss. Keep MOV if the file is going back into an edit timeline or needs ProRes-class intermediate handling. Container choice does not change file size by itself; the codec and bitrate do.

    Can a MOV file be compressed without losing quality?

    Truly lossless codecs such as FFV1, HuffYUV, and Lagarith barely shrink the file, so they are archive-only. Visually lossless is the practical answer: CRF 18–22 for H.264, 22–28 for H.265. High-bitrate sources can drop about 80% with no visible change; already-compressed files cannot.

    Why is my compressed MOV file still too large?

    The most common cause is that the source was already compressed, leaving little quality to remove. The second is remuxing rather than re-encoding, which leaves the bitrate unchanged. The third is a hard cap like Gmail’s 25 MB — that calls for a share link instead of more compression.

    Does compressing a MOV file reduce audio quality?

    Only if you lower the audio bitrate; the video codec you choose does not touch audio. AAC 128 kbps is usually enough for speech and screen recordings, while 192–256 kbps suits music. Audio is a tiny share of total size, so keep it at 128 kbps minimum rather than cutting it to solve a size problem.

    Can I compress a MOV file on my phone?

    Yes — phone-side editors and share-sheet compression options handle short clips, and cloud tools accept uploads up to their free-tier cap. Expect less control: no CRF setting, limited codec choice, and often forced downscaling. For a 1 GB+ MOV, a desktop tool like HandBrake gives far more control over size and quality.

    Is zipping a MOV file an effective way to reduce its size?

    No — video is already compressed data, so ZIP usually saves only a percent or two. Zip is useful for bundling a master with project files, not for shrinking video. If a MOV must get smaller, re-encode it to H.264 or H.265 instead.